
An equity research team wants to deploy a large language model to assist analysts in synthesizing earnings call transcripts, 10-K filings, and sell-side research notes into comprehensive company summaries. A data scientist recommends retrieval-augmented generation (RAG) rather than fine-tuning a base model. What is the primary advantage of RAG in this earnings research context?
Select an answer to reveal the explanation.
Short Explanation
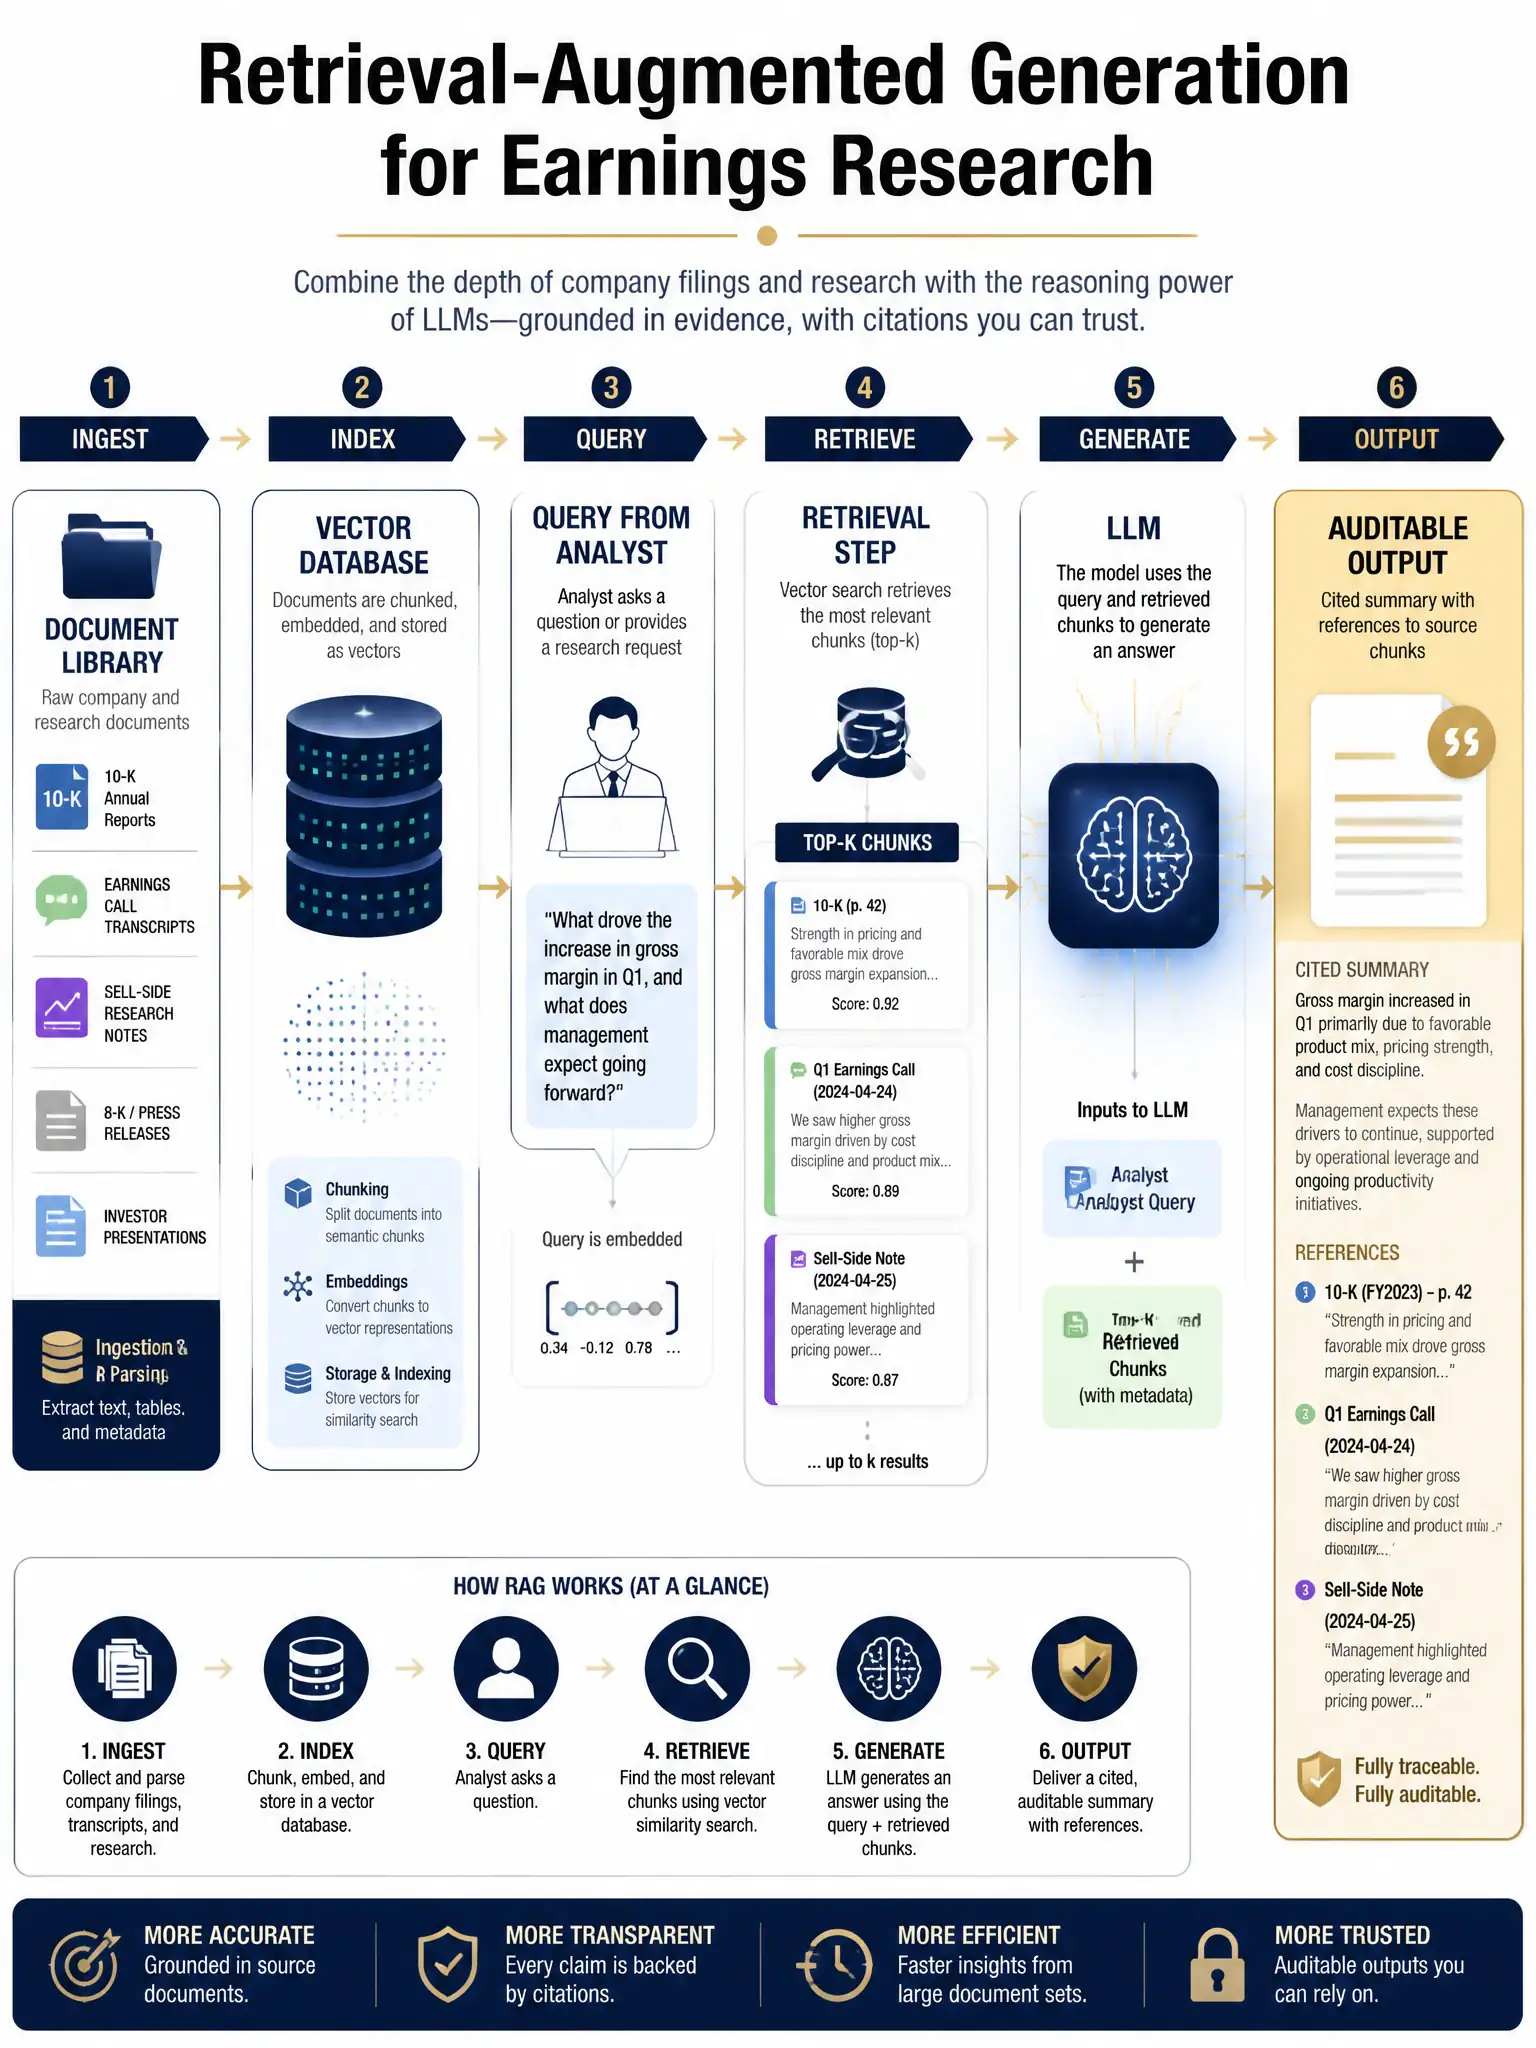
RAG gives you a live library card instead of forcing the model to memorize every filing. It retrieves the relevant transcripts and filings at query time, so summaries stay current, citable, and auditable as new earnings drop.
Full Explanation
Retrieval-augmented generation (RAG) addresses the fundamental limitation of static pre-trained language models in time-sensitive financial research: knowledge cutoff. A base LLM trained on data through a certain date cannot incorporate the Q3 earnings call that was published yesterday, the 8-K filed last week, or the revised sell-side consensus note from this morning. Fine-tuning could update model knowledge, but retraining on every new document is computationally prohibitive and introduces the risk of catastrophic forgetting — where new training degrades performance on previous knowledge.
RAG solves this by separating retrieval from generation. A vector database indexes all relevant financial documents — earnings transcripts, 10-K/10-Q filings, 8-Ks, sell-side notes — as embedding vectors. At query time, the analyst's question is embedded and used to retrieve the most semantically relevant document chunks, which are then injected into the model's context window alongside the query. The model generates its response grounded in those specific retrieved passages, which can be cited by document, page, and paragraph. This citation trail is essential in investment contexts where analysts and compliance teams need to audit the basis for any claim in a company summary. The primary advantage, therefore, is that RAG allows the model to ground its responses in specific, retrievable source documents — enabling citations, auditability, and dynamic updating as new filings become available — without retraining the model on each new document.
Additionally, RAG enables selective retrieval across firm-proprietary document repositories that should never be included in model training data due to confidentiality or regulatory restrictions — documents can be queried without being exposed to external model vendors through fine-tuning pipelines. The claim that RAG eliminates the need for any human review because retrieved documents guarantee factual accuracy misunderstands RAG: retrieved documents constrain hallucination significantly but do not eliminate it — models can still misinterpret or selectively emphasize retrieved passages, so human review remains mandatory. The claim that RAG permanently stores all retrieved documents inside the model weights, creating a proprietary knowledge base that cannot be accessed by competitors, confuses RAG with fine-tuning; retrieved documents live in an external index, not in model weights, and are fully accessible to administrators. The claim that RAG is superior to fine-tuning because it produces higher-quality prose and more fluent language than base models, regardless of the retrieval quality, is incorrect: prose fluency is a function of the base model, not the retrieval mechanism.