
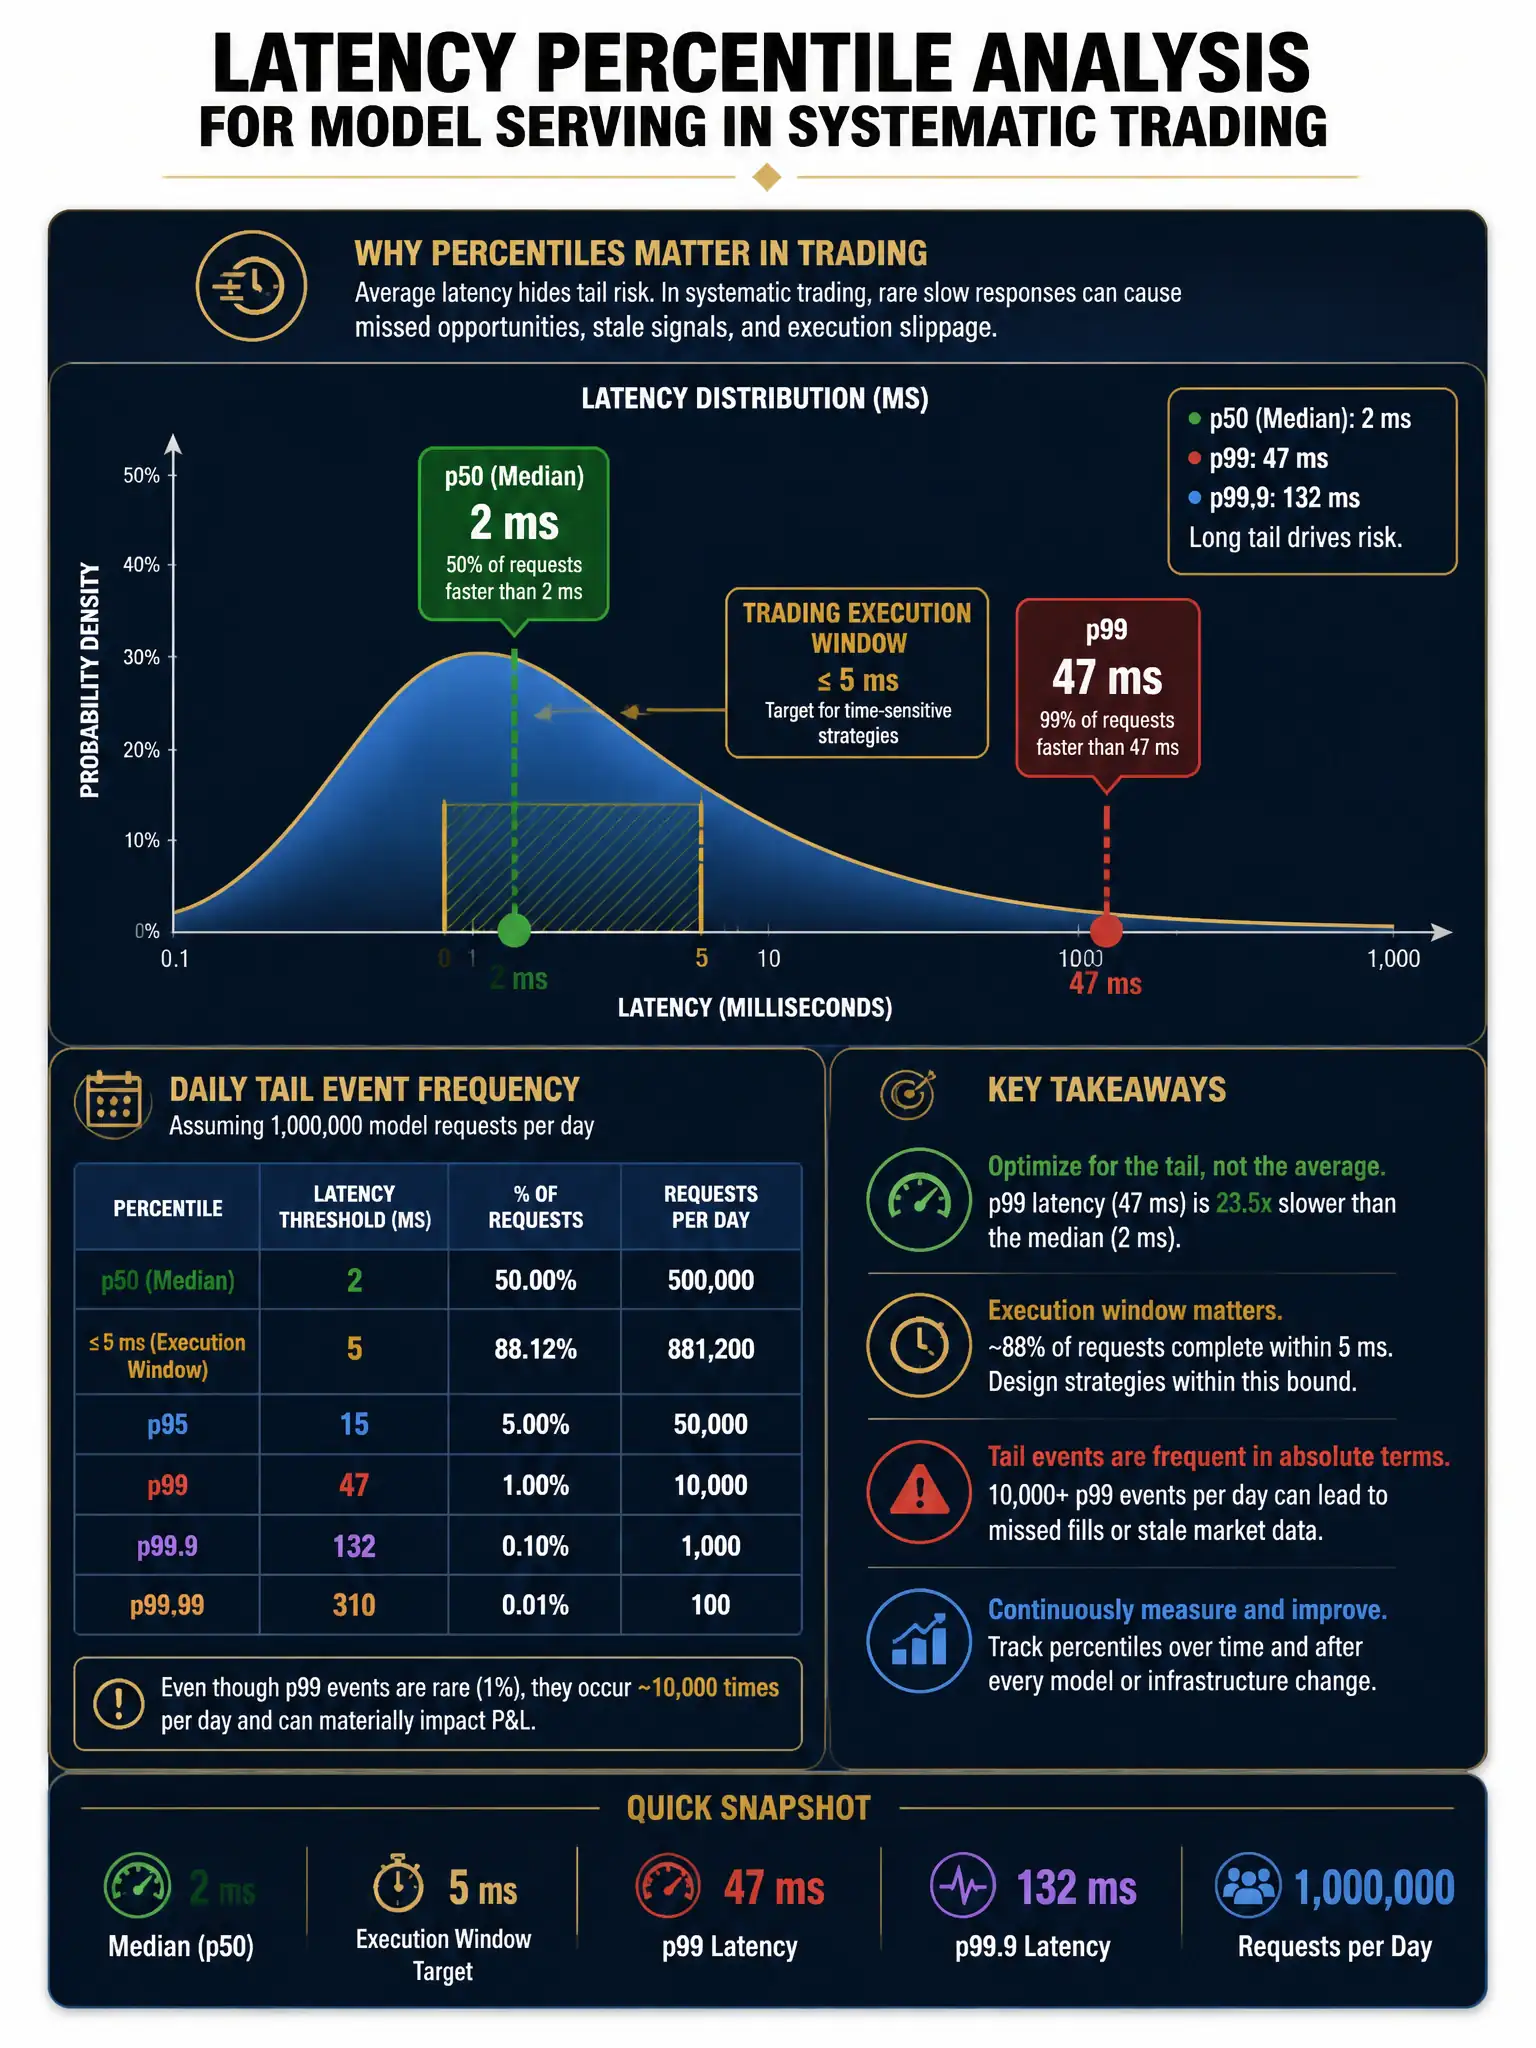
A systematic equity fund is procuring a third-party model serving infrastructure for its intraday mean-reversion signals. The execution team specifies that any signal latency above 5 milliseconds end-to-end will result in adverse fill rates that negate the edge. The vendor's benchmark shows p50 latency of 2ms and p99 latency of 47ms. How should the fund interpret this performance profile?
Select an answer to reveal the explanation.
Short Explanation
Todd Lammle: In low-latency trading, the 99th percentile is like the slowest runner on a relay team — it's the one that loses the race. The 2ms median sounds great until you realize that 1-in-100 signals come back at 47ms, which in high-frequency mean-reversion is a miss, not a delay. The 99th-percentile profile identifies the tail-latency problem that actually determines live performance.
Full Explanation
In high-frequency and systematic trading infrastructure, tail latency — specifically the 99th and 99.9th percentile — is the operationally decisive metric, not the median. When the fund generates thousands of signal events per day, a p99 of 47ms means that roughly 10 events per 1,000 signal evaluations will return results after the execution window closes. For mean-reversion strategies that depend on catching transient price dislocations within milliseconds, a 47ms tail latency event is functionally equivalent to a missed trade. The correct interpretation is that the p99 latency of 47ms indicates that 1% of all inferences will exceed the 5ms threshold by nearly 10x, which at high signal frequency represents a material edge-degrading event rate.
The p50-only interpretation reflects a common misunderstanding of performance statistics. The p50 describes the typical case; SLA design for latency-sensitive applications must be anchored to the tail. Quantitative trading teams at firms like Two Sigma, DE Shaw, and Renaissance Technologies consistently design SLAs around p99 and p99.9 thresholds, not medians.
The throughput-only proposal incorrectly proposes replacing latency with throughput. While throughput (signals per second) is a valuable scaling metric, it does not capture the time-to-result distribution that determines execution quality. High-throughput systems can have terrible tail latency.
The force majeure waiver is both legally and operationally problematic. Tail latency caused by garbage collection spikes, network jitter, or resource contention is a predictable, engineerable characteristic of distributed systems — not a force majeure event. Waiving it contractually removes the vendor's incentive to optimize and exposes the fund to uncapped performance risk.
CFIA candidates should understand the distinction between p50, p95, p99, and p99.9 latency percentiles, and be able to calculate the practical daily frequency of tail events from signal volume and percentile thresholds.