
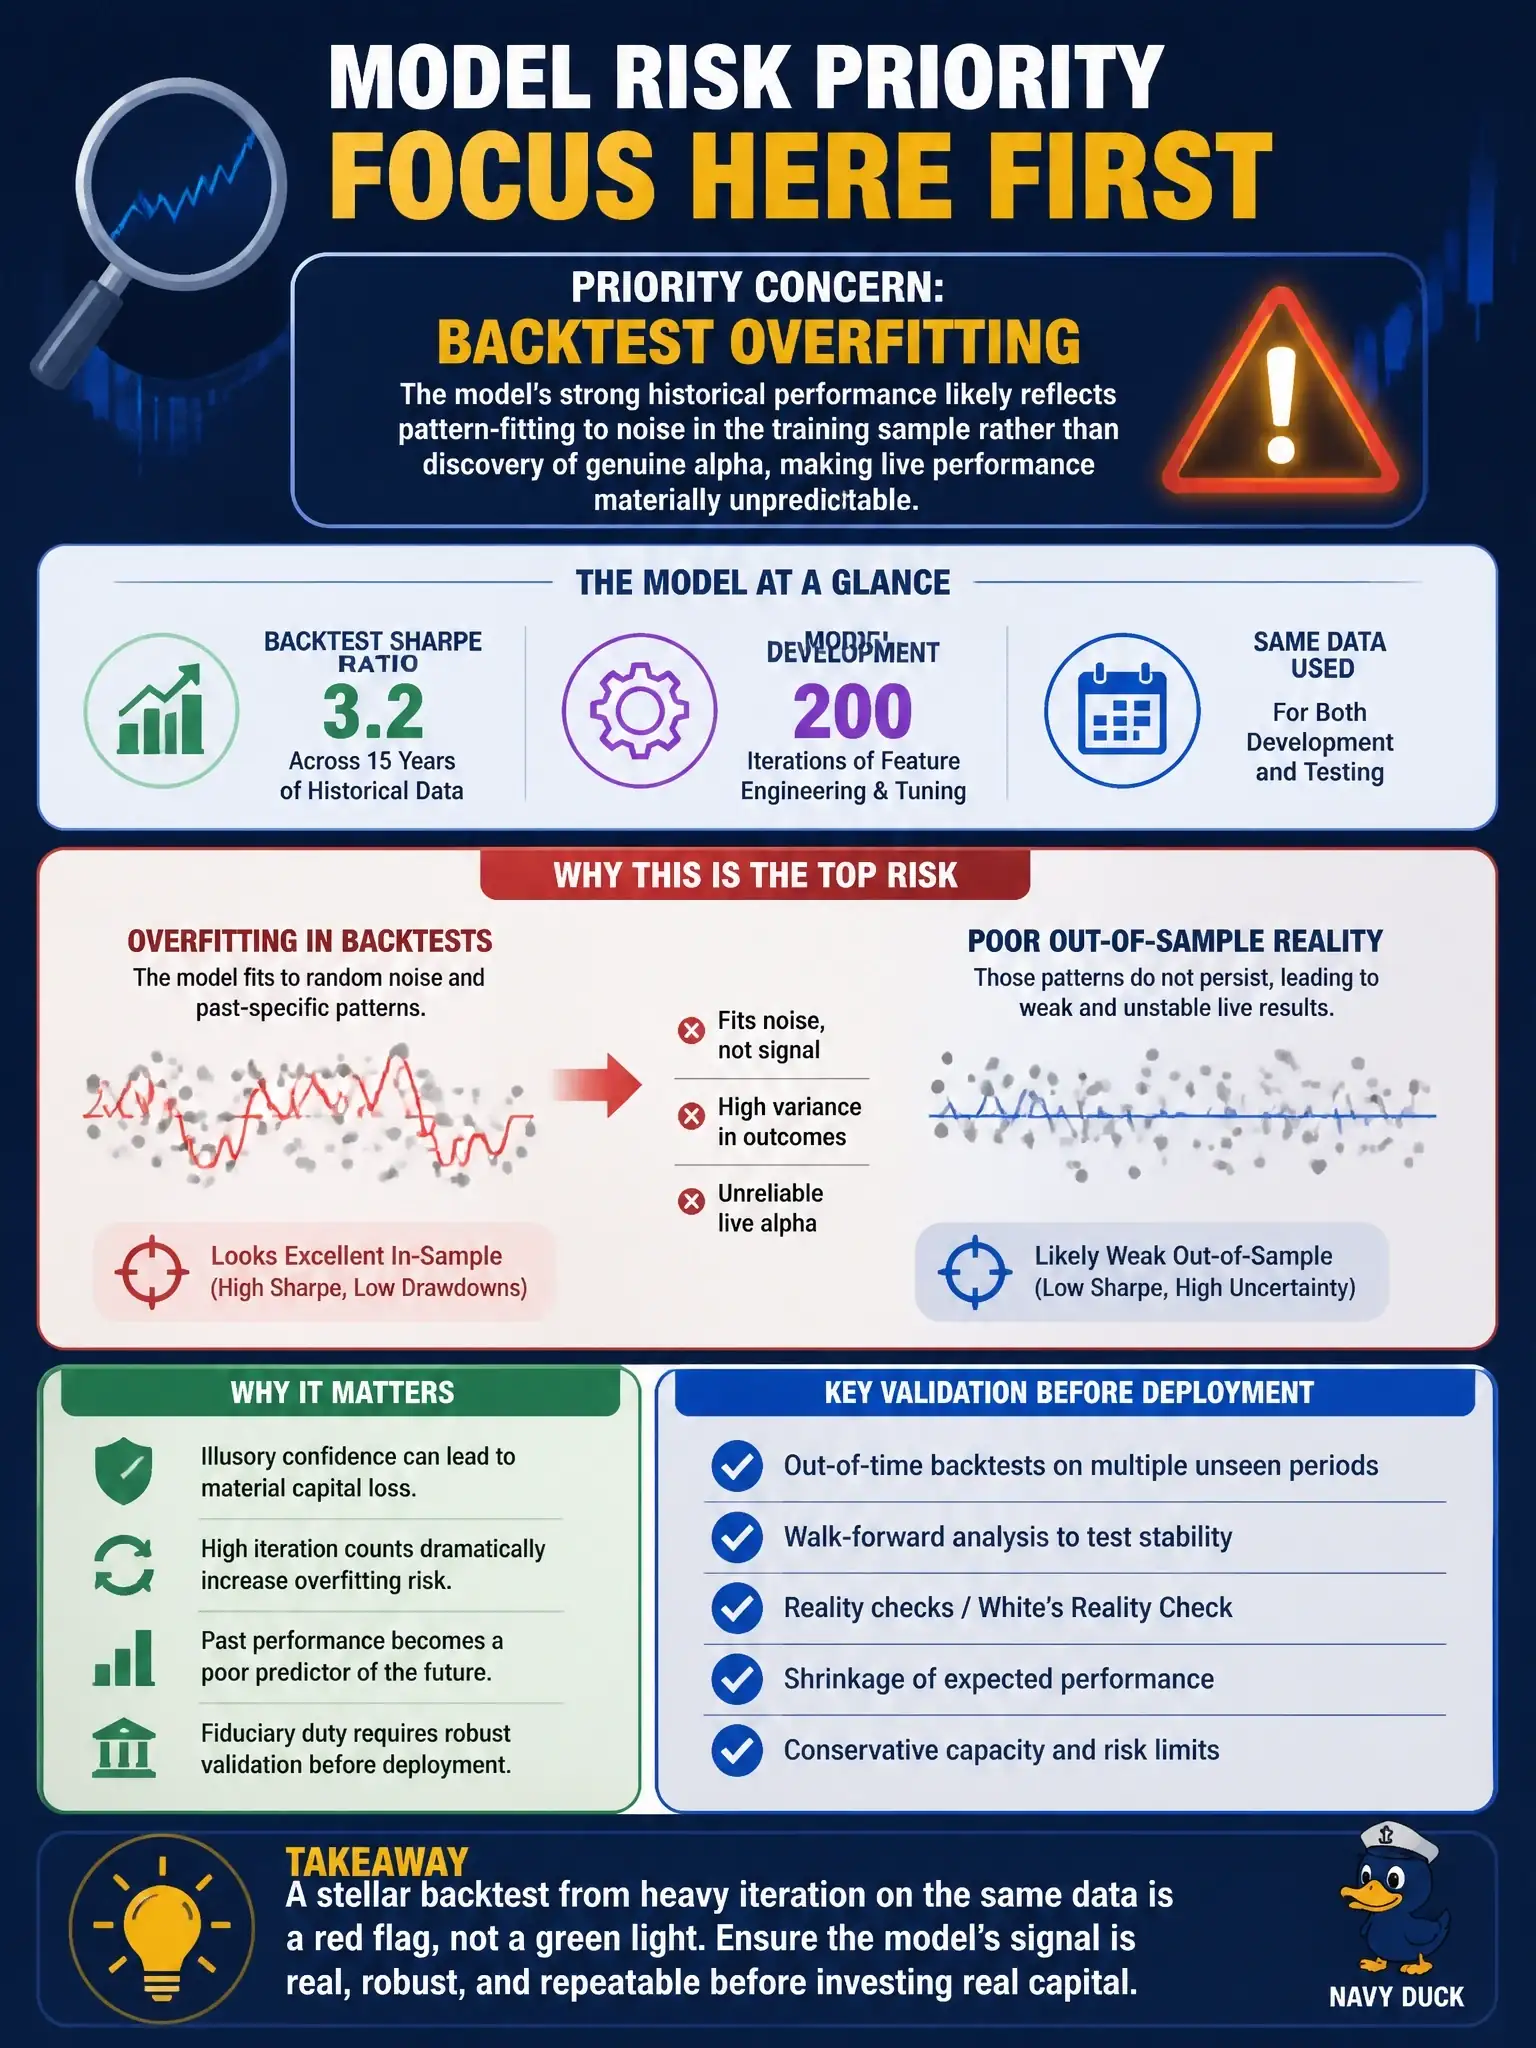
A quantitative portfolio manager presents a new AI alpha signal that achieved a Sharpe ratio of 3.2 in backtesting across 15 years of historical data. The model was developed through 200 iterations of feature engineering and parameter tuning on this same dataset. From a model risk management perspective, which concern should the risk committee prioritize before approving live deployment?
Select an answer to reveal the explanation.
Short Explanation
Here's the deal: two hundred tweaks on the same 15 years of data is a textbook recipe for backtest overfitting. You can fit almost any pattern into historical noise by accident, so you're seeing a memorized exam, not a real edge. You need untouched out-of-sample data before you put client capital at risk.
Full Explanation
Backtest overfitting — also called data snooping, multiple hypothesis testing bias, or in-sample overfitting — is one of the most serious model risks in quantitative investment management. It occurs when a model is developed through repeated iteration on the same historical dataset, effectively learning the idiosyncratic noise of that sample as if it were signal. The result is inflated in-sample performance metrics that do not generalize to new data.
The statistical relationship here is well-established: Harvey, Liu, and Zhu (2016) demonstrated that for strategies tested on financial data, the minimum acceptable t-statistic for a claimed factor should be at least 3.0, accounting for the number of tests performed. With 200 iterations of feature engineering and tuning on the same dataset, the effective p-value threshold has been drastically eroded — a Sharpe of 3.2 achieved through this process provides very weak statistical evidence of genuine alpha.
From a regulatory standpoint, SR 26-2 (which superseded SR 11-7 in April 2026), the Federal Reserve, OCC and FDIC model risk management guidance, describes out-of-sample and out-of-time testing during development and back-testing as part of outcomes analysis. Sound validation here includes: (1) a true hold-out test set that was never touched during development; (2) walk-forward out-of-sample testing; (3) transaction cost modeling; and (4) sensitivity analysis across market regimes. The absence of any out-of-sample validation is a material gap.
The concern that the Sharpe ratio calculation methodology may not align with SEC reporting standards for performance claims is a disclosure question, not a model integrity question. The concern that the 15-year lookback period does not include sufficient market stress scenarios to validate performance in tail-risk environments raises a valid secondary concern about stress-testing coverage, but it is a refinement issue rather than the foundational validity problem. The concern that the model may incorporate non-public information in historical market data, creating insider trading regulatory exposure, would be a serious legal issue but is not the risk indicated by the described development process.
The risk committee should require the development team to conduct genuine out-of-sample evaluation on data that was fully sequestered before development began, and apply statistical adjustment methods (such as the Bailey-López de Prado minimum backtest length formula) to set appropriate performance thresholds given the number of trials conducted.