
A large hedge fund has built its AI-powered signal generation pipeline entirely on a single proprietary LLM provider's API. The vendor announces a 40% price increase and a policy change that restricts financial output caching — a feature the fund relies on for latency optimization. The Head of Technology asks the CFIA-credentialed architect to present a vendor lock-in mitigation strategy to the risk committee. Which approach BEST reduces strategic dependency while maintaining operational continuity?
Select an answer to reveal the explanation.
Short Explanation
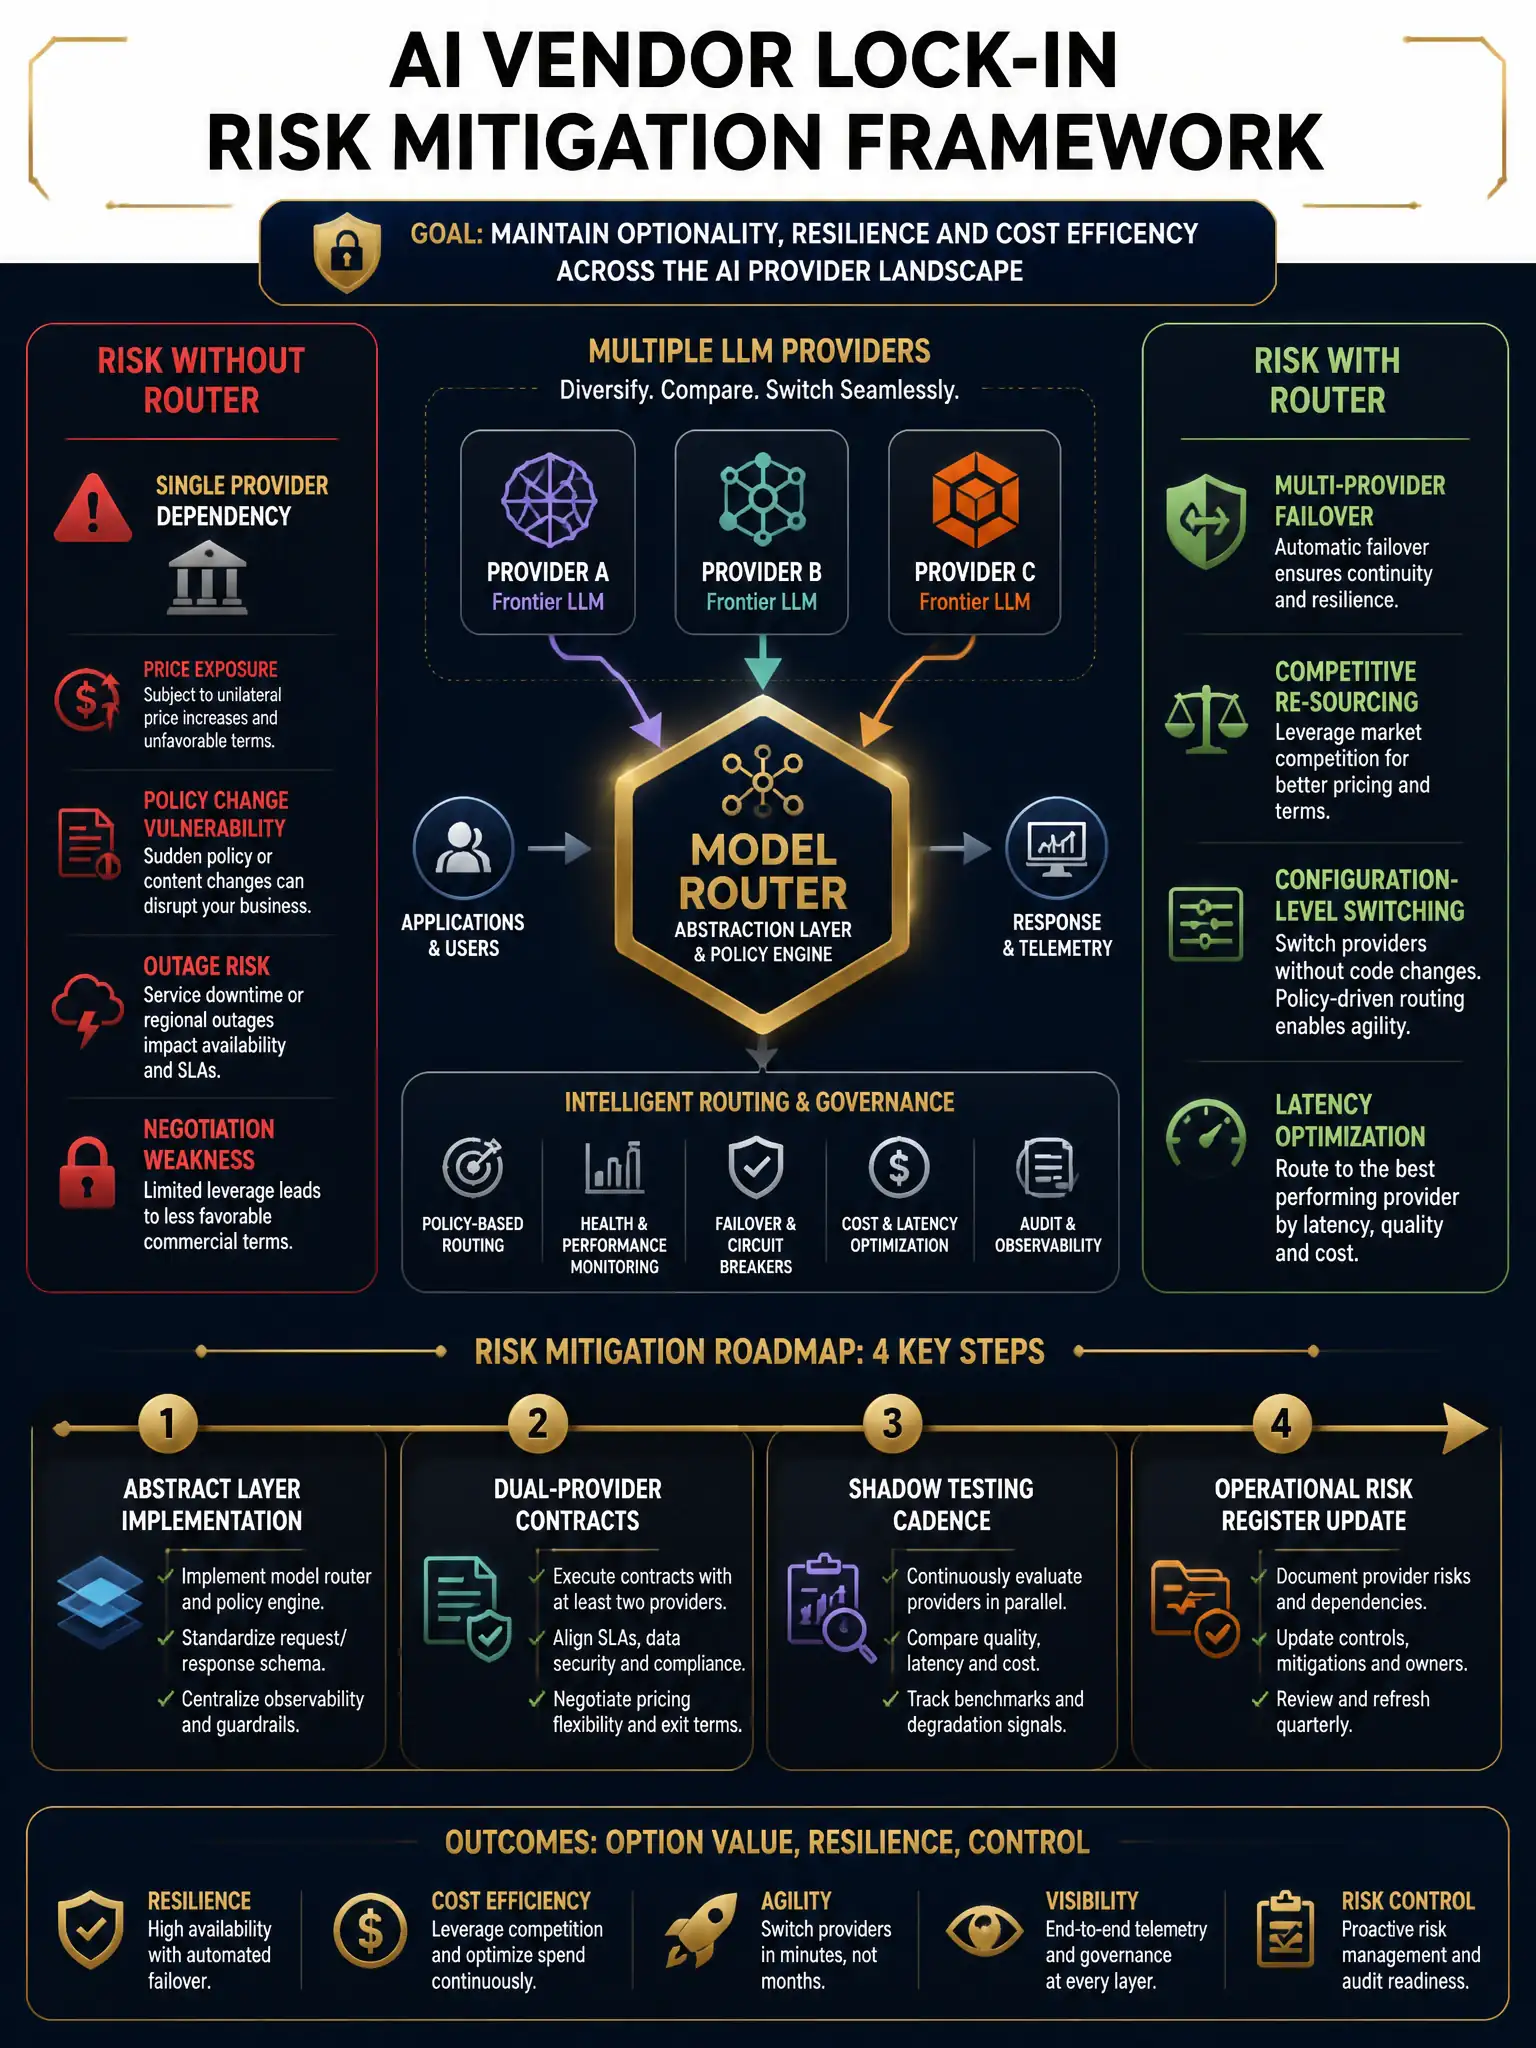
You don't want one vendor holding your alpha hostage. Route inference requests through a model router so your business logic isn't married to one provider. That lets you fail over or re-source models without rewriting the pipeline.
Full Explanation
Vendor lock-in in AI infrastructure is structurally similar to single-counterparty concentration risk in a portfolio — it creates asymmetric downside with limited upside. When a firm's entire signal generation pipeline depends on one provider's API, it loses negotiating leverage, becomes exposed to unilateral policy changes, and faces operational disruption if the provider experiences outages or changes its terms. For a hedge fund where latency and reliability directly affect alpha generation, this is a material operational risk.
The correct approach is implementing a provider-agnostic abstraction layer, often called a model router or LLM gateway, with examples such as LiteLLM, PortKey, or custom-built orchestration layers. This layer standardizes how prompts are constructed, how responses are parsed, and how errors are handled, regardless of which underlying model provider fulfills the request. The firm's application code calls the router, and the router handles provider-specific API formats, authentication, and retry logic. Switching from one provider to another becomes a configuration change, not a pipeline rewrite.
Effective lock-in mitigation also includes maintaining parallel contracts with at least two providers; running periodic shadow-testing of alternative models against production workloads so the team understands performance parity before a crisis forces a switch; and including AI vendor concentration as a named risk category in the firm's operational risk framework.
The approach of immediately migrating all workloads to an open-source model to eliminate vendor dependency before the price increase takes effect is incorrect because it introduces new operational risk and ignores the performance validation required for a signal generation system. The approach of negotiating a volume discount with the current vendor and documenting the arrangement in the investment policy statement as a risk control is incorrect because it addresses pricing but does nothing to reduce dependency, leaving the fund fully locked in. The approach of accepting the price increase and policy change as unavoidable, on the premise that switching costs for LLM providers are universally prohibitive in financial services environments, is factually wrong; while switching costs exist, they are manageable with proper abstraction layer architecture and are far lower than the long-term cost of vendor-imposed constraints.