
A fixed income research team is evaluating transformer-based language models for automated analysis of 10-K filings, earnings call transcripts, and Fed minutes. The lead quant architect explains that transformers process these documents fundamentally differently from earlier recurrent neural network (RNN) approaches. Which characteristic of the transformer self-attention mechanism is most directly responsible for its superior performance on long financial documents compared to RNNs?
Select an answer to reveal the explanation.
Short Explanation
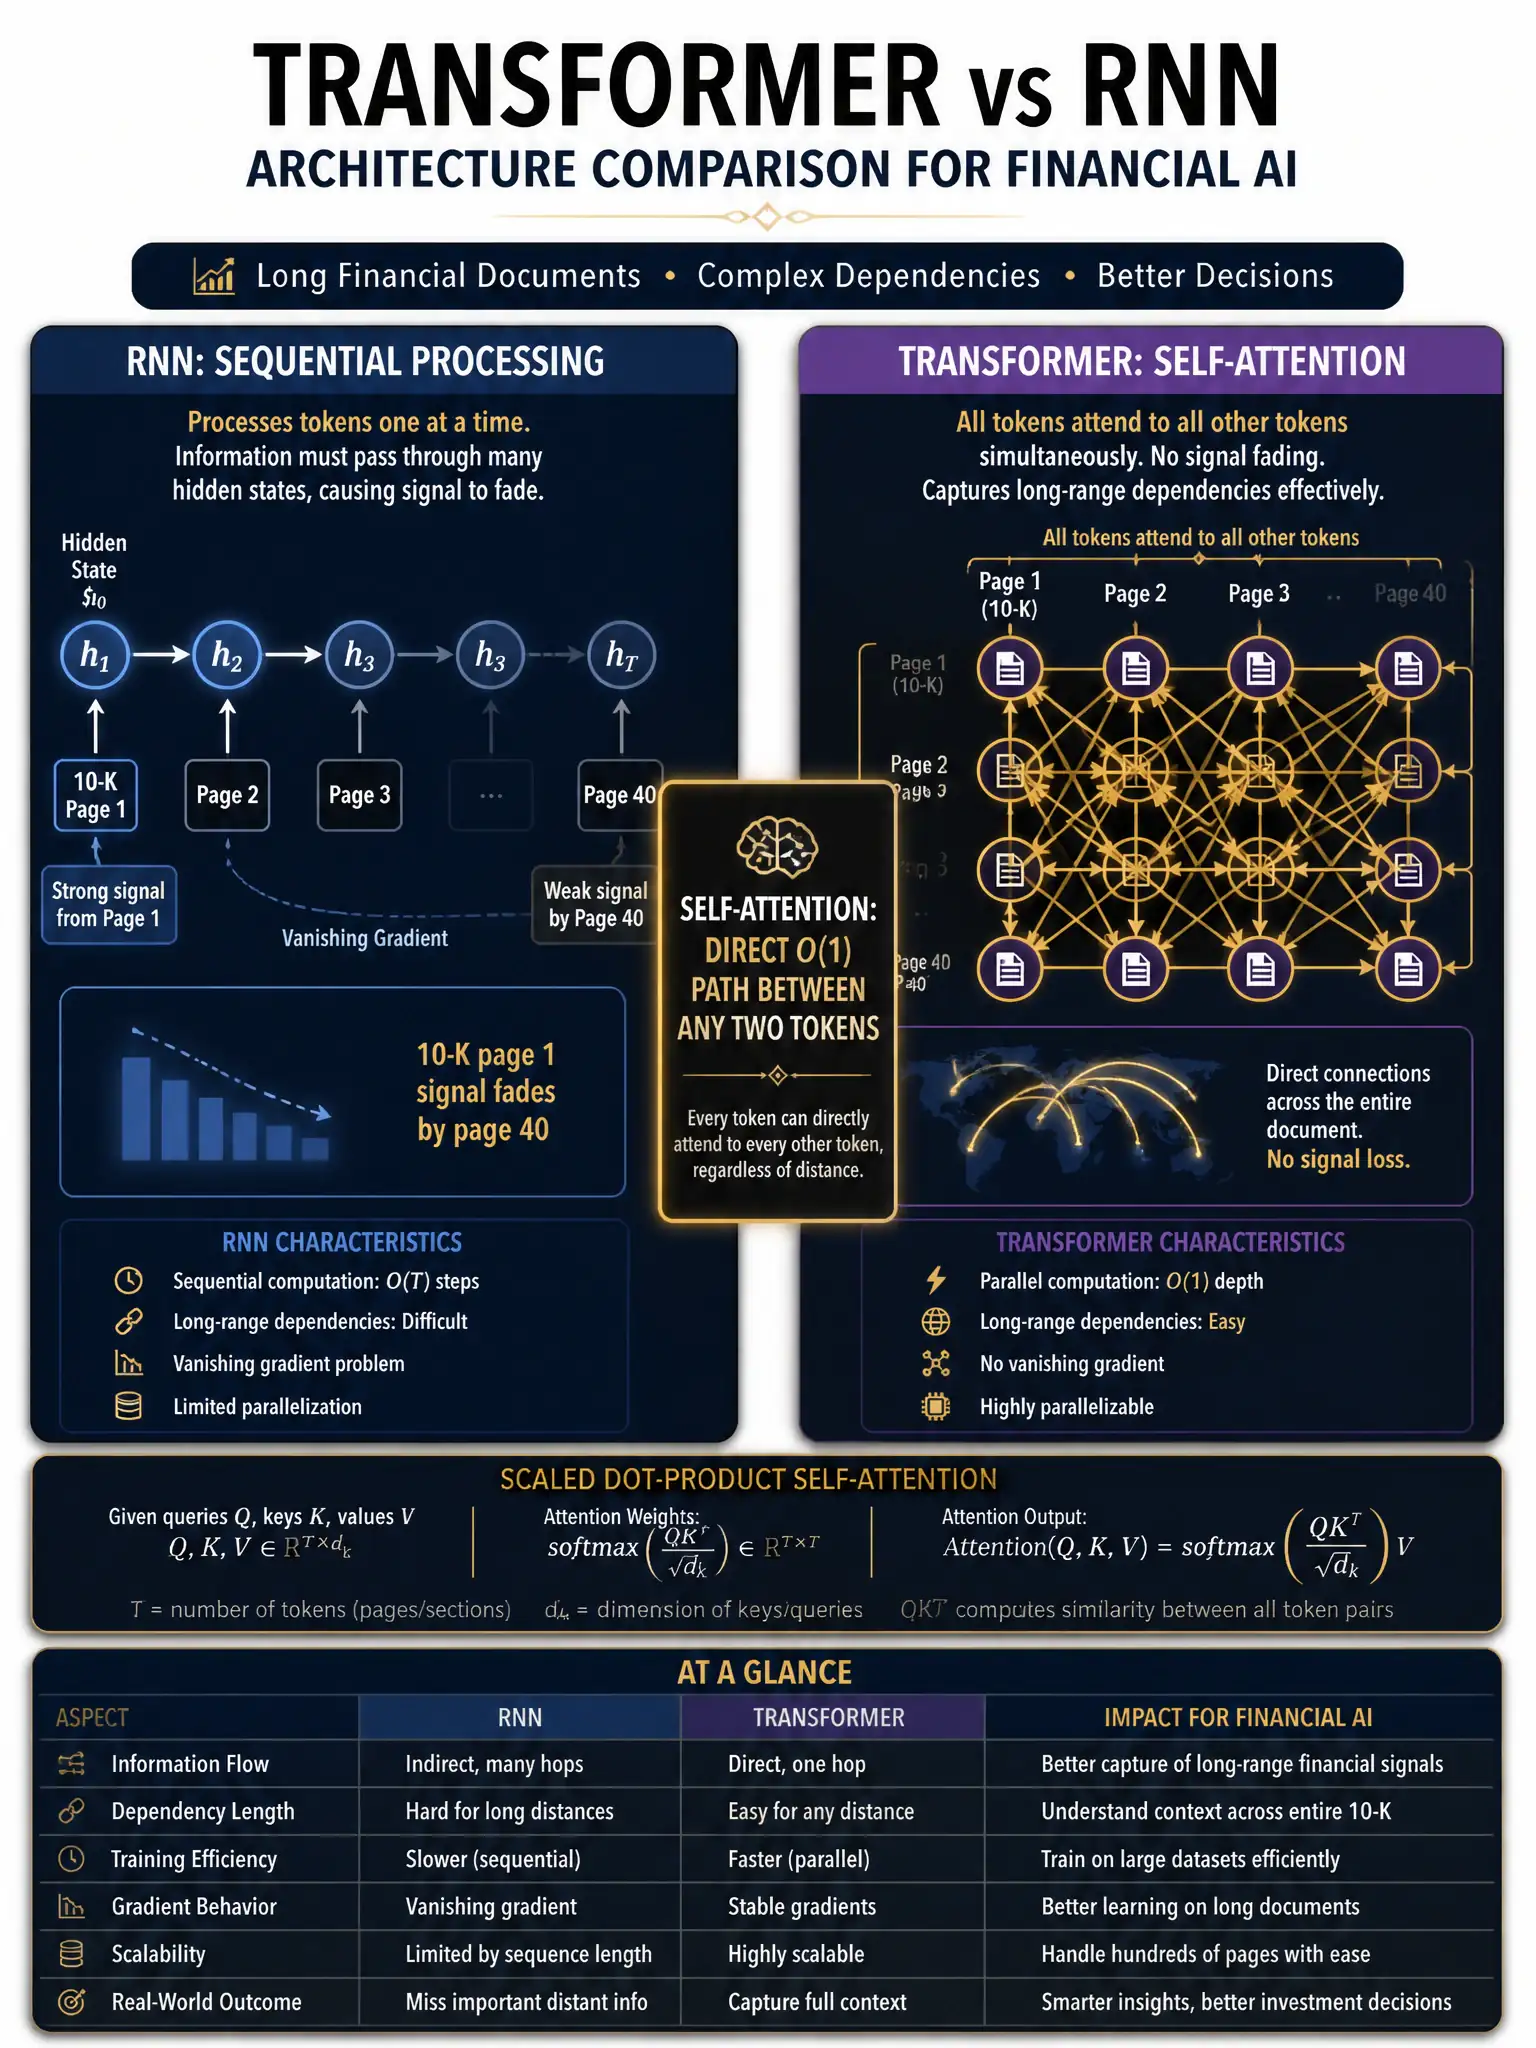
Think about how you read a 10-K: you don't lose page 1 by page 40. Self-attention lets every token directly check every other token in parallel, so long-range financial dependencies don't fade like they do in RNNs.
Full Explanation
The characteristic most directly responsible is that transformers process all tokens in parallel with direct pairwise attention weights between any two positions, eliminating the vanishing gradient problem that prevents RNNs from capturing long-range dependencies in documents. The transformer architecture, introduced by Vaswani et al. (2017) in 'Attention Is All You Need,' replaced the sequential processing paradigm of RNNs and LSTMs with a parallel multi-head self-attention mechanism. The core mathematical operation computes attention weights between every pair of tokens in a sequence simultaneously using query-key-value matrices. This has two critical consequences for financial document processing. First, the vanishing gradient problem that plagued RNNs — where gradients decay exponentially as they backpropagate through sequential time steps — is eliminated because there is no sequential recurrence. Every token position has a direct gradient path to every other position through the attention weight matrix. This means a model trained on 10-K filings can learn that the word 'restatement' on page 45 is semantically connected to 'revenue recognition' on page 3, a dependency that an LSTM with hidden state size 512 would struggle to maintain across 40 pages of tokens. Second, parallel processing of all tokens enables much more efficient training on large financial corpora. Financial-specific transformer models — FinBERT, BloombergGPT, and similar — leverage this to learn domain-specific semantic relationships (e.g., 'impairment' carries different weight near 'goodwill' versus 'hearing') that general-purpose models miss. The convolutional-filter claim describes convolutional neural networks, not transformers. CNNs use local receptive fields and are less effective at long-range document-level dependencies. The fixed-length hidden-state claim describes the encoder architecture of older seq2seq models (Sutskever et al., 2014) with fixed-length bottleneck vectors — a limitation that transformers explicitly solved with their variable-length attention representation. The reinforcement-learning-from-human-feedback claim describes RLHF (Reinforcement Learning from Human Feedback), which is a fine-tuning technique, not a property of the transformer architecture itself. RLHF operates on top of a pre-trained transformer, not as part of its core processing mechanism.