
A program manager is launching an agent that drafts customer emails, summarizes contracts, and proposes refunds up to a threshold. The pilot must protect fairness, transparency, and accountability across regions. Which action should the manager take to apply Responsible AI principles to agent use before scaling?
Select an answer to reveal the explanation.
Short Explanation
You're adding guardrails before hitting the highway. Human-centered oversight keeps fast drafts fair and traceable. It's like requiring a co-signature on checks while training a new clerk.
Full Explanation
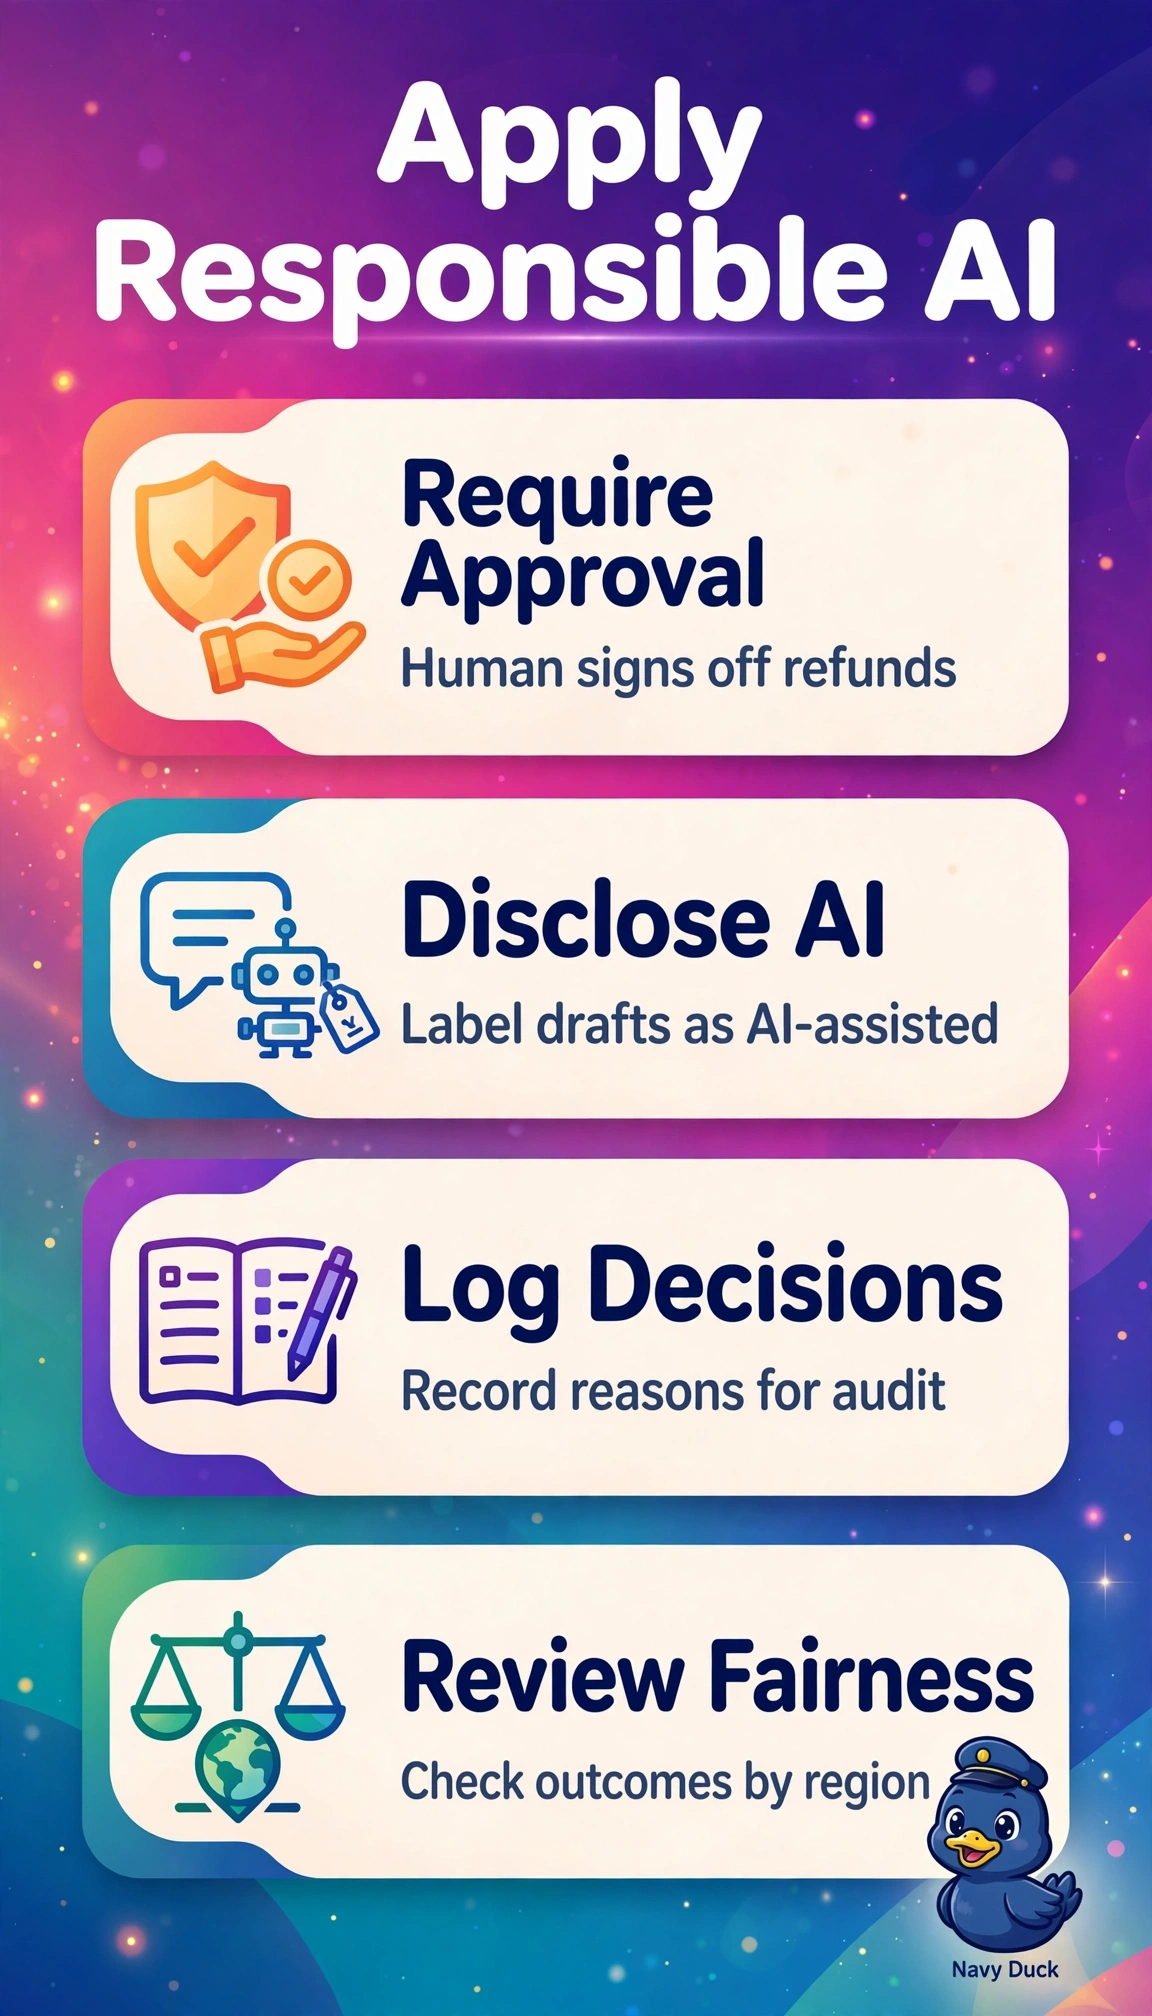
The correct action integrates all three Responsible AI pillars for this pilot because human approval for financial proposals preserves accountability and provides a control point before impact, customer-facing disclosure of AI drafts satisfies transparency so recipients can interpret and correct outputs like summaries, and centralized logging of decisions with prompts and outcomes enables fairness review across regions to detect disparate patterns before scaling. Auto-approving refunds under the threshold even with disclosure and logging fails on oversight because efficiency does not substitute for human accountability for financial harm and reversibility, a standard exam trap where a plausible throughput optimization violates the stated approval need. Retaining logs regionally only for troubleshooting fails on governance because operational debugging lacks defined fairness metrics, retention, and cross-regional aggregation needed for accountability and bias detection. Noting AI use only internally fails on transparency because internal documentation does not inform the affected customer relying on the draft or summary, undermining informed reliance and redress. The exam caveat is to select the response that satisfies every stem requirement rather than the most operationally efficient or familiar practice, as questions often include two of three controls to test completeness. As a practical check, confirm the pilot has an approval queue for refunds, visible AI labeling in customer messages, and a queryable central log that a reviewer can sample by region and outcome for fairness analysis.