
An orchestrator manages a pipeline where Agent B typically completes in under 10 minutes. On a production run, the orchestrator does not receive a completion signal from Agent B after 45 minutes. The orchestrator cannot determine if Agent B is still working slowly, has crashed silently, or is stuck in an infinite loop. Which detection mechanism would enable the orchestrator to reliably identify and respond to a stalled Agent B?
Select an answer to reveal the explanation.
Short Explanation
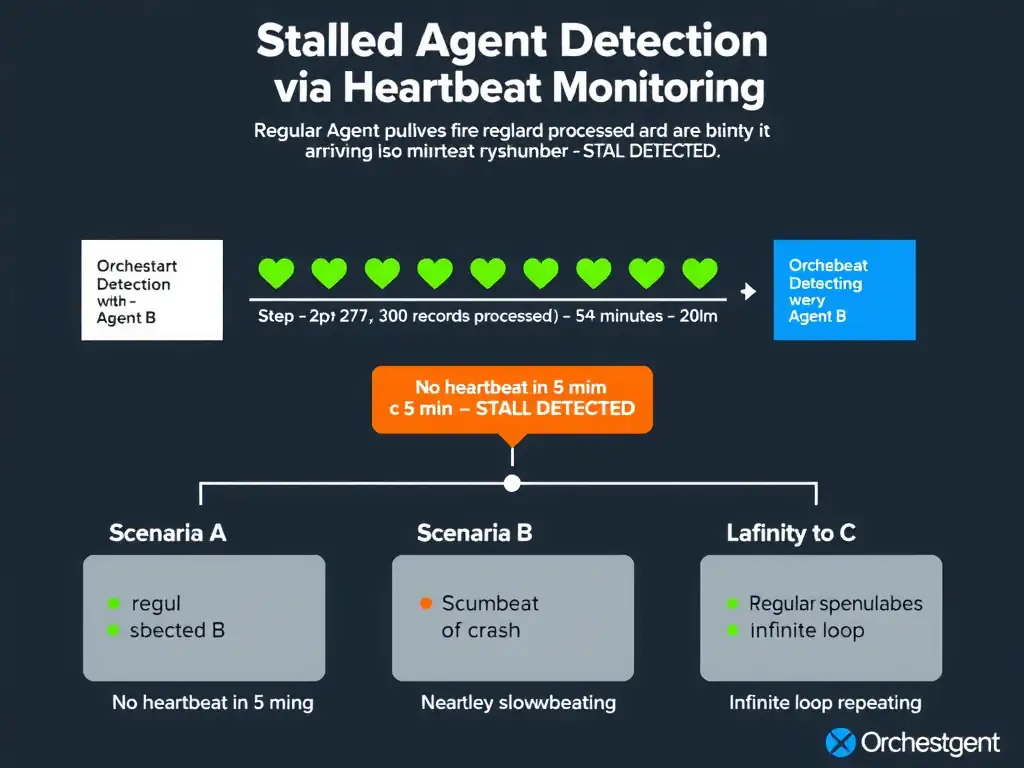
You need a heartbeat from the agent, not a blind timeout. If it checks in every couple of minutes with progress, silence for five minutes tells you it's stalled. That lets you tell slow work from a dead or looping process.
Full Explanation
The core challenge is distinguishing three failure modes that are externally indistinguishable without additional instrumentation: working slowly but correctly, a silent crash, and an infinite loop. A heartbeat mechanism differentiates these. If heartbeats are missing, the agent has likely crashed or is looping without reporting progress, so the orchestrator triggers a stall response. If heartbeats are present with advancing progress, the agent is working slowly but correctly, so the orchestrator waits. If heartbeats are present but progress is not advancing, the agent is stuck in an infinite loop at a fixed step, so the orchestrator triggers a stall response. The heartbeat payload, such as the current step and records processed, makes the mechanism multi-dimensional rather than just a liveness check. The hard-deadline approach eliminates ambiguity by force, but it terminates legitimate slow runs. If the agent occasionally takes fourteen minutes for large datasets, a fifteen-minute deadline creates frequent false positives that break valid pipelines. The output-polling comparison approach cannot detect stalls where the agent is producing output but not progress, such as writing the same log message in an infinite retry loop. It also adds a dependency on being able to read the agent's intermediate output, which may not be architecturally available. The auto-scaling restart approach handles crash detection at the infrastructure level, but it does not inform the orchestrator, does not detect infinite loops because the process is running, and does not preserve the stall context needed for the orchestrator to decide how to respond, such as escalate, retry, or fail the pipeline.