
A multi-agent pipeline processes large-scale data transformation tasks. Agent A (Extractor) retrieves data from an upstream source and passes control to Agent B (Transformer). In production, Agent A occasionally fails mid-run, and the pipeline must be restarted with Agent B picking up from where Agent A left off. Currently, Agent B receives only the raw output of Agent A, but when Agent A fails mid-run, Agent B does not know which records were successfully extracted and which were not. Which handoff documentation design would BEST enable Agent B to resume accurately?
Select an answer to reveal the explanation.
Short Explanation
If you hand off 'some data' with no manifest, you're passing a baton while shouting 'figure out the rest.' A structured handoff document is the GPS coordinates: here's exactly what was done, what wasn't, and where to pick up. That lets the transformer skip completed records and resume cleanly.
Full Explanation
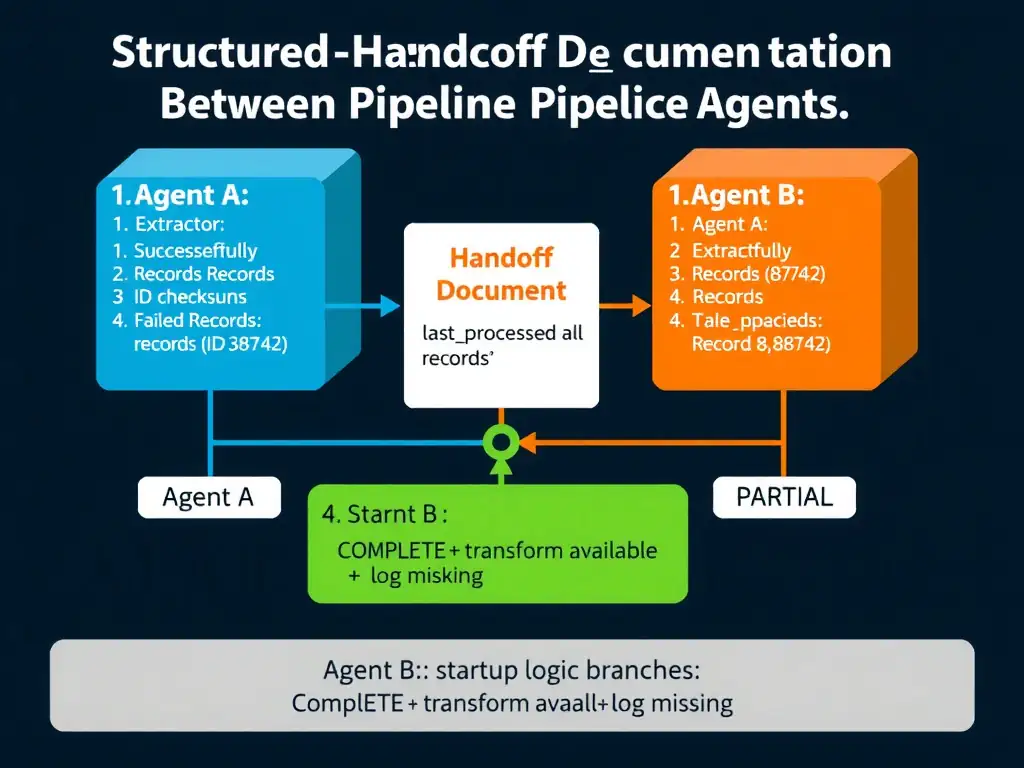
Handoff documentation is a critical pattern for multi-agent pipelines that must be resilient to partial failures. The handoff document serves as the contract between the upstream extractor and the downstream transformer:
Required handoff document contents: 1. Successfully extracted records: a list of record IDs with checksums, proving the records the transformer receives are complete and unmodified 2. Failed or unattempted records: an explicit list of records that were not successfully extracted, so the transformer can flag or re-request them rather than silently producing a partial transform 3. Cursor position: the last processed position in the upstream source, such as last page number, last record timestamp, or last offset. This is the precise resume point. 4. Status flag: COMPLETE or PARTIAL — the transformer's logic branches differently. For a COMPLETE handoff, the transformer transforms all records. For a PARTIAL handoff, the transformer transforms available records and logs a warning about missing records.
The approach that requires the extractor to always complete a full extraction before passing to the transformer, using retry logic to handle transient failures, is not always feasible — upstream source failures, rate limits, or infrastructure timeouts may prevent completion regardless of retry count. Retry loops with hard failure modes do not eliminate the need for graceful partial handoffs.
The approach where the transformer queries the upstream source directly to re-extract all records, ignoring the extractor's partial output, is correct in one scenario (small dataset, idempotent extraction) but wastes work for large datasets where the extractor successfully extracted 90% of records before failing. It also assumes re-extraction is possible, which may not be true for streaming sources.
The approach with a shared counter that the extractor increments for each successfully extracted record provides a resume point but not a record-level manifest — the transformer knows to start at record 1,001 but does not know which specific records 1-1,000 were extracted successfully. Records extracted out of order would produce incorrect offset semantics.