
A team improves their documentation-generation agent's output for a specific type of API function by updating the system prompt. After the update, documentation quality for that function type improves significantly. Two weeks later, the team receives bug reports that the agent has stopped generating parameter descriptions for a different function type that was working correctly before the prompt change. The team never ran evaluation against the second function type after making the prompt change. What process was missing?
Select an answer to reveal the explanation.
Short Explanation
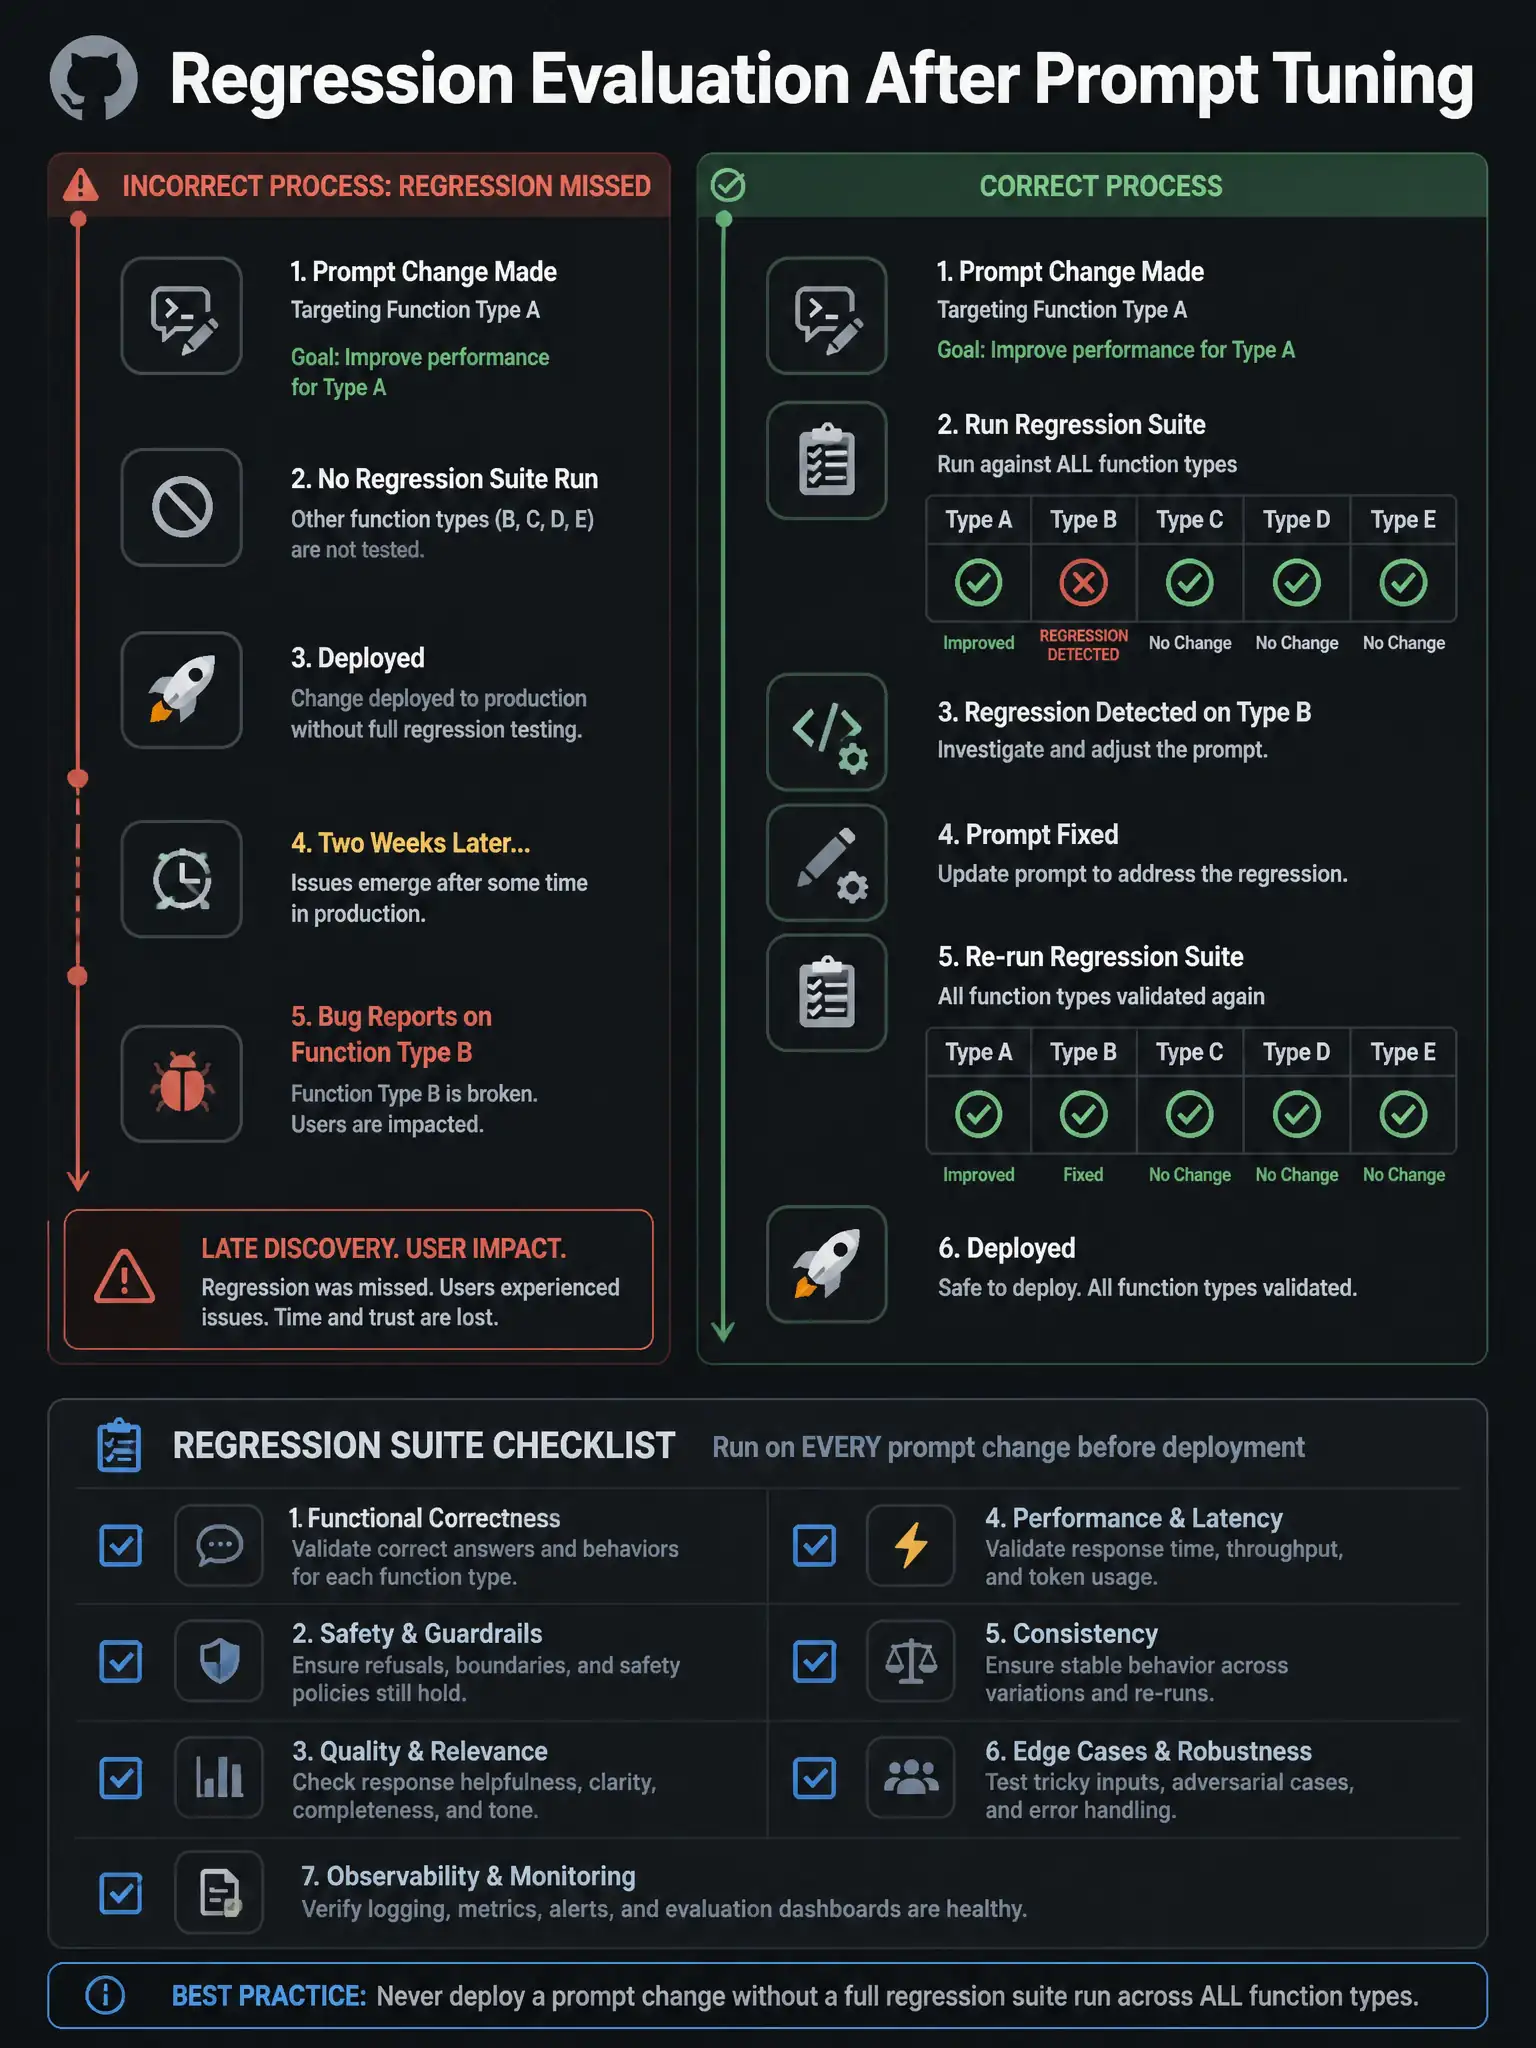
Fixing one leak without checking if you created another — that's the regression trap. When you change a system prompt, it can shift behavior across function types that weren't the target of the fix. You need a regression evaluation suite that runs all previously-working function types against the updated prompt before deployment.
Full Explanation
Prompt changes are global: a modification to the system prompt affects the model's behavior across all input types that flow through that prompt, not just the specific case the change was targeting. This is why regression evaluation is mandatory after any prompt tuning.
The regression evaluation suite is a predefined set of test inputs covering all major usage patterns and previously-validated behaviors. After any prompt change: 1. Run the full regression suite against the updated prompt 2. Compare results to the baseline (pre-change outputs) for each test case 3. Any test case that was passing before and now fails or degrades is a regression 4. Fix the regression before deploying the change
The regression suite should include representative examples from each function type, edge cases, and known previously-failing cases that were fixed in earlier tuning rounds.
The approach of relying on user bug reports is the status quo that led to the problem — bug reports came two weeks after deployment. Reactive discovery through user reports is too slow and damages trust.
The approach of using separate prompt configuration for each function type is a valid architectural approach for isolating changes, but it adds maintenance overhead and does not eliminate the need for regression testing within each prompt's domain. It is a design consideration, not a substitute for regression evaluation.
The approach of fine-tuning instead of prompt engineering is a separate architectural choice. Fine-tuned models can also introduce regressions; regression evaluation is required after fine-tuning as well. Switching to fine-tuning does not eliminate the need for the missing process.