
After deploying a documentation agent, you observe that it fails on approximately 20% of documentation requests — consistently producing incomplete summaries for files longer than 500 lines. The team's response each time is to manually correct the output and move on. After three months, the failure rate has not changed. What critical practice is the team neglecting?
Select an answer to reveal the explanation.
Short Explanation
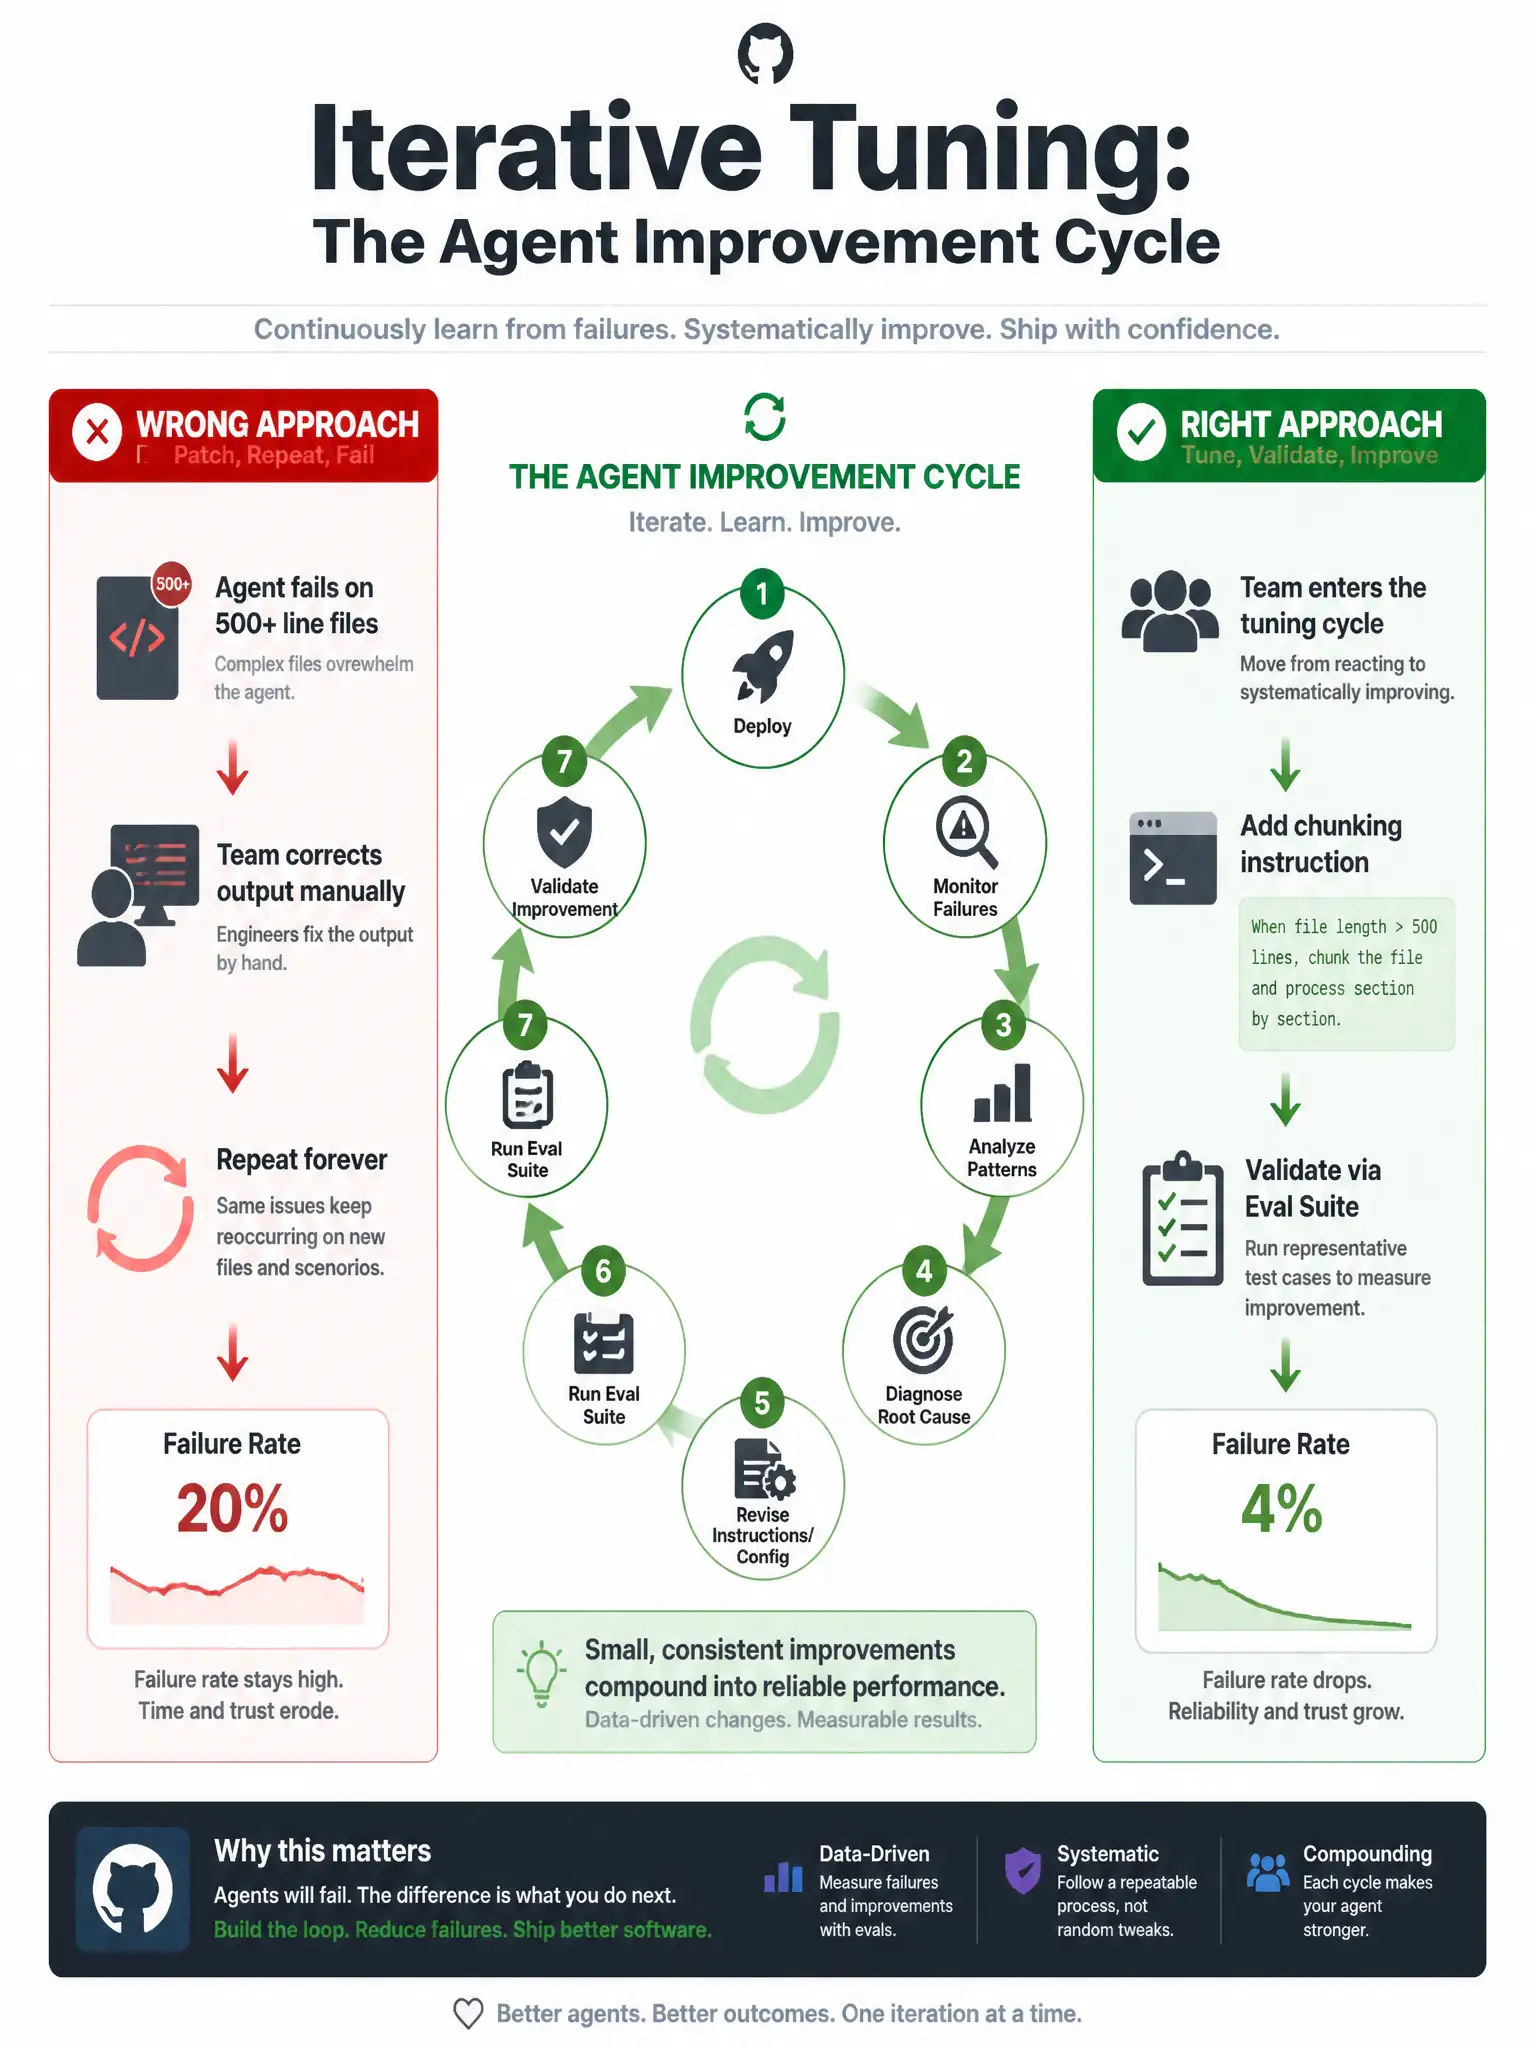
You're mopping the floor under a leaking pipe every day instead of fixing the pipe. The team's missing iterative tuning: analyze the failure pattern, revise instructions or memory config, and validate improvements. Agentic systems need continuous tuning, not just one-time deployment.
Full Explanation
This question tests your understanding of iterative tuning as a required ongoing practice in agentic system development, distinct from one-time deployment.
The correct practice is implementing iterative tuning: analyzing failure patterns, revising agent instructions or memory configuration, and validating improvements through evaluation, rather than only correcting outputs manually. The team has identified a consistent, reproducible failure pattern: files over 500 lines produce incomplete summaries. This is diagnostic gold — a clear failure signature that points to a specific root cause, likely context management, chunking strategy, or instruction gaps for long documents. Iterative tuning means: (1) analyzing the failure pattern systematically; (2) hypothesizing a root cause, such as the agent truncating input when the context window fills; (3) revising the agent's instructions, memory configuration, or processing strategy, such as adding file chunking or adjusting summarization instructions for long files; (4) running the evaluation suite to validate improvement; and (5) deploying the updated agent. This cycle should repeat for each identified failure cluster until the rate is acceptable. Manual output correction is not tuning — it addresses individual outputs without improving the agent.
The option suggesting the team should accept the 20% failure rate as an acceptable performance baseline for agentic systems is incorrect. A 20% failure rate on a consistent, reproducible pattern is not an acceptable baseline — it is an optimization opportunity. Agentic systems are expected to improve over time through iterative tuning; accepting persistent known failures is a process failure.
The option suggesting the team should increase the agent's context window to handle longer files without changing its instructions is incorrect, though plausible. While context window size may be a contributing factor, simply increasing the context window without changing instructions may not resolve the summarization quality issue. More importantly, this option represents a single intervention without the systematic diagnose-revise-validate cycle that iterative tuning requires. Even if it helps, it must be paired with evaluation validation.
The option suggesting the team should replace the documentation agent with a rule-based system for files over 500 lines is incorrect. Replacing the agent with a rule-based system for long files adds architectural complexity and eliminates the benefits of the agentic approach for that use case. The correct response to a diagnosable failure pattern is to tune the agent, not replace it with a simpler system.
Iterative tuning is not optional — it's the mechanism by which deployed agents improve over time.