
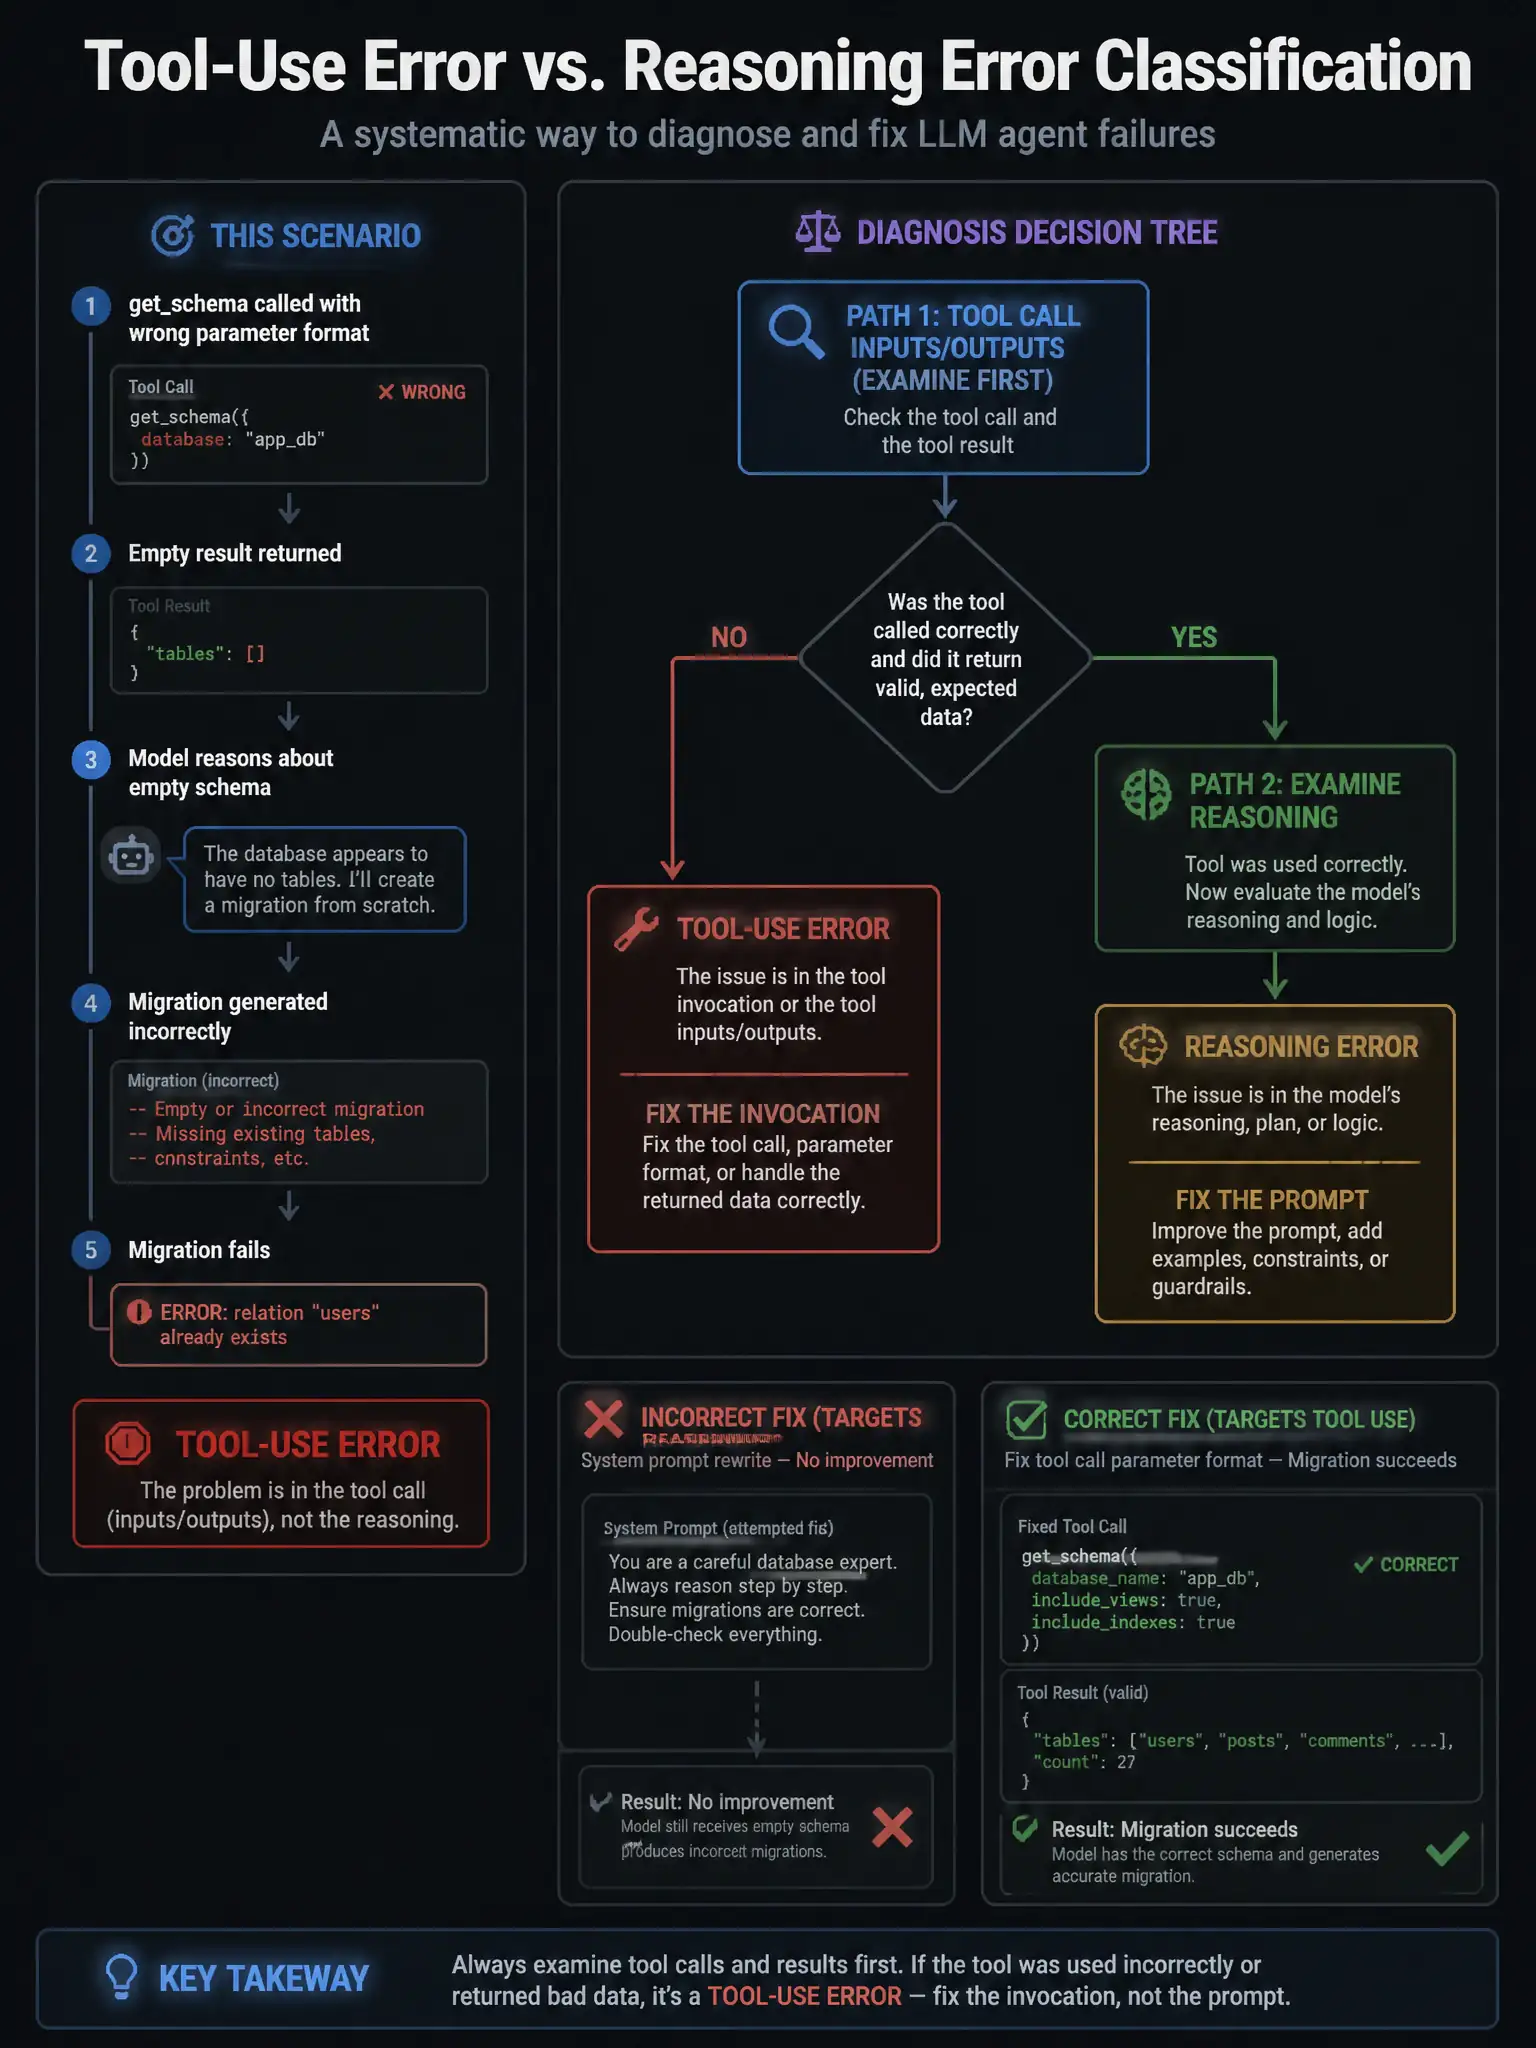
An agent for generating database migrations is frequently producing incorrect output. A developer reviews the logs and concludes the model is reasoning incorrectly about the schema, so they rewrite the reasoning instructions in the system prompt. After the change, the failures persist at the same rate. A deeper log review later reveals the agent was calling a get_schema tool with the wrong parameter format, receiving empty results, and then reasoning about an empty schema. What was the misdiagnosis?
Select an answer to reveal the explanation.
Short Explanation
You blamed the navigator when the GPS was sending bad coordinates. The agent's reasoning wasn't the problem; its malformed get_schema call gave it an empty schema to reason about. Fix the tool invocation, not the prompt.
Full Explanation
Failure classification in agentic systems requires distinguishing between two categories of errors:
Reasoning errors: the model receives correct inputs (context, tool results) but draws incorrect conclusions, applies wrong logic, or makes faulty decisions based on available information.
Tool-use errors: the model constructs a tool call incorrectly (wrong parameter format, missing required fields, wrong tool selected), resulting in errors or empty/incorrect tool results that then feed into subsequent reasoning.
The misdiagnosis was treating this as a reasoning error when it was actually a tool-use error. The agent received empty schema results because its tool call parameter format was wrong. The subsequent reasoning — about an empty schema — may have been internally consistent but was reasoning about nothing. Rewriting the reasoning instructions cannot fix a problem that occurs before the model even has data to reason about.
The diagnostic approach for distinguishing these categories: examine the full trace including tool call inputs and outputs before the model's reasoning step. If tool results are empty or erroneous, the root cause is in the tool invocation layer. If tool results are correct but the reasoning about them is wrong, the root cause is in the reasoning layer.
The claim that the system prompt reasoning instructions were too long, causing the model to ignore them, is a distractor about prompt design, not about the actual failure mechanism.
The claim that the get_schema tool had a bug that caused it to return empty results regardless of input parameters would have been caught in tool unit tests and would manifest as consistently empty results for all inputs, not specifically for the agent's malformed parameter format.
The claim that the agent's model did not have enough training data on database schema formats to understand migration tasks is a model capability claim that would require broad evidence across many scenarios, not a diagnosis for a specific recurring failure with a specific tool call pattern.