
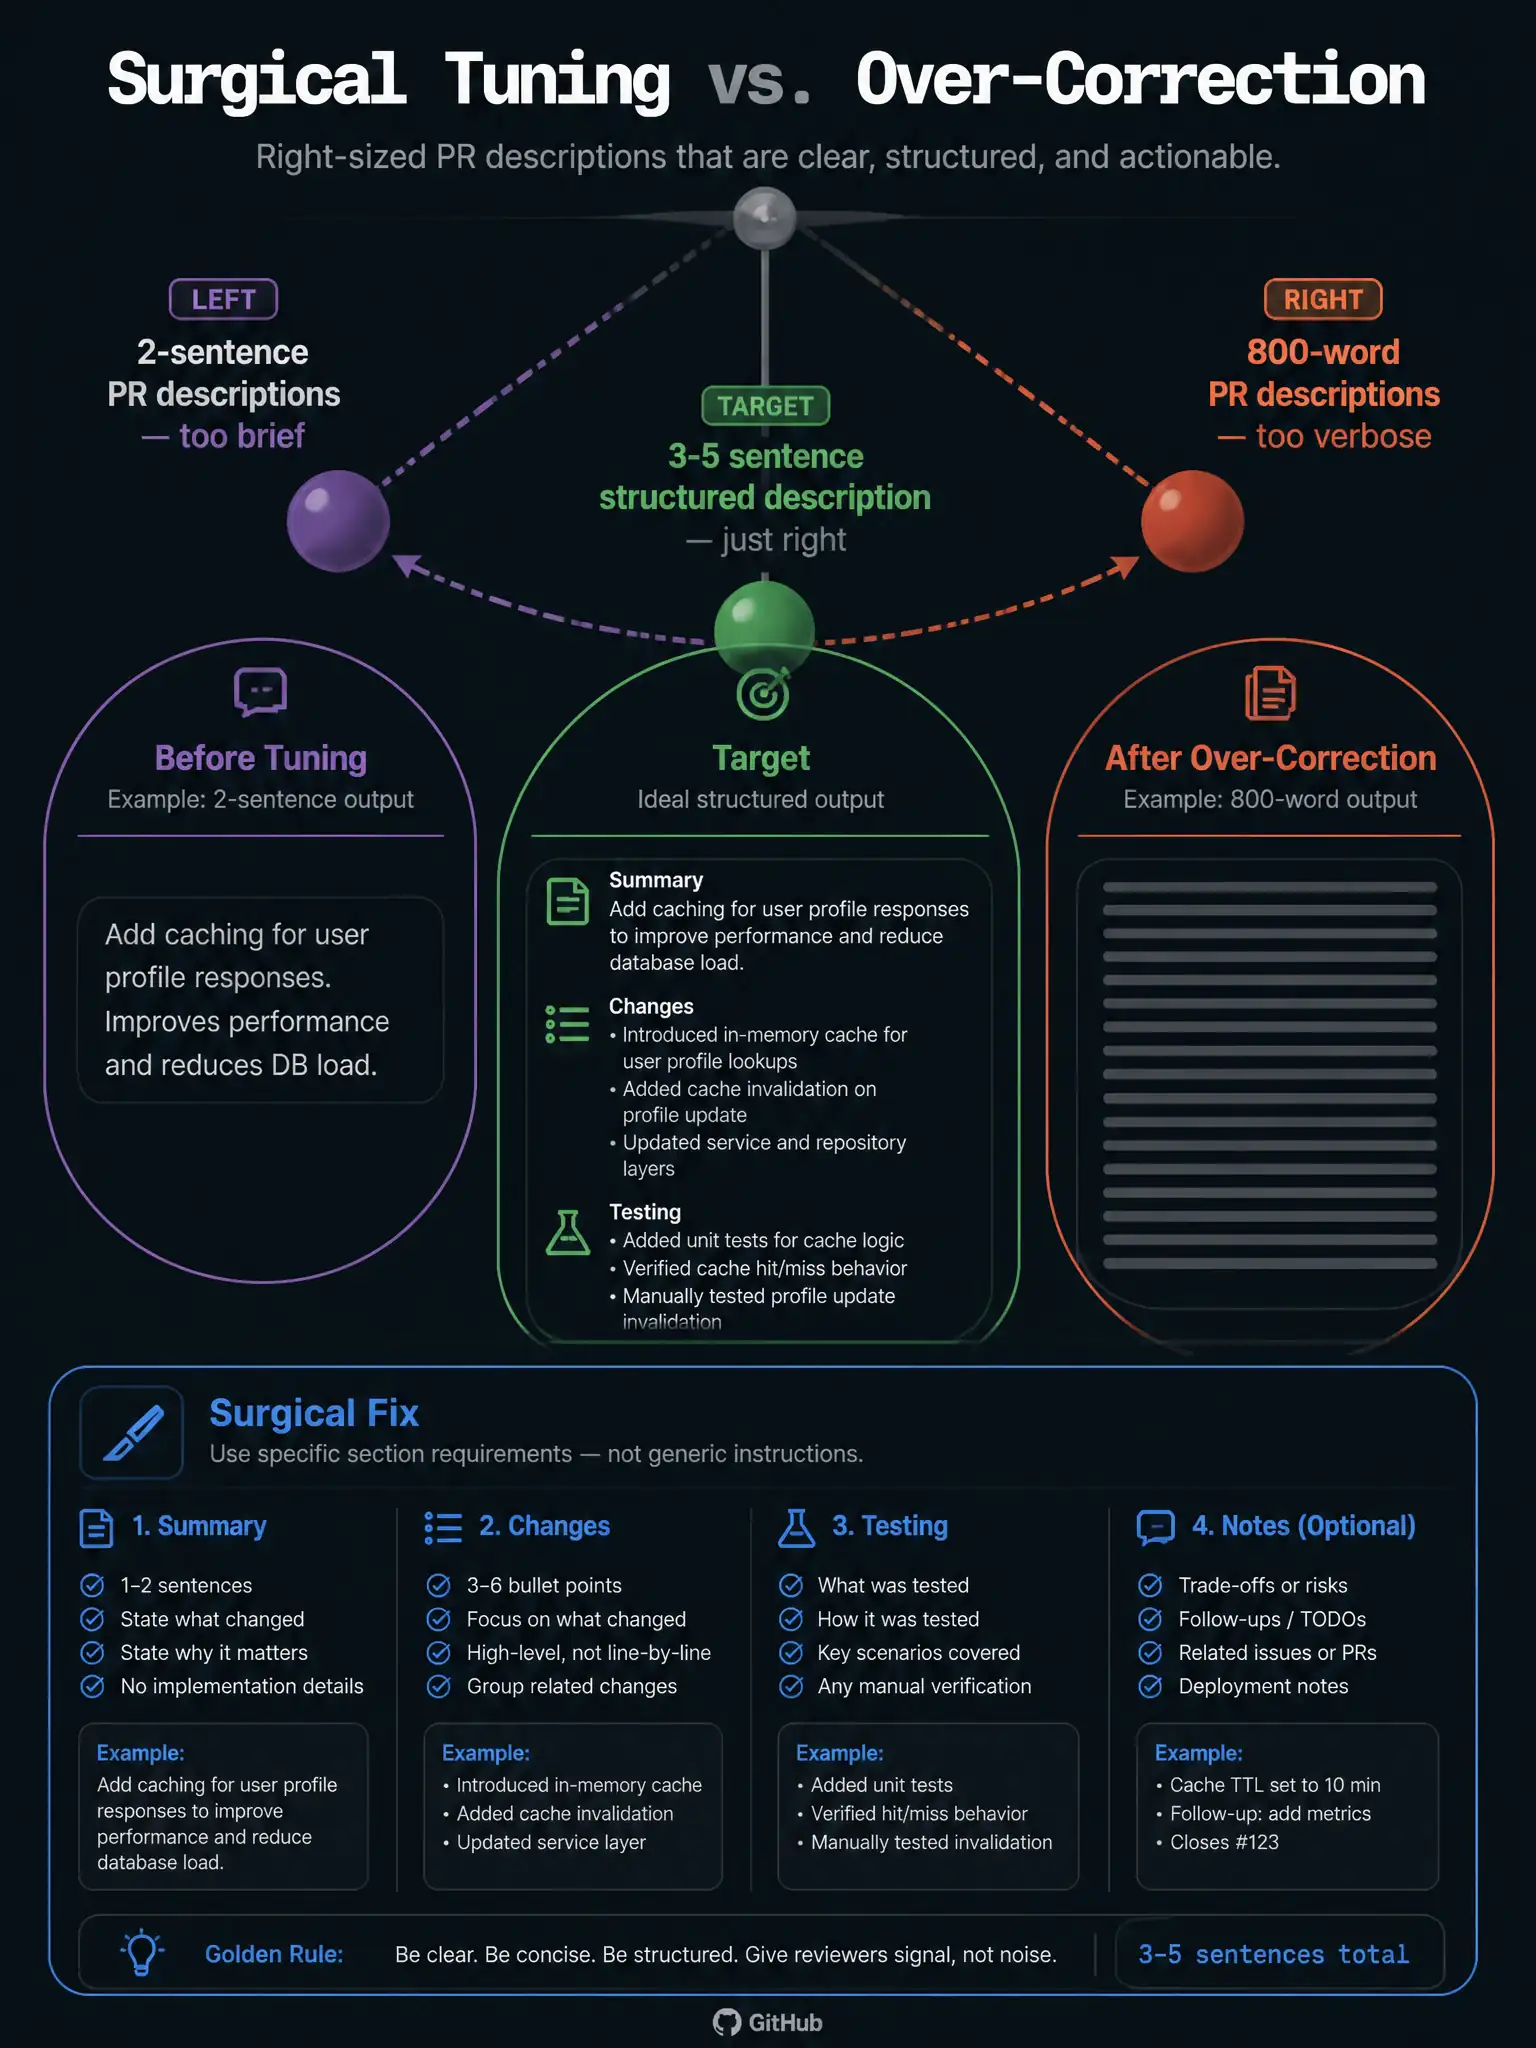
An agent that generates pull request descriptions was producing descriptions that were too brief — averaging 2 sentences. The team modified the system prompt to strongly emphasize detailed explanations. After the change, the agent began producing descriptions averaging 800 words that reviewers find too verbose and time-consuming to read. What tuning mistake was made?
Select an answer to reveal the explanation.
Short Explanation
You overcorrected. You turned the volume all the way up instead of adjusting the dial, so the descriptions swung from too brief to too verbose. Surgical tuning would target the missing sections, not tell the model to be generally more detailed.
Full Explanation
Over-correction is a common tuning failure where a valid problem is addressed with changes that are too broad or too strong, causing the behavior to swing past the target to the opposite extreme. In this case, 'too brief' was the diagnosed problem, and 'strongly emphasize detailed explanations' was the blunt instrument applied globally. Surgical tuning looks different: examine the actual failing examples, such as the 2-sentence descriptions, identify what they were missing, such as context about the change's purpose, affected components, and testing notes, and add specific guidance about those elements. For example: 'Include the following sections in each pull-request description: Summary (1-2 sentences), Changes Made (bullet list of affected files/functions), Testing Approach, and Known Limitations if any.' This structured guidance provides a floor without an open-ended directive to be 'detailed,' which the model interprets as 'more is better.' The temperature-change proposal is wrong because increasing temperature affects randomness and diversity in outputs, not output length, so it would not address the brevity problem. The larger-context-window proposal is wrong because context window size determines how much input the model can process, not the length of its output, and it is not the cause of 2-sentence outputs or a fix for the verbosity problem. The different-base-model proposal is wrong because switching models is an expensive architectural change that should be a last resort, not the first response to a tuning failure, and the problem is identifiable as a prompt configuration issue rather than a fundamental model capability gap.