
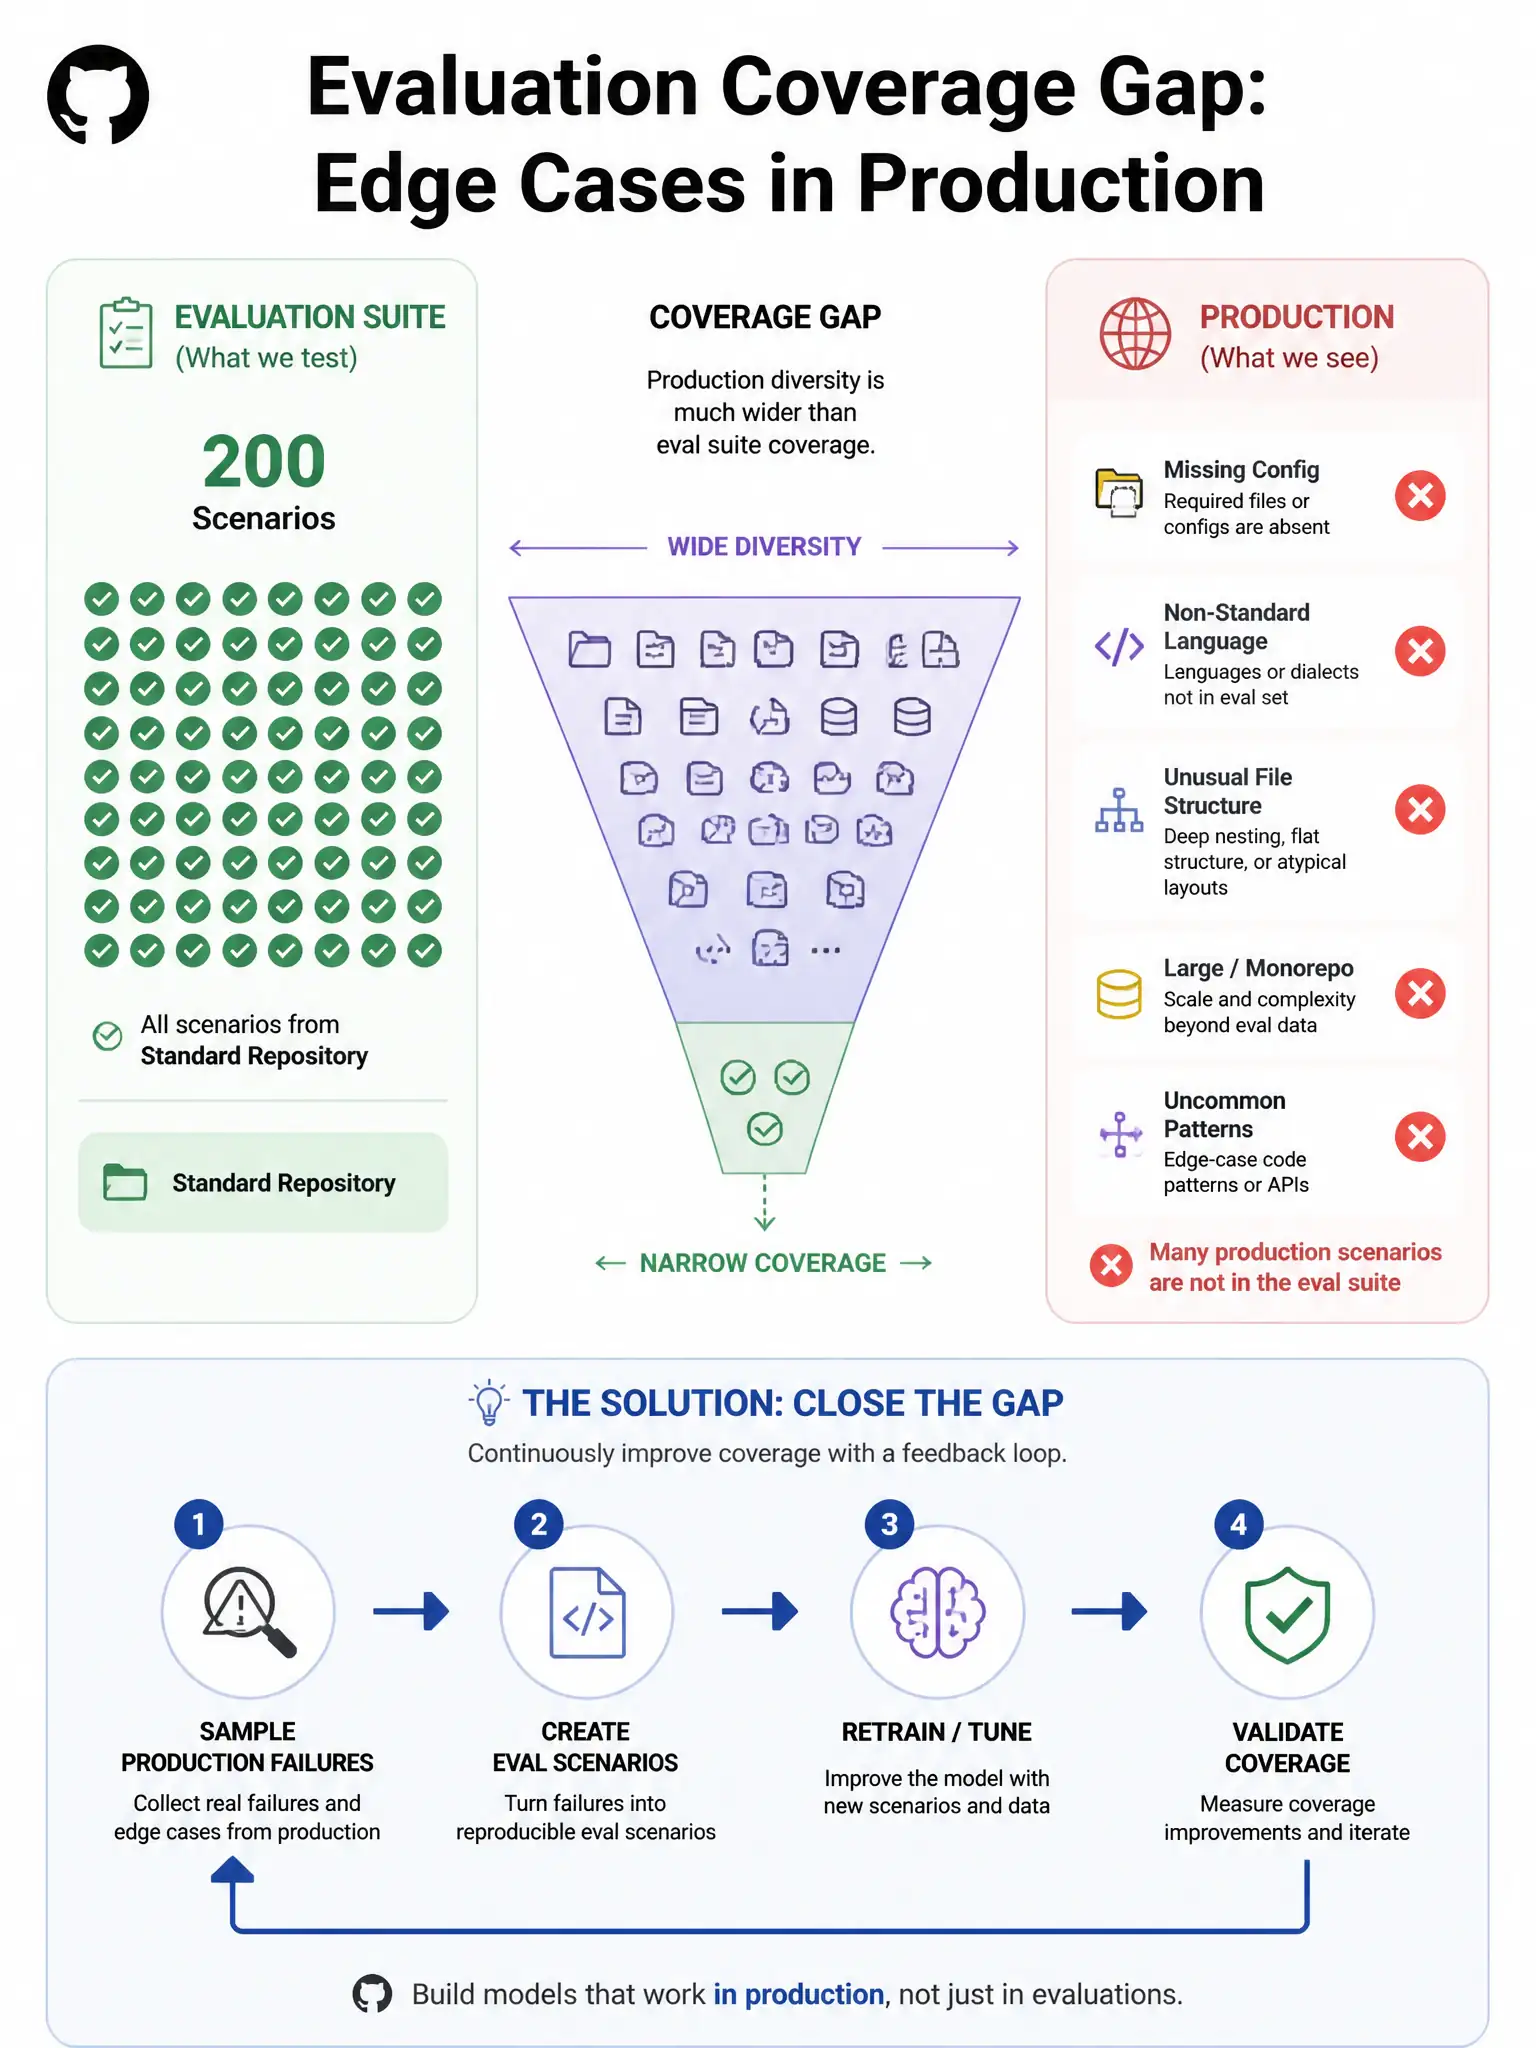
A team reports that their code-review agent passes all 200 scenarios in the evaluation suite during testing but frequently fails when deployed to real repositories. Failures cluster around unusual file structures, non-standard languages, and repositories with missing configuration files. What is the most appropriate corrective action?
Select an answer to reveal the explanation.
Short Explanation
If your eval suite only tests easy stuff, your agent will choke on weird stuff. When production failures cluster around unusual files, non-standard languages, and missing configs, expand the suite with those real-world edge cases. That's the evaluation-driven fix the exam wants you to spot.
Full Explanation
This question tests your ability to diagnose and remediate incomplete evaluation coverage — a failure mode where the evaluation suite is representative of happy-path scenarios but does not cover the diversity of real production inputs. The exam tests whether you recognize incomplete evaluation coverage as a distinct root cause.
The correct response is to expand the evaluation suite with edge-case scenarios sampled from production failure patterns, covering non-standard inputs and missing configuration states. When production failures cluster around specific categories of inputs, such as unusual file structures, non-standard languages, and missing configs, the right response is to sample those failure patterns and create corresponding evaluation scenarios. This is called evaluation-driven tuning: you use production failure data to expand your eval suite, then iterate on the agent until it handles those cases correctly. This ensures the evaluation suite actually reflects the distribution of inputs the agent encounters in production.
The option that increases the evaluation suite timeout is incorrect. Timeout increases address performance constraints, not capability gaps. The failures described are about the agent not knowing how to handle certain inputs, not about running out of time.
The option that adds a fallback instruction telling the agent to skip files it does not recognize is incorrect. Instructing the agent to skip unrecognized files treats the symptom rather than the root cause and degrades the agent's usefulness on real-world repositories. It would also silently ignore failures rather than correcting the agent's behavior.
The option that deploys a separate agent instance dedicated to handling non-standard repositories is incorrect. Deploying a separate agent for non-standard repositories is an architectural workaround that adds operational complexity and maintenance burden. It also sidesteps the evaluation problem — the second agent would have the same evaluation coverage gap unless specifically addressed. The correct approach is to fix the evaluation suite and improve the primary agent's handling of the problematic scenarios.
The key principle here is that evaluation suites must be continuously updated as production failure patterns are discovered. Static eval suites that were built before deployment will drift from reality over time.