
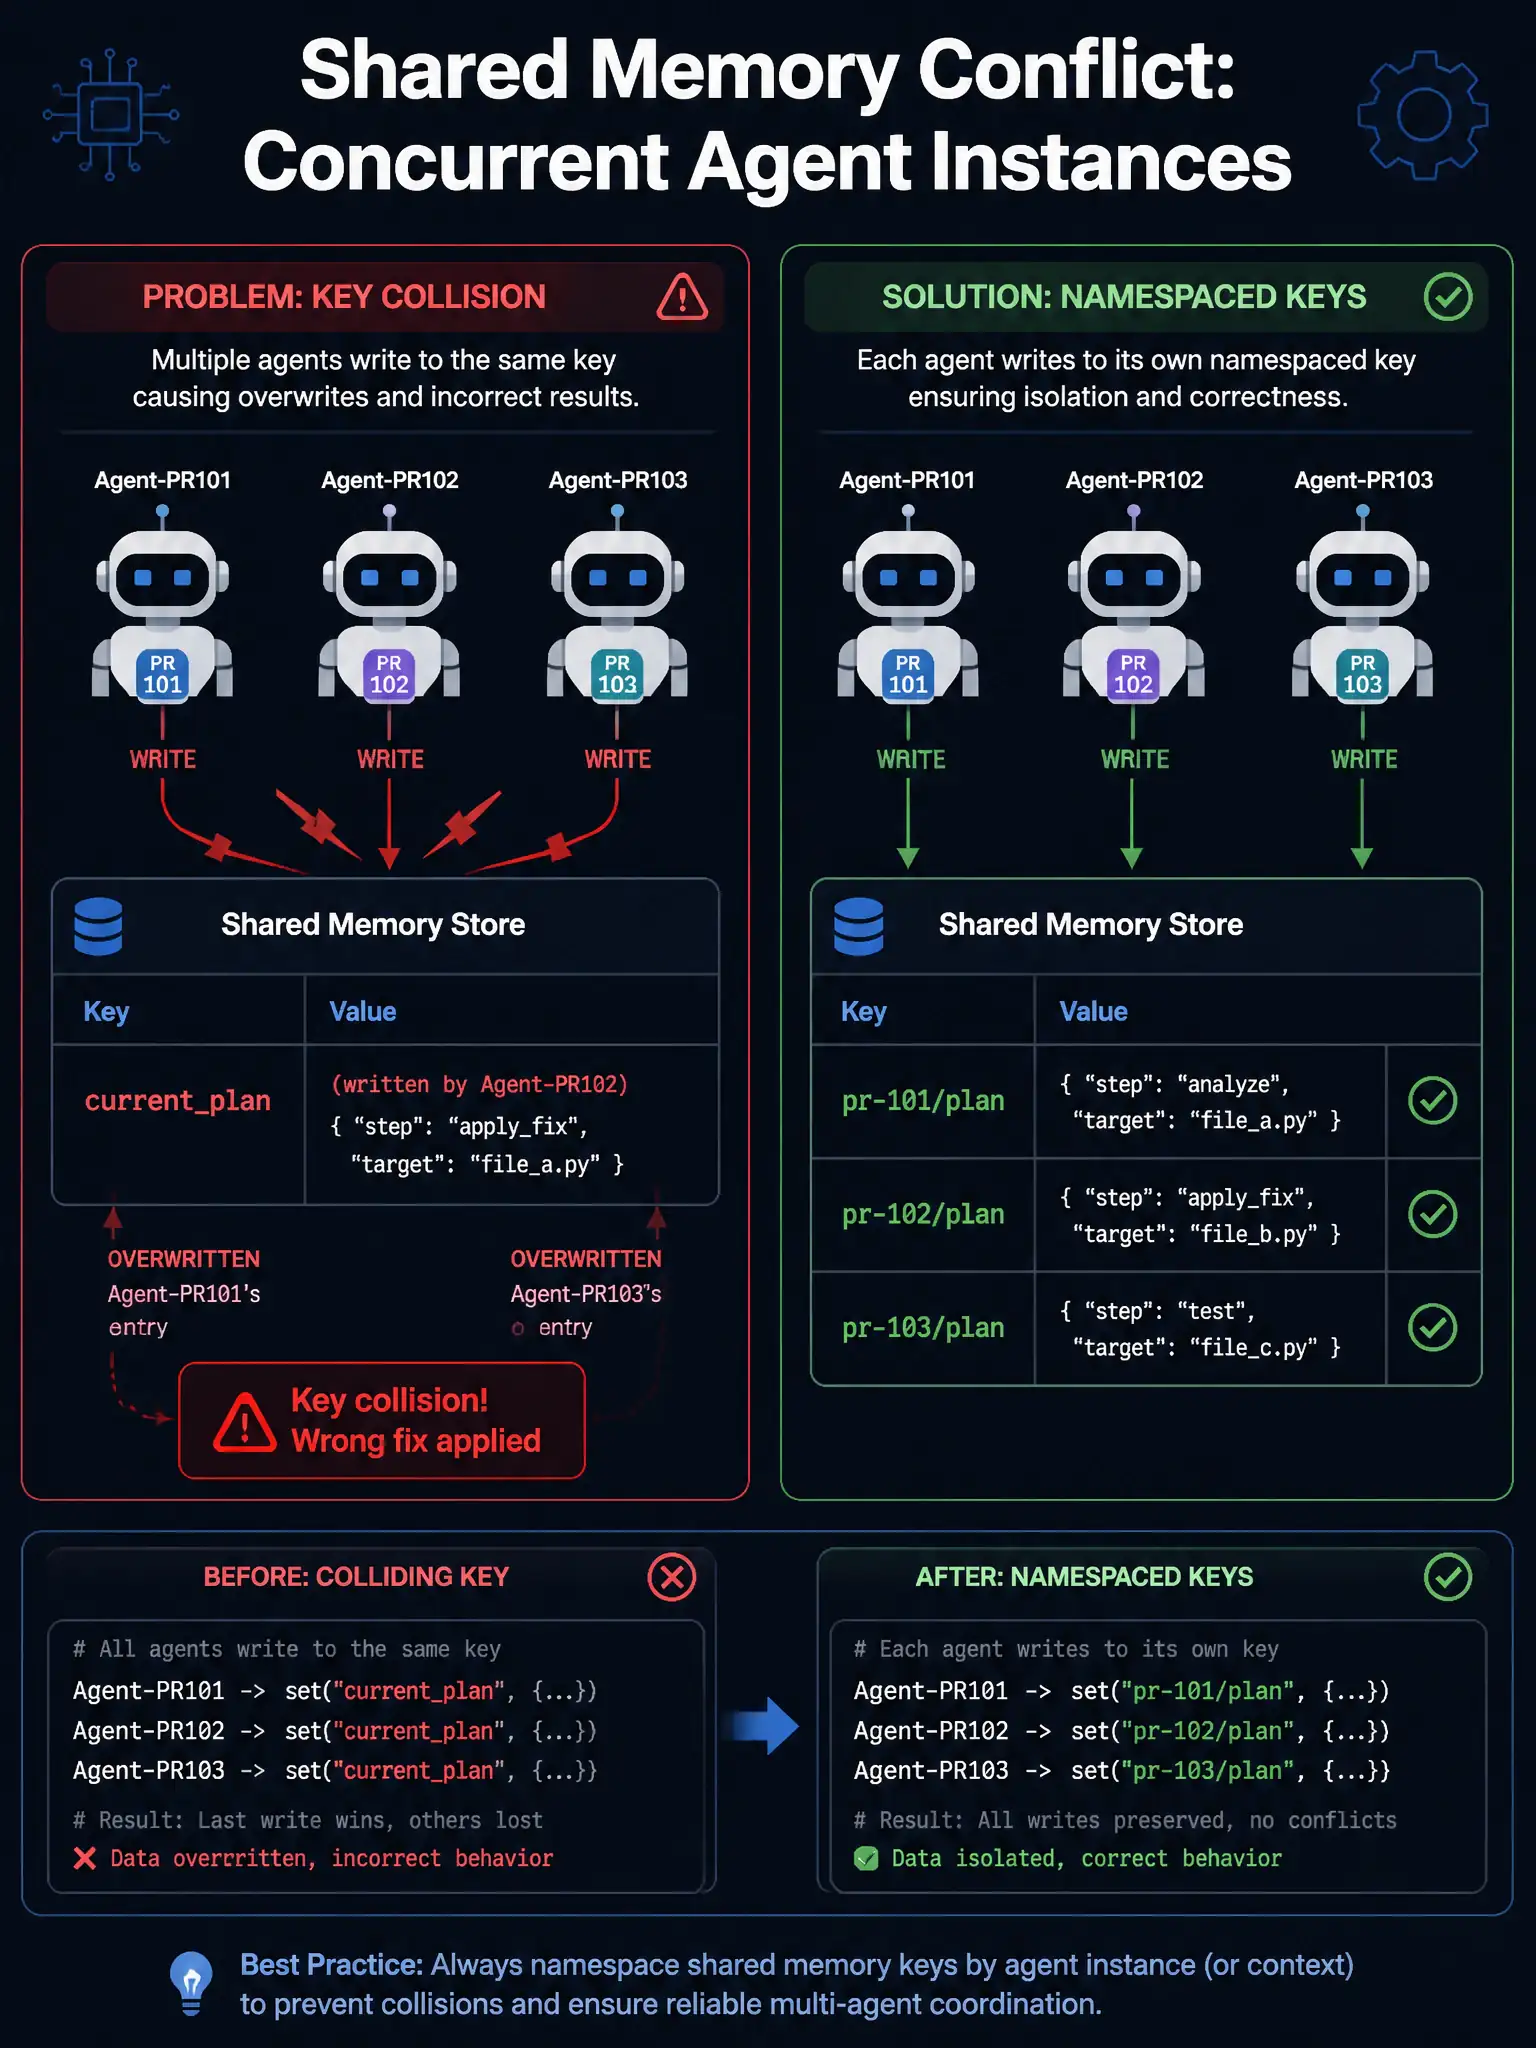
An agent that processes pull requests in parallel is failing intermittently — sometimes it applies the wrong fix to the wrong PR, or skips a PR entirely. Investigation reveals that multiple concurrent agent instances are all reading from and writing to the same shared memory store using the same key namespace. Which fix addresses the root cause?
Select an answer to reveal the explanation.
Short Explanation
This is a shared-state race condition, like two chefs grabbing the same salt shaker. You need to scope each agent instance's memory keys to its PR identifier so instances cannot overwrite each other's state. That gives each instance its own labeled shaker without serializing everything.
Full Explanation
When multiple concurrent agent instances share a memory store with the same key namespace, writes from one instance overwrite state written by another. This produces exactly the described symptoms: wrong fixes applied to wrong PRs because one instance reads another's work-item state, and skipped PRs because a state entry is overwritten before the owning instance can act on it.
The PR-scoped key fix is correct: the solution is key-space isolation. Each agent instance should prefix or namespace its memory keys with a unique task identifier — in this case, the pull request number or a unique execution identifier, for example pr-1234/current-file or pr-1234/plan. This guarantees that reads and writes by one instance never collide with another's, even when using the same underlying shared store.
The retry-budget fix is incorrect: retrying failed writes does not solve a race condition. If two instances write to the same key, retrying just means the conflict happens more often. The last writer wins, and the earlier write is lost regardless of retry count.
The in-context-memory switch is tempting but over-engineered and limiting. In-context memory does provide per-instance isolation, but it limits each instance's state to what fits in its context window and makes cross-instance coordination impossible. The shared external store is a valid architectural choice when properly namespaced — the problem is key collision, not the store itself.
The global-lock fix is the classic wrong answer for concurrency problems. A global lock would technically prevent conflicts, but it serializes all agent instances, completely eliminating the concurrency benefit. It also introduces deadlock risk and becomes a throughput bottleneck at scale. Namespace isolation is the idiomatic solution for concurrent agent state management.
The core pattern: any time multiple agent instances share a memory store, every key should incorporate a unique task or instance identifier to prevent cross-instance contamination.