
Two instances of a code-review agent are running concurrently to handle high review volume. Both instances read the same shared state file that tracks which pull requests have been assigned for review, add their assignments to the list in memory, and then write the updated list back to the file. After several hours, the team notices that some pull requests are assigned to two reviewers while others have no reviewer, indicating state corruption. What is the root cause?
Select an answer to reveal the explanation.
Short Explanation
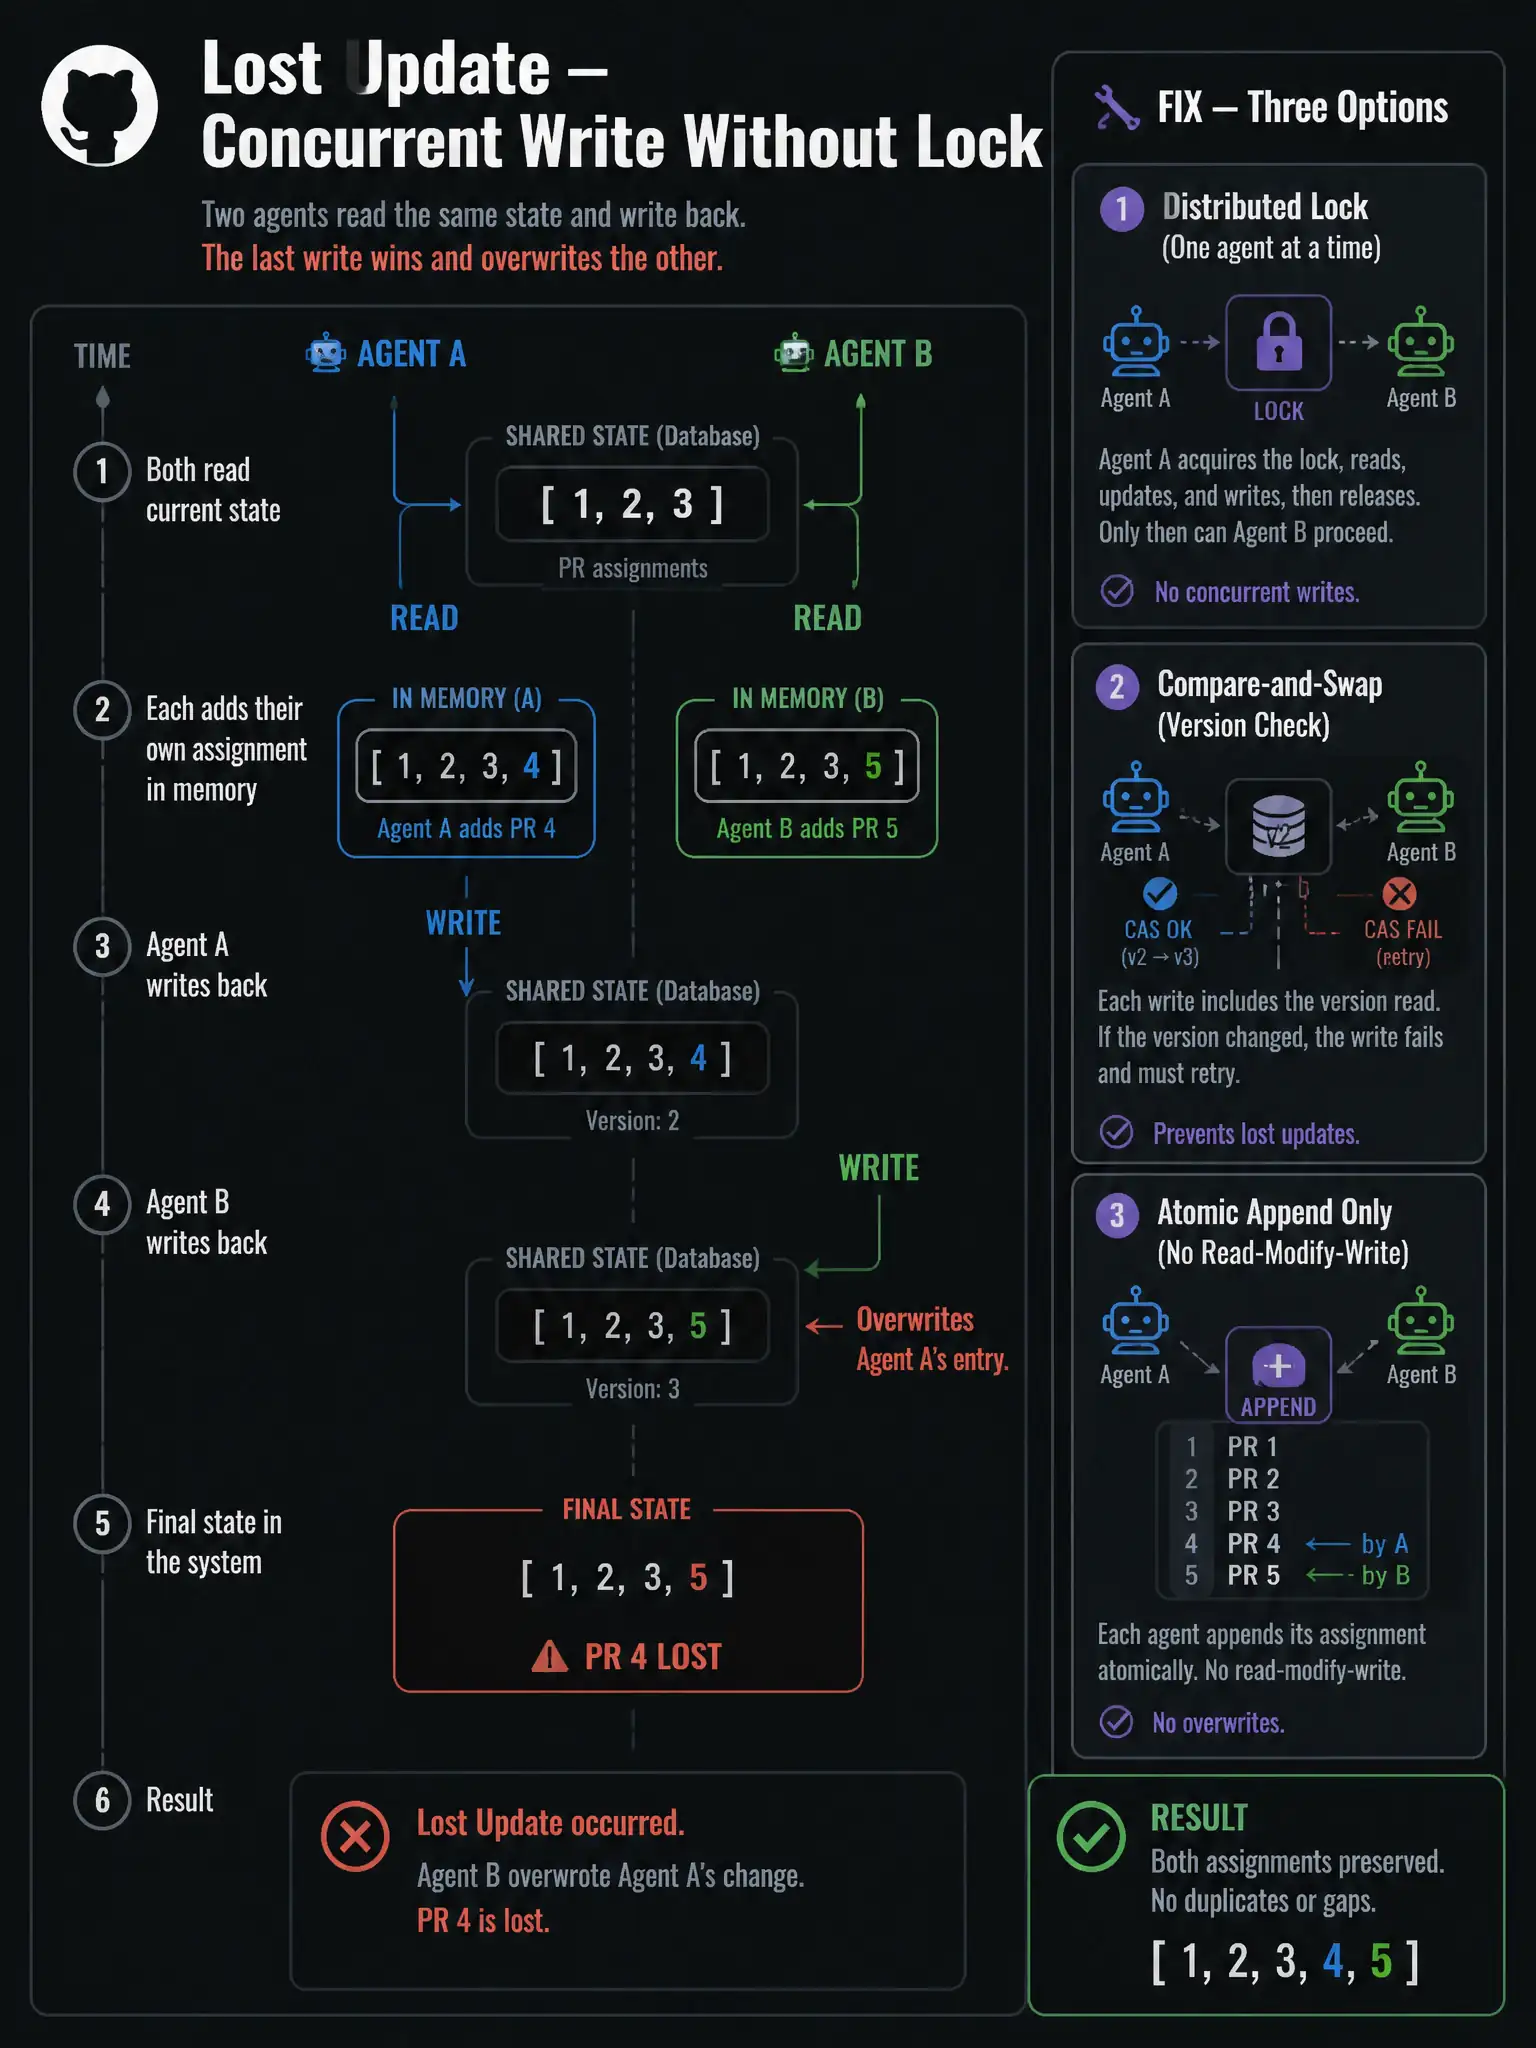
Two agents grab the same to-do list, each writes its additions without knowing the other is doing it at the same time — classic lost update problem. When the second write lands after the first, it overwrites the first agent's additions. You fix it with distributed locking or compare-and-swap so only one writer modifies the state at a time.
Full Explanation
The read-modify-write pattern on shared state without a lock is a classic race condition. Here is the sequence that causes corruption: first agent instance reads the state file (pull-request list: one, two, three); second agent instance reads the same snapshot; first agent adds a new pull request and writes back; second agent adds another pull request to its in-memory copy and writes back, overwriting the first agent's addition. The result is lost updates: some additions are dropped, others may be applied twice if both instances happen to add the same pull request independently. Solutions include a distributed lock (mutex) that allows only one agent to perform the read-modify-write at a time; compare-and-swap (optimistic locking) where the write includes the version seen at read time and fails if the state has changed, forcing a retry; or moving to an atomic append operation where each agent only adds its own assignment without reading and rewriting the full list. The claim that the shared state file format is incompatible with concurrent reads and must be changed to a database format addresses the symptom but not the cause. Changing to a database does not inherently prevent the lost-update problem without isolation levels and locking configured appropriately. The claim about different time zones causing timestamp conflicts is not a real failure mode for this type of state management operation. The claim that the state file has grown too large to be read reliably by both agent instances simultaneously would cause read errors or truncation, not the specific pattern of some pull requests having two reviewers and others having none.