
A developer reviews the trace of a GitHub Copilot agent that is supposed to open a GitHub issue, search for related issues, and then post a linking comment. The trace shows: the agent correctly called the 'create_issue' tool, then called 'search_issues' with a query that matched nothing, and then — instead of recognizing there were no related issues — the agent called 'create_issue' a second time with the same parameters. How should this failure be classified?
Select an answer to reveal the explanation.
Short Explanation
You've got a reasoning error here. The tools and environment worked fine; the agent just misread an empty search result and repeated issue creation instead of skipping the comment. That's bad logic, not bad tools or a broken environment.
Full Explanation
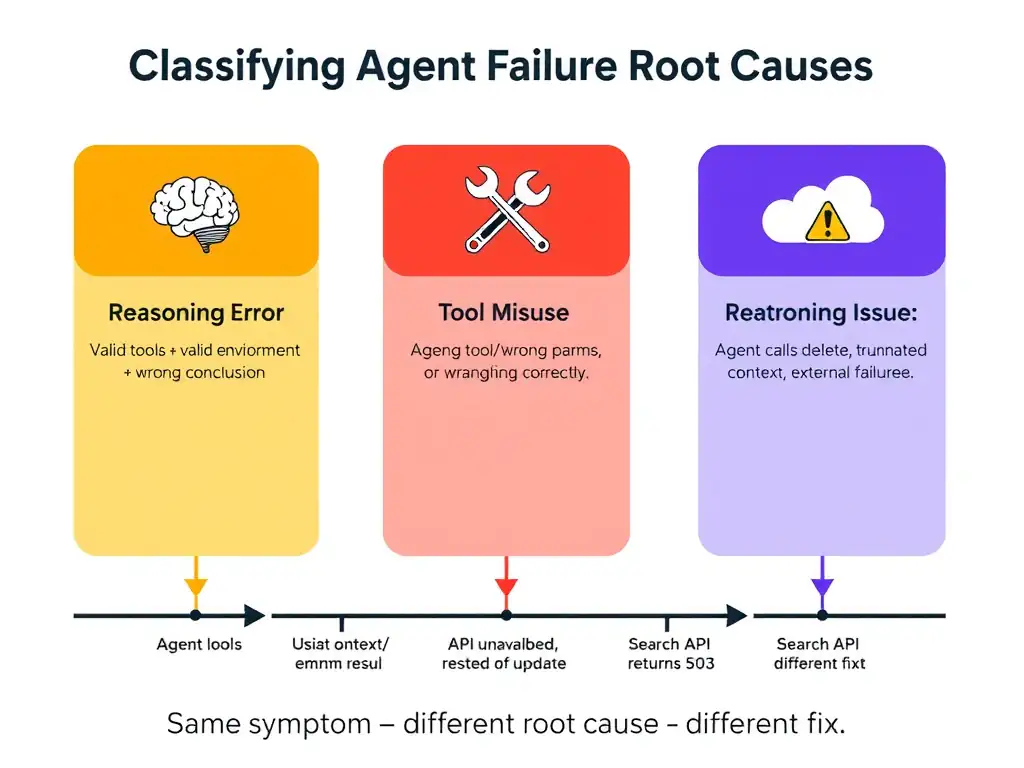
Classifying agent failures into their root cause category is essential for choosing the right fix. The three primary categories are: reasoning error, where the agent's logic or inference is wrong because it received valid inputs and had the right tools but drew an incorrect conclusion or took an illogical next action; tool misuse, where the agent called a tool with wrong parameters, called the wrong tool, or called a tool at the wrong time; and context or environment issue, where something outside the agent's reasoning caused the failure, such as a tool returning an error, an API being unavailable, or the context window being truncated. The correct classification is the reasoning error option: the agent misinterpreted an empty search result as a signal to repeat the issue creation step rather than skipping the comment. The trace shows that both tools functioned correctly: the create_issue call succeeded, and the search_issues call returned a valid empty response. The environment was healthy. The agent's mistake was in interpreting the empty result: instead of branching to 'no related issues found — skip comment step,' it incorrectly re-triggered the issue creation step. This is a reasoning or logic error in the agent's decision-making. The environment issue option is incorrect because the search tool returned a valid response. An empty result set is not an environment failure; it is a legitimate outcome the agent should handle. The tool misuse option is incorrect. The agent called create_issue rather than post_comment, which does look like the wrong tool, but the deeper cause is that the agent's reasoning led it to that wrong choice. The action is a symptom; the reasoning flaw is the root cause. The context issue option is incorrect. There is no evidence of truncation or token exhaustion in the scenario. The tools all returned responses, and the agent continued acting, just incorrectly.