
In a multi-agent deployment pipeline, the testing agent fails to complete its task after 3 retries. The deployment must not proceed without passing tests. What should the orchestrator do?
Select an answer to reveal the explanation.
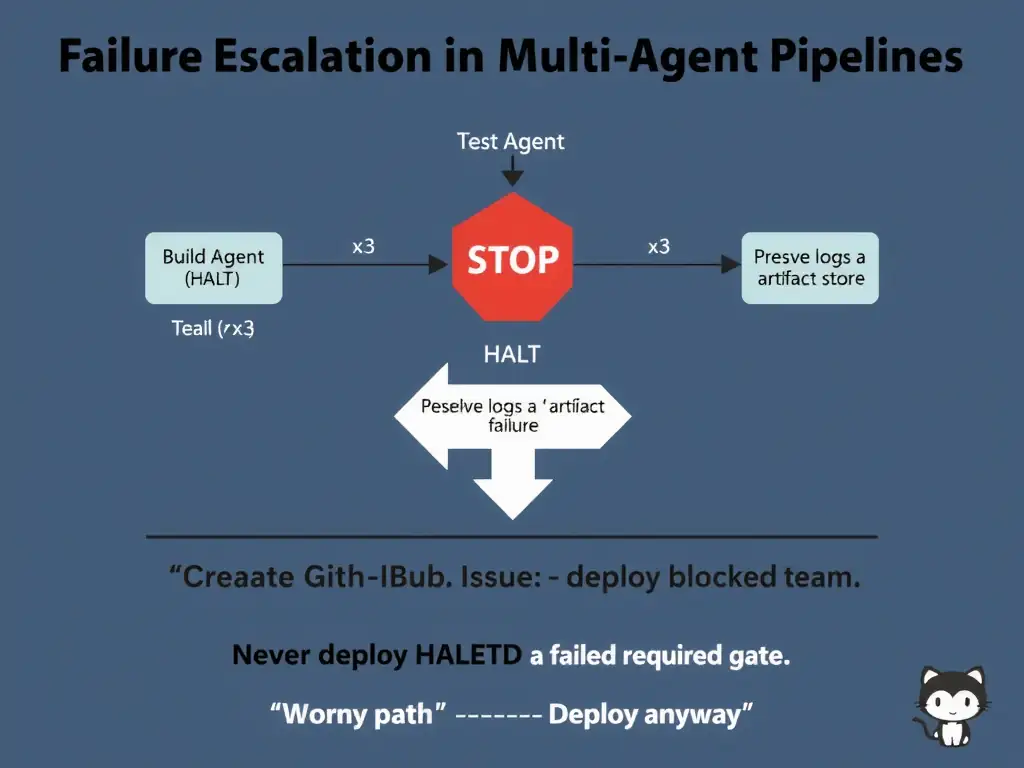
Short Explanation
If a testing agent fails after three retries, you stop the pipeline, keep the logs and state, and alert the team. You don’t deploy, skip tests, or blindly rerun everything when a required gate fails.
Full Explanation
In agentic pipelines, failure escalation paths are as important as the happy path. When a critical agent, such as a testing agent whose success is required for safe progression, exhausts its retries, the orchestrator should halt the pipeline to prevent downstream steps from executing on an untested artifact. It should preserve the failing agent's logs, intermediate outputs, and error details in a durable location, such as an artifact upload or issue comment, and notify the responsible team through a GitHub Issue, webhook notification, or pager alert. The preserved state should not be destroyed because it is critical for diagnosing and fixing the failure. Halting with state preservation and notification is the safe failure mode because it prevents unsafe deployments, preserves diagnostic information, and gets a human involved to resolve the root cause. Proceeding with deployment and flagging the test failure in deploy logs is wrong because it violates the basic purpose of the testing gate; a log entry is a post-hoc record but does not prevent the unsafe deployment. Skipping the testing phase and proceeding directly to the security scan phase is wrong because it bypasses a required quality gate, and security scanning cannot substitute for functional testing. Re-running the full pipeline from the beginning is wrong because it consumes resources, discards useful partial state, and is unlikely to succeed if the root cause is a persistent failure rather than a flaky transient issue; it should only be considered after diagnosis.