
A county IR team asks how tokenization affects searching rare hostnames in alert text. What connection should they understand?
Select an answer to reveal the explanation.
Short Explanation
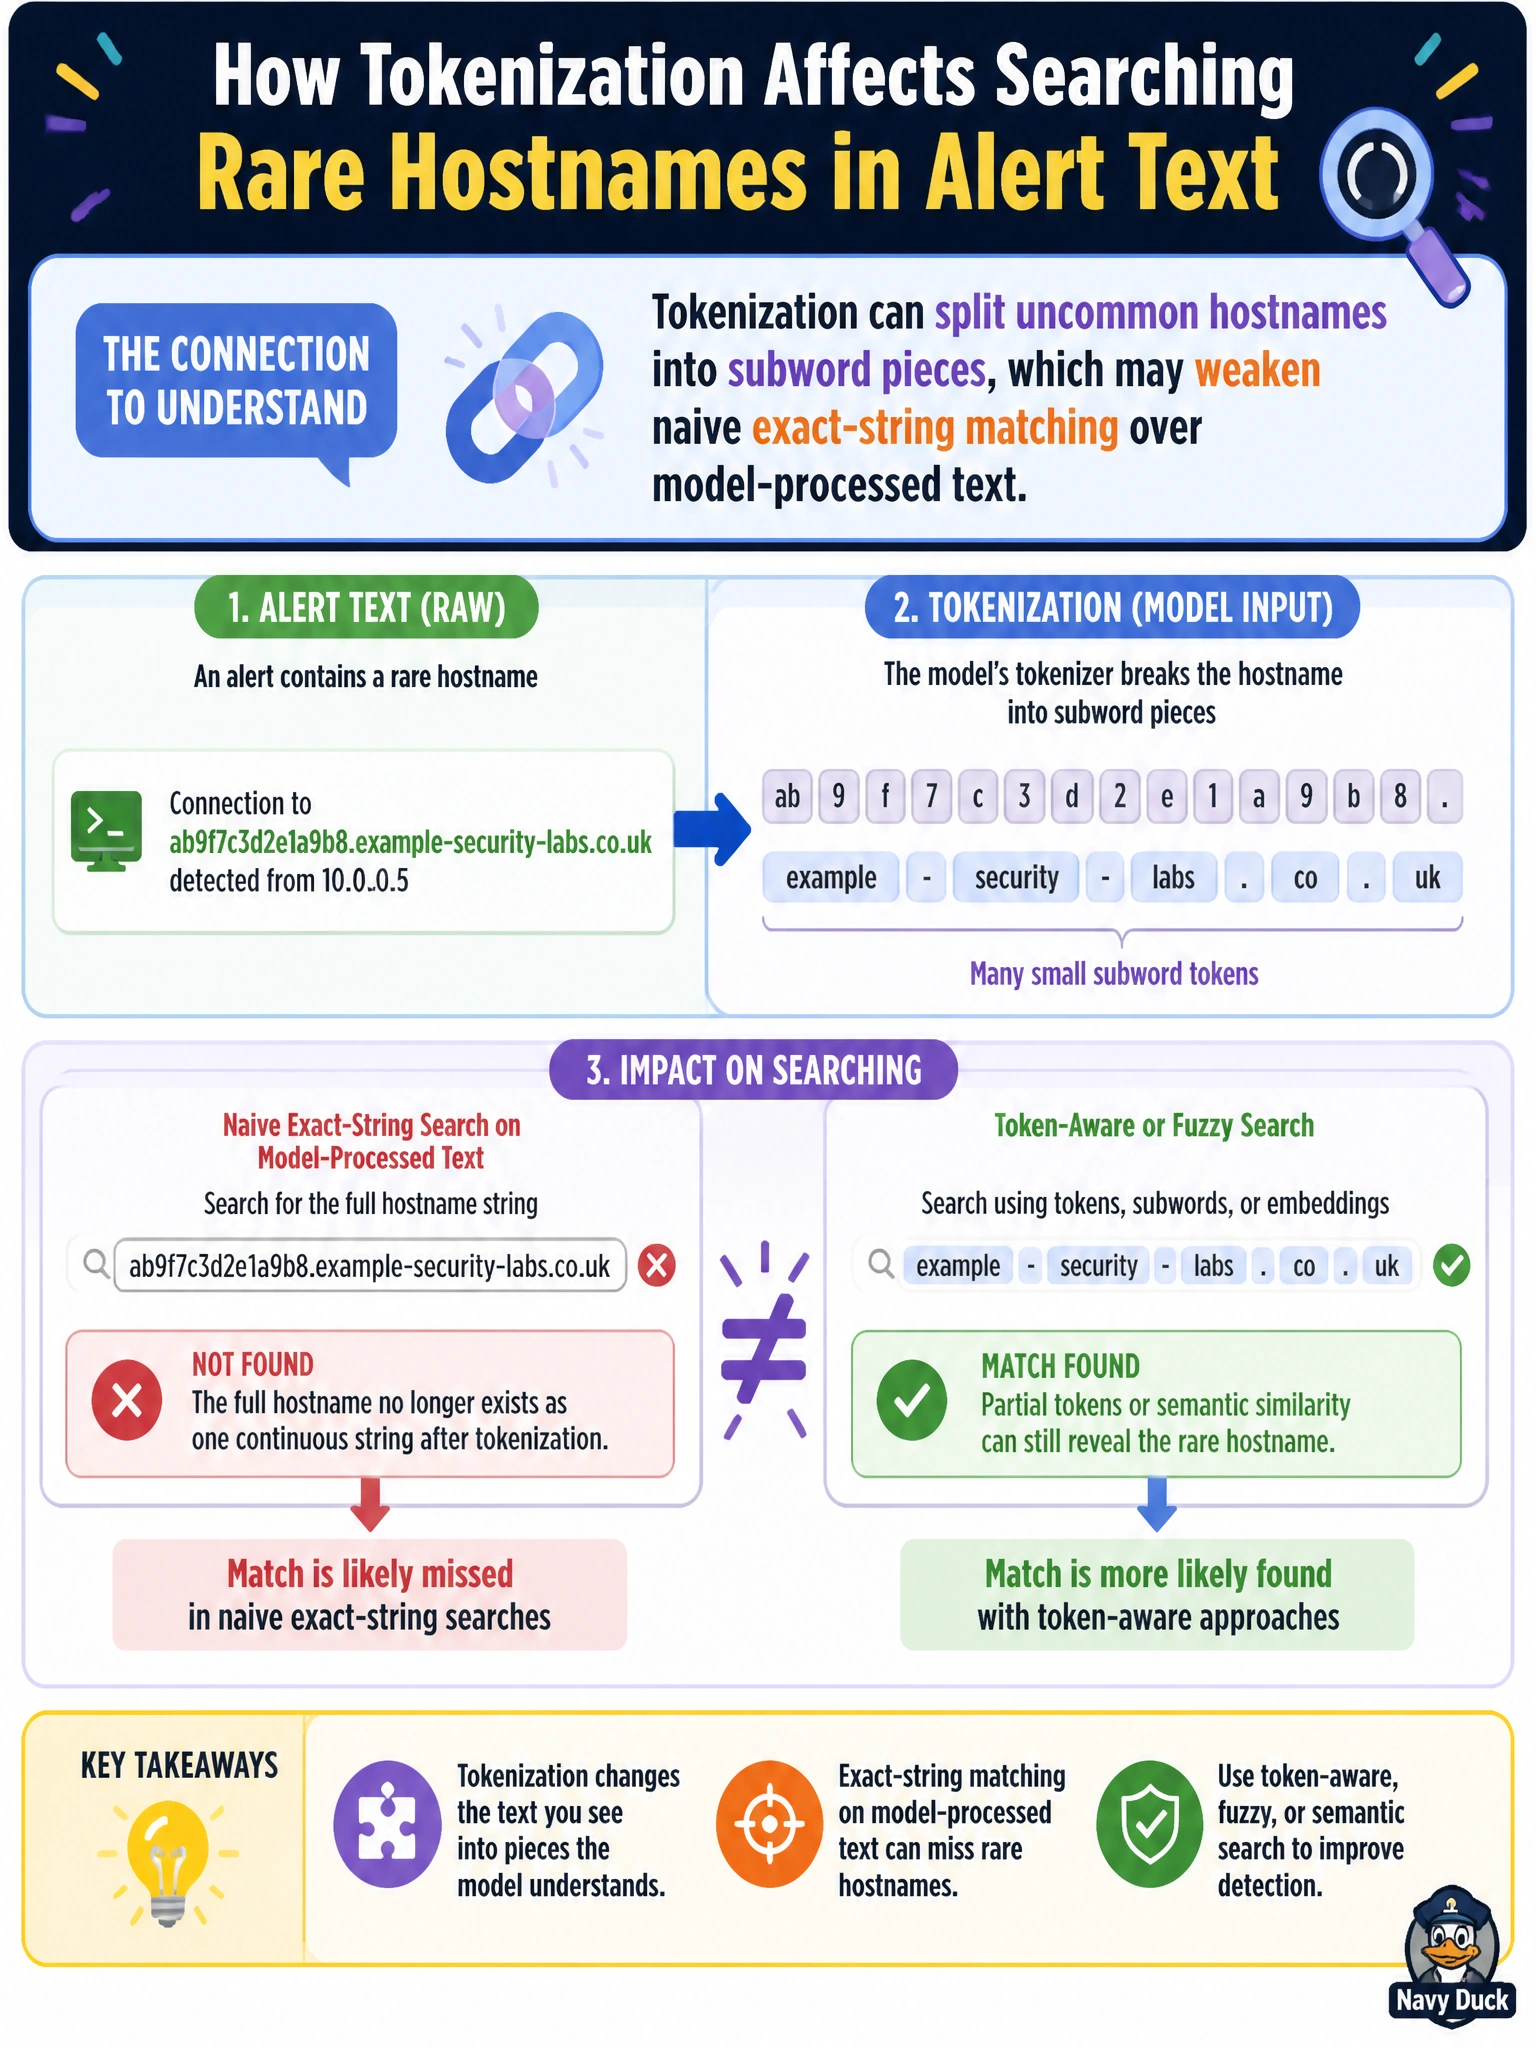
Odd hostnames get diced like a long street name into syllables. If the model sees pieces instead of the whole name, naive exact matching over that processed text can miss the rare label the IR team cares about.
Full Explanation
A county IR team asking how tokenization affects searching rare hostnames in alert text should understand that tokenization can split uncommon hostnames into subword pieces, which may weaken naive exact-string matching over model-processed text. Rare civic hostnames often fall outside common vocabularies, so subword tokenizers fragment them; downstream AI features that operate on tokens may not preserve a single searchable inventory string. IR workflows that assume unbroken hostname literals after AI processing can miss matches.
Claiming tokenization can attach surrounding DNS context to uncommon hostnames, which may shift naive exact-string matching over model-processed text, overstates what tokenization does — uncommon civic hostnames routinely fall outside common vocabularies and still get split into subword pieces that can defeat naive exact-string search. Tokenization does not replace uncommon hostnames with anonymized ID tokens, which may obscure naive exact-string matching over model-processed text; it is a text segmentation process that can break uncommon hostnames into subword pieces. Tokenization does not parse uncommon hostnames into structured indicator fields, which may alter naive exact-string matching over model-processed text; it processes raw text and may fragment hostnames rather than creating structured indicators.
Exam caveat: effects vary by tokenizer and whether the pipeline retains original raw text alongside embeddings or model output; always know which layer you are searching. Operational check: test county alert pipelines with known rare hostnames, compare exact-match success on raw SIEM fields versus AI-processed text, and prefer raw telemetry fields for inventory-critical hostname search when subword splits appear.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.