
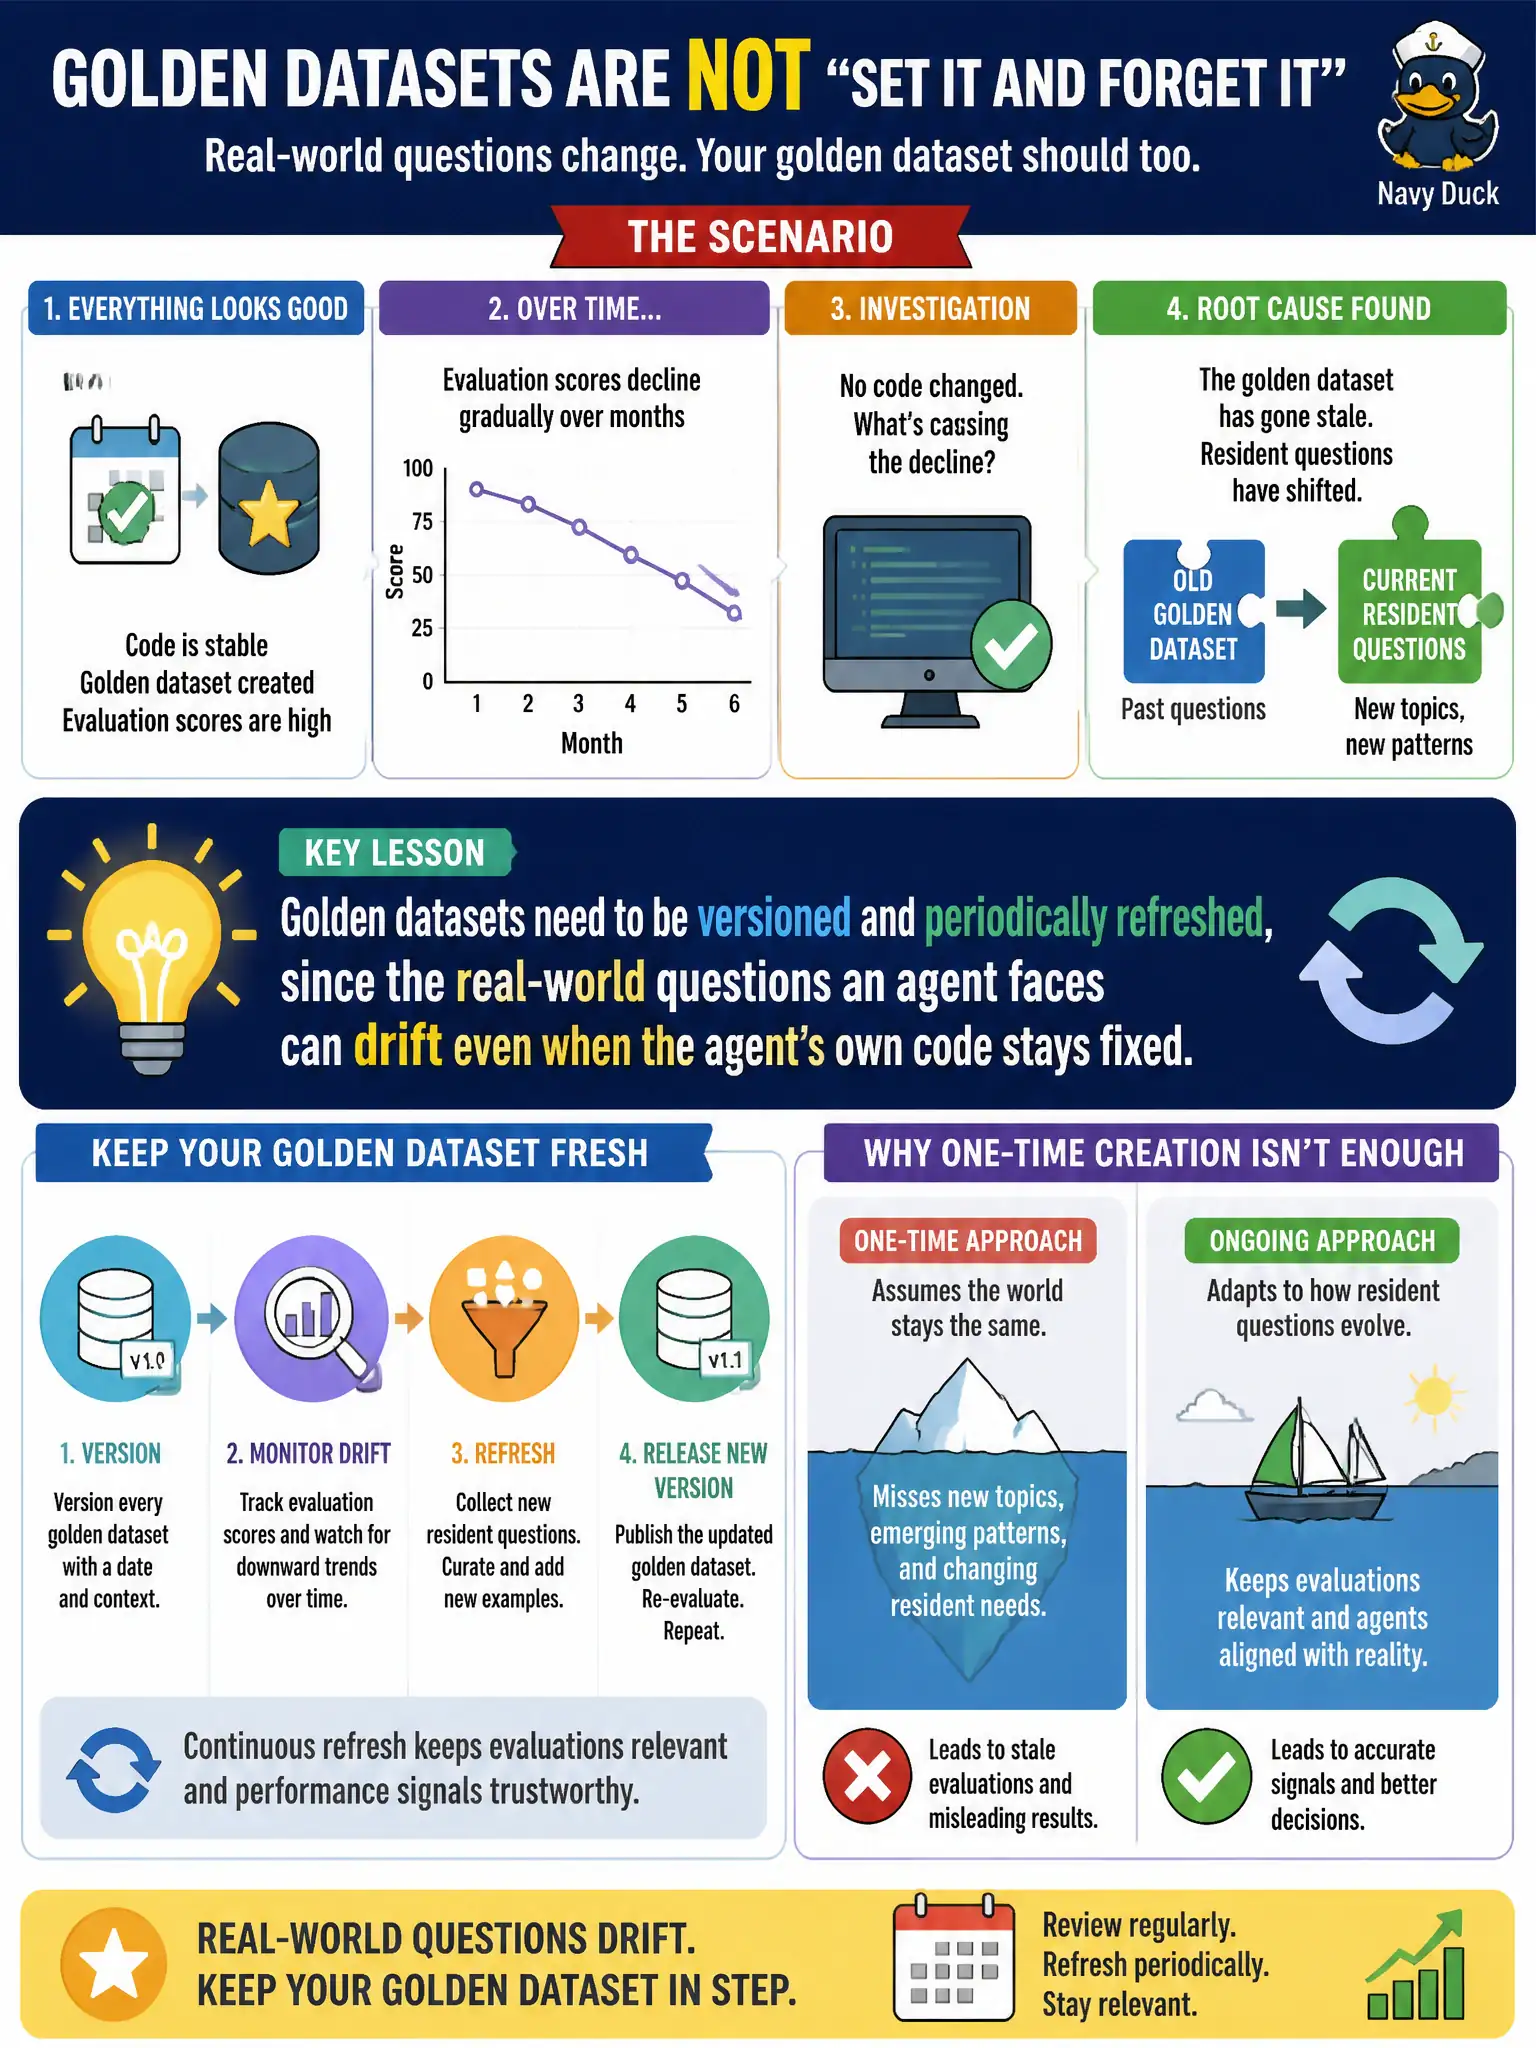
A library-programs assistant's evaluation scores decline gradually over several months even though no code changed. Investigating, the team suspects the golden dataset itself has gone stale relative to how resident questions have shifted. What does this scenario illustrate about golden datasets that a one-time creation approach misses?
Select an answer to reveal the explanation.
Short Explanation
A golden dataset is like a map of the neighborhood — accurate the day you drew it, but the streets keep changing while the map sits still in a drawer. If residents start asking new kinds of questions the map never anticipated, the agent starts scoring worse against reality even though nothing about the agent itself moved.
Full Explanation
Golden datasets encode a snapshot of expected inputs and correct outputs at the time they're built, but the population of real questions an agent faces isn't static — resident interests, program offerings, and phrasing patterns shift over months, so a fixed dataset gradually stops representing the traffic the agent actually handles, even while the agent's code remains unchanged. That drift is exactly what this scenario describes: falling scores with no code change points at the measurement instrument going stale, not at the thing being measured getting worse. Treating any code-free score decline as necessarily a tooling bug skips the more common explanation and could send the team debugging the wrong system. Assuming a validated dataset stays representative forever ignores that representativeness is a property of matching real-world distribution, which changes independently of the model. Dismissing a gradual, sustained decline as noise risks missing a real signal — genuine dataset staleness produces exactly this kind of slow drift rather than a sudden spike. Scope caveat: refreshing a golden dataset requires ongoing sampling of real (anonymized) resident questions to know what's shifted, not just re-running the same fixed set on a schedule. Operational check: compare a recent sample of real resident queries against the golden dataset's prompt topics and confirm the dataset still covers the categories residents are actually asking about now.