
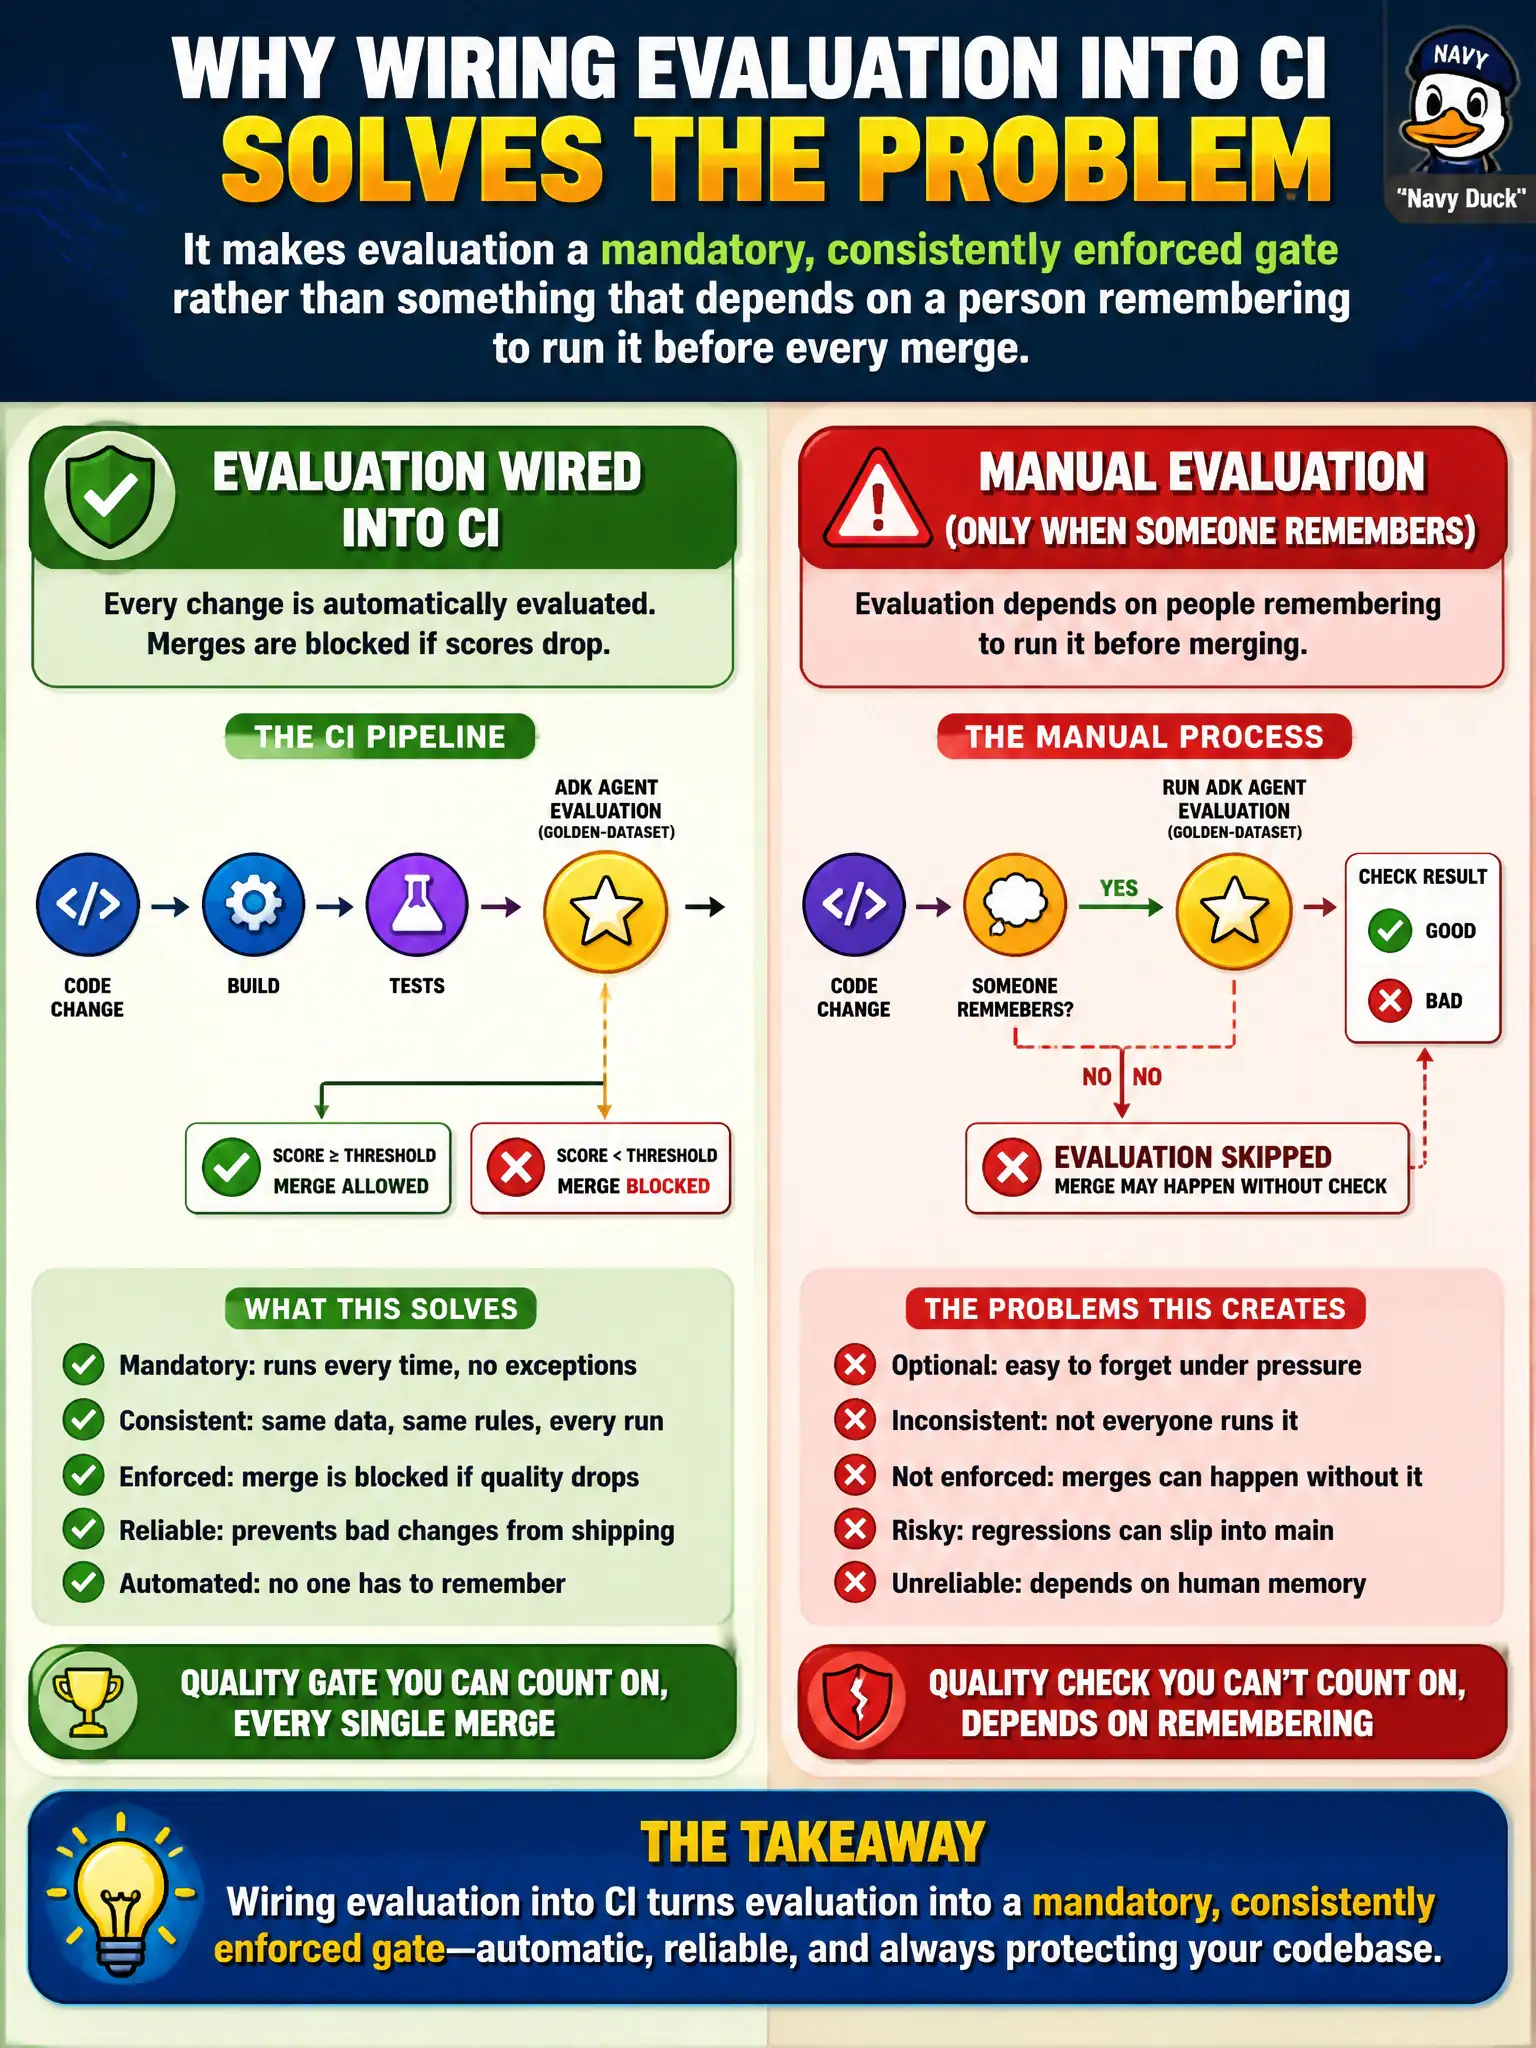
A county IT team wires their ADK agent's golden-dataset evaluation into the CI pipeline so that every code change automatically triggers a full evaluation run, and a merge is blocked if scores drop below a set threshold. What problem does wiring evaluation into CI solve that running the same evaluation manually, only when someone remembers to, does not?
Select an answer to reveal the explanation.
Short Explanation
A safety check that only runs when someone happens to remember is really just a suggestion. Wiring it into CI turns evaluation from a good habit into a locked door — no merge gets through without the golden dataset passing first, no matter who's in a hurry that day.
Full Explanation
The core value of CI-integrated evaluation is enforcement consistency: manual evaluation depends on a person choosing to run it, which is vulnerable to being skipped under deadline pressure, forgotten during a routine change, or applied inconsistently across contributors, while a CI-wired check runs automatically on every code change and blocks the merge if the golden-dataset scores fall below the set threshold, removing that human dependency entirely. This is an enforcement improvement, not a change to what's being measured or how much data is needed. Automated CI evaluation does not shrink dataset requirements — the same golden dataset still needs sufficient coverage to be meaningful, whether it's run manually or triggered automatically. No evaluation gate, automated or manual, can guarantee zero incorrect production responses, since the golden dataset only covers scenarios someone thought to include, and real traffic will always include cases outside that coverage. A pass/fail threshold still has to be explicitly defined by the team; CI enforces whatever threshold is configured, it doesn't invent one on its own. Scope caveat: a CI gate is only as strong as the threshold chosen, and a threshold set too loosely will pass regressions just as a manual check might have missed them. Operational check: confirm the CI configuration actually fails the build step when scores drop below threshold, rather than only logging a warning that a reviewer could ignore.