
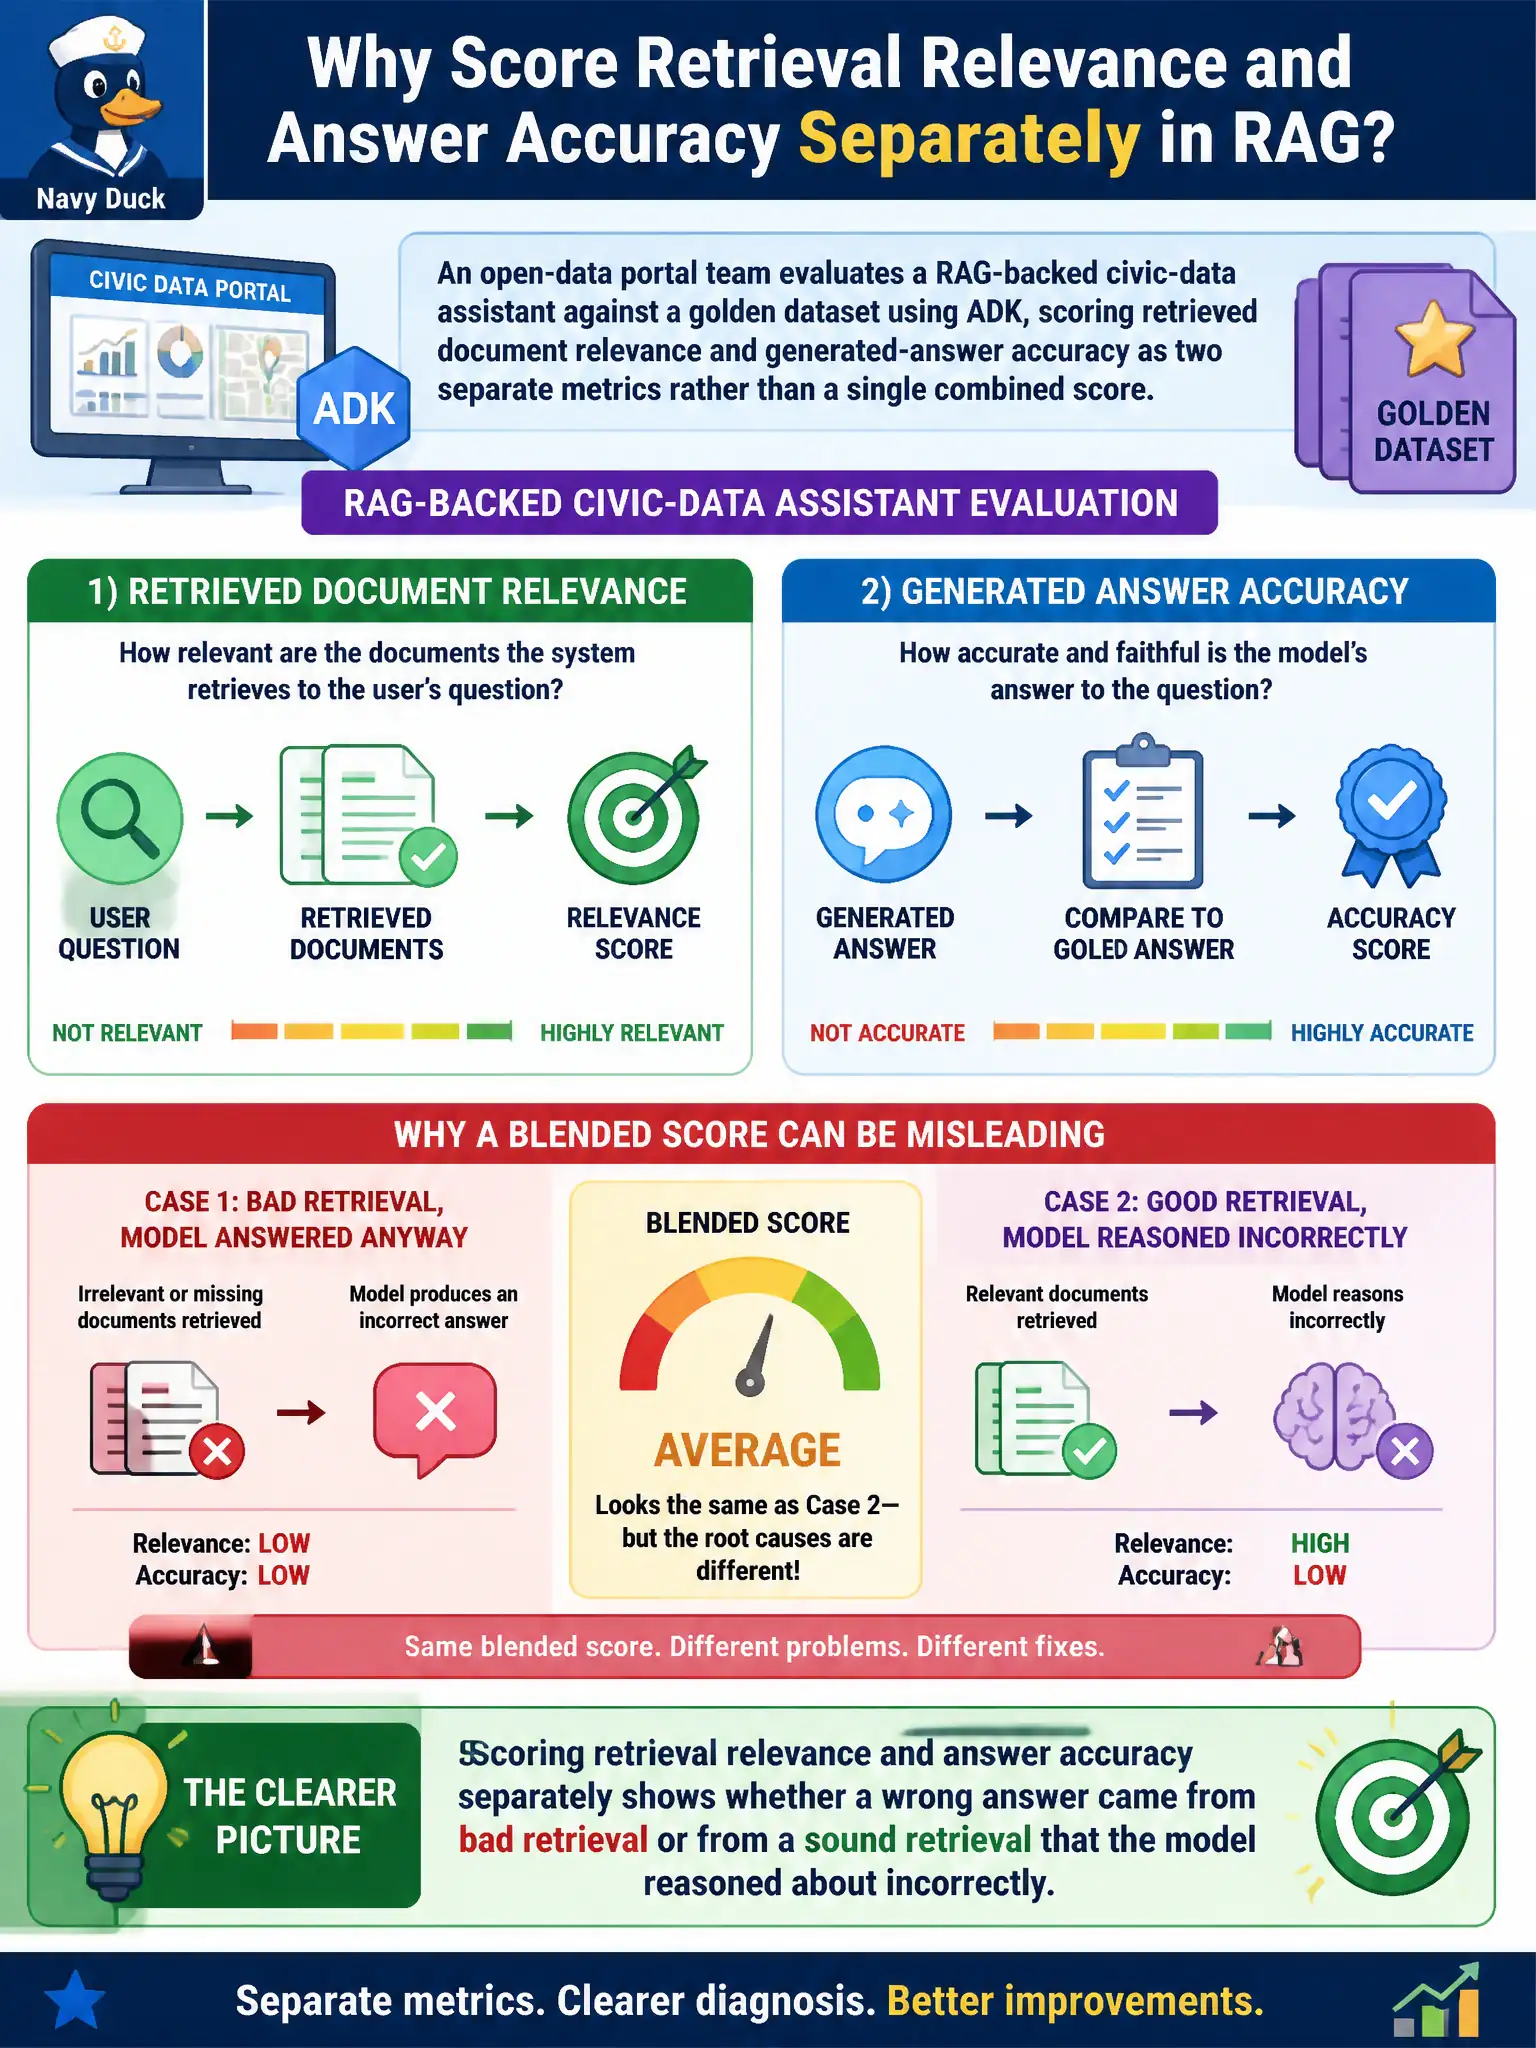
An open-data portal team evaluates a RAG-backed civic-data assistant against a golden dataset using ADK, scoring retrieved document relevance and generated-answer accuracy as two separate metrics rather than a single combined score. Why does scoring these two dimensions separately give the team a clearer picture than one blended score?
Select an answer to reveal the explanation.
Short Explanation
Think of a RAG agent as two workers: a librarian who fetches documents and a writer who turns them into an answer. If the final answer is wrong, one blended score can't tell you whether the librarian handed over the wrong book or the writer misread a good one — and separate scores can.
Full Explanation
Splitting retrieval quality from generation quality isolates two failure modes that require different fixes: poor retrieval points to the embedding model, similarity scoring, or reranking configuration, while poor generation with good retrieval points to prompt design or the model's reasoning over correct context. A single blended score collapses both signals into one number, so a low score gives no direction for where to intervene — the team could spend effort tuning the wrong component. This distinction is not an ADK mechanical requirement; it's a diagnostic choice the team makes because it produces actionable results, so framing it as something ADK forces misstates the reason. Claiming retrieval is inherently easier to measure mischaracterizes both metrics as fixed in difficulty rather than as complementary views into different pipeline stages. Separate scoring does not eliminate the need for a golden dataset covering retrieval — it actually requires one, since relevance can't be scored without a labeled set of expected-relevant documents per query. Scope caveat: separate scores still need to be read together, since a system can show strong retrieval and weak generation, or the reverse, and only the pairing tells the full story. Operational check: for a query with a low overall score, check whether the retrieval-relevance metric or the answer-accuracy metric is the one that dropped before deciding where to invest.