
A square weight matrix needs to be inverted as part of a closed-form solution. Under which condition does that inverse actually exist?
Select an answer to reveal the explanation.
Short Explanation
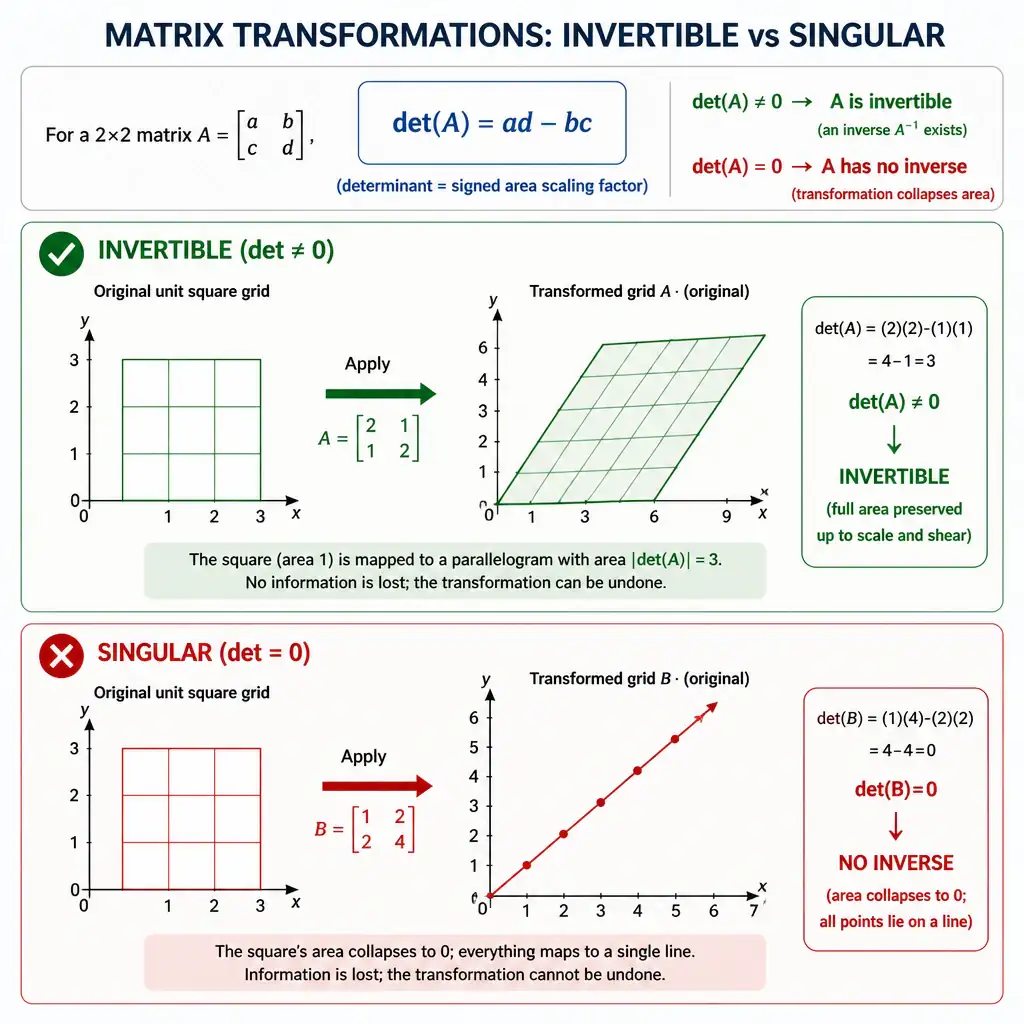
Here's the deal: you can invert a square matrix only when its determinant isn't zero. If the determinant is zero, the transformation squashes space and you can't undo it, so there's no inverse. Symmetry and positive entries don't prove invertibility.
Full Explanation
A square matrix is invertible (also called non-singular) if and only if its determinant is non-zero. This is because the determinant represents the scaling factor of the linear transformation that the matrix represents; when the determinant is zero, the transformation collapses the space into a lower dimension (rank deficiency), meaning information is irreversibly lost and no matrix can map the output back to a unique input. Equivalent conditions include: the matrix has full rank, its columns (and rows) are linearly independent, and the only solution to the homogeneous equation is the zero vector.
The condition that the determinant equals zero states the opposite of the truth — a zero determinant is precisely the condition under which a matrix is singular and cannot be inverted, so that condition describes non-invertibility, not invertibility.
The condition that the matrix is symmetric across its main diagonal is incorrect because symmetry is an unrelated structural property. Many symmetric matrices are perfectly invertible, but symmetry alone offers no such guarantee: a matrix filled entirely with the same repeated value, for instance, can be symmetric yet singular (determinant zero) because its rows are linearly dependent.
The condition that the matrix has all positive entries fails for the same kind of reason: the sign of the matrix's entries has no bearing on whether the determinant vanishes. A matrix of all positive numbers can easily have linearly dependent rows and thus a zero determinant.
In deep learning contexts, this matters directly: computing a closed-form solution such as ordinary least squares requires inverting the Gram matrix formed from the design matrix, and if the design matrix has redundant or perfectly correlated features, that Gram matrix becomes singular, forcing practitioners toward regularization (ridge regression) or a pseudoinverse instead. A useful memory aid: 'zero determinant, zero chance of inverting.'