
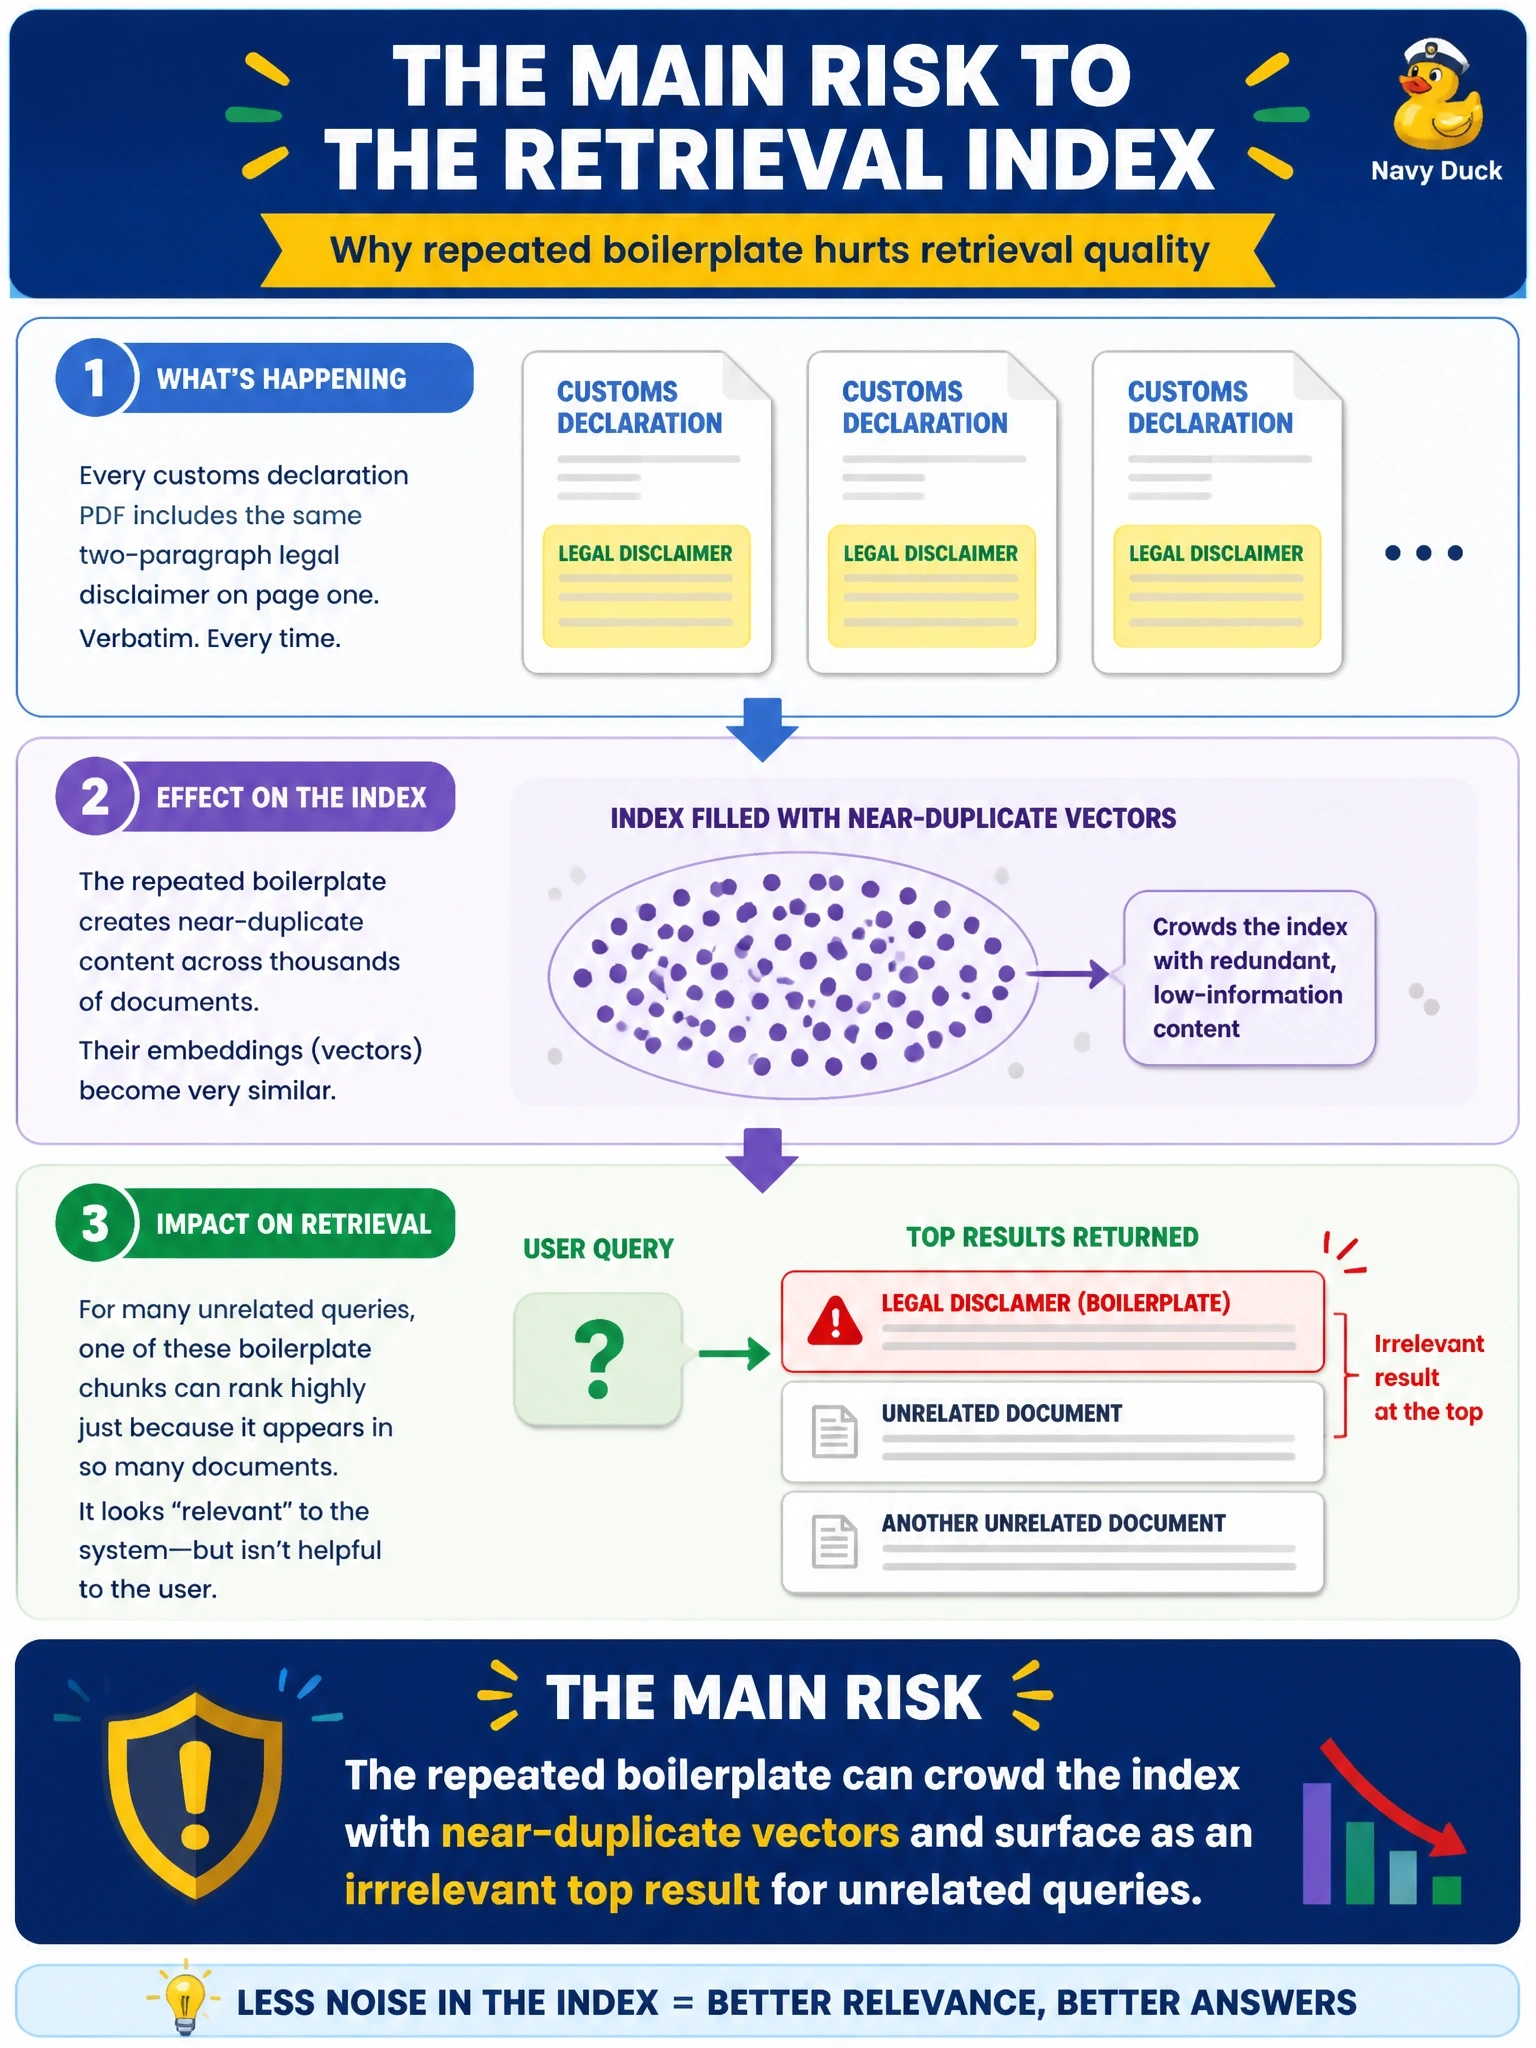
Every customs declaration PDF that Meridian's brokers file includes an identical two-paragraph legal disclaimer on page one, repeated verbatim across thousands of filings. Left in the corpus, what is the main risk to the retrieval index?
Select an answer to reveal the explanation.
Short Explanation
When the exact same disclaimer shows up in every filing, its vector effectively becomes the 'average' point of your whole index - so if a query is even vaguely generic, that boilerplate paragraph can out-rank the actual answer purely by sheer repetition, not relevance.
Full Explanation
The main risk is that thousands of near-identical boilerplate vectors crowd the index and can surface as top results for queries that have nothing to do with the disclaimer's content, purely because the same phrasing appears so often that its embedding neighborhood becomes densely populated. This is a real and common retrieval-quality failure mode, not a cosmetic one. Claiming the disclaimer only costs disk space is wrong because it understates the harm - the problem is not storage, it is that duplicated low-information text pollutes the similarity ranking and pushes substantive results down. Claiming the embedding model will fail on the document is wrong because embedding models do not error out on repeated or boilerplate text; they will happily produce a (low-information) vector for it, which is precisely why the problem is silent rather than loud. Claiming Unity Catalog rejects duplicate row text is wrong because Delta tables in Unity Catalog have no such uniqueness constraint on text content by default, and even if they did, the disclaimer text differs per filing only in surrounding context, not verbatim in every case, so a hypothetical uniqueness rule would not reliably catch it anyway. The fix implied by this diagnosis is filtering the boilerplate out during data preparation, before it ever reaches the index.