
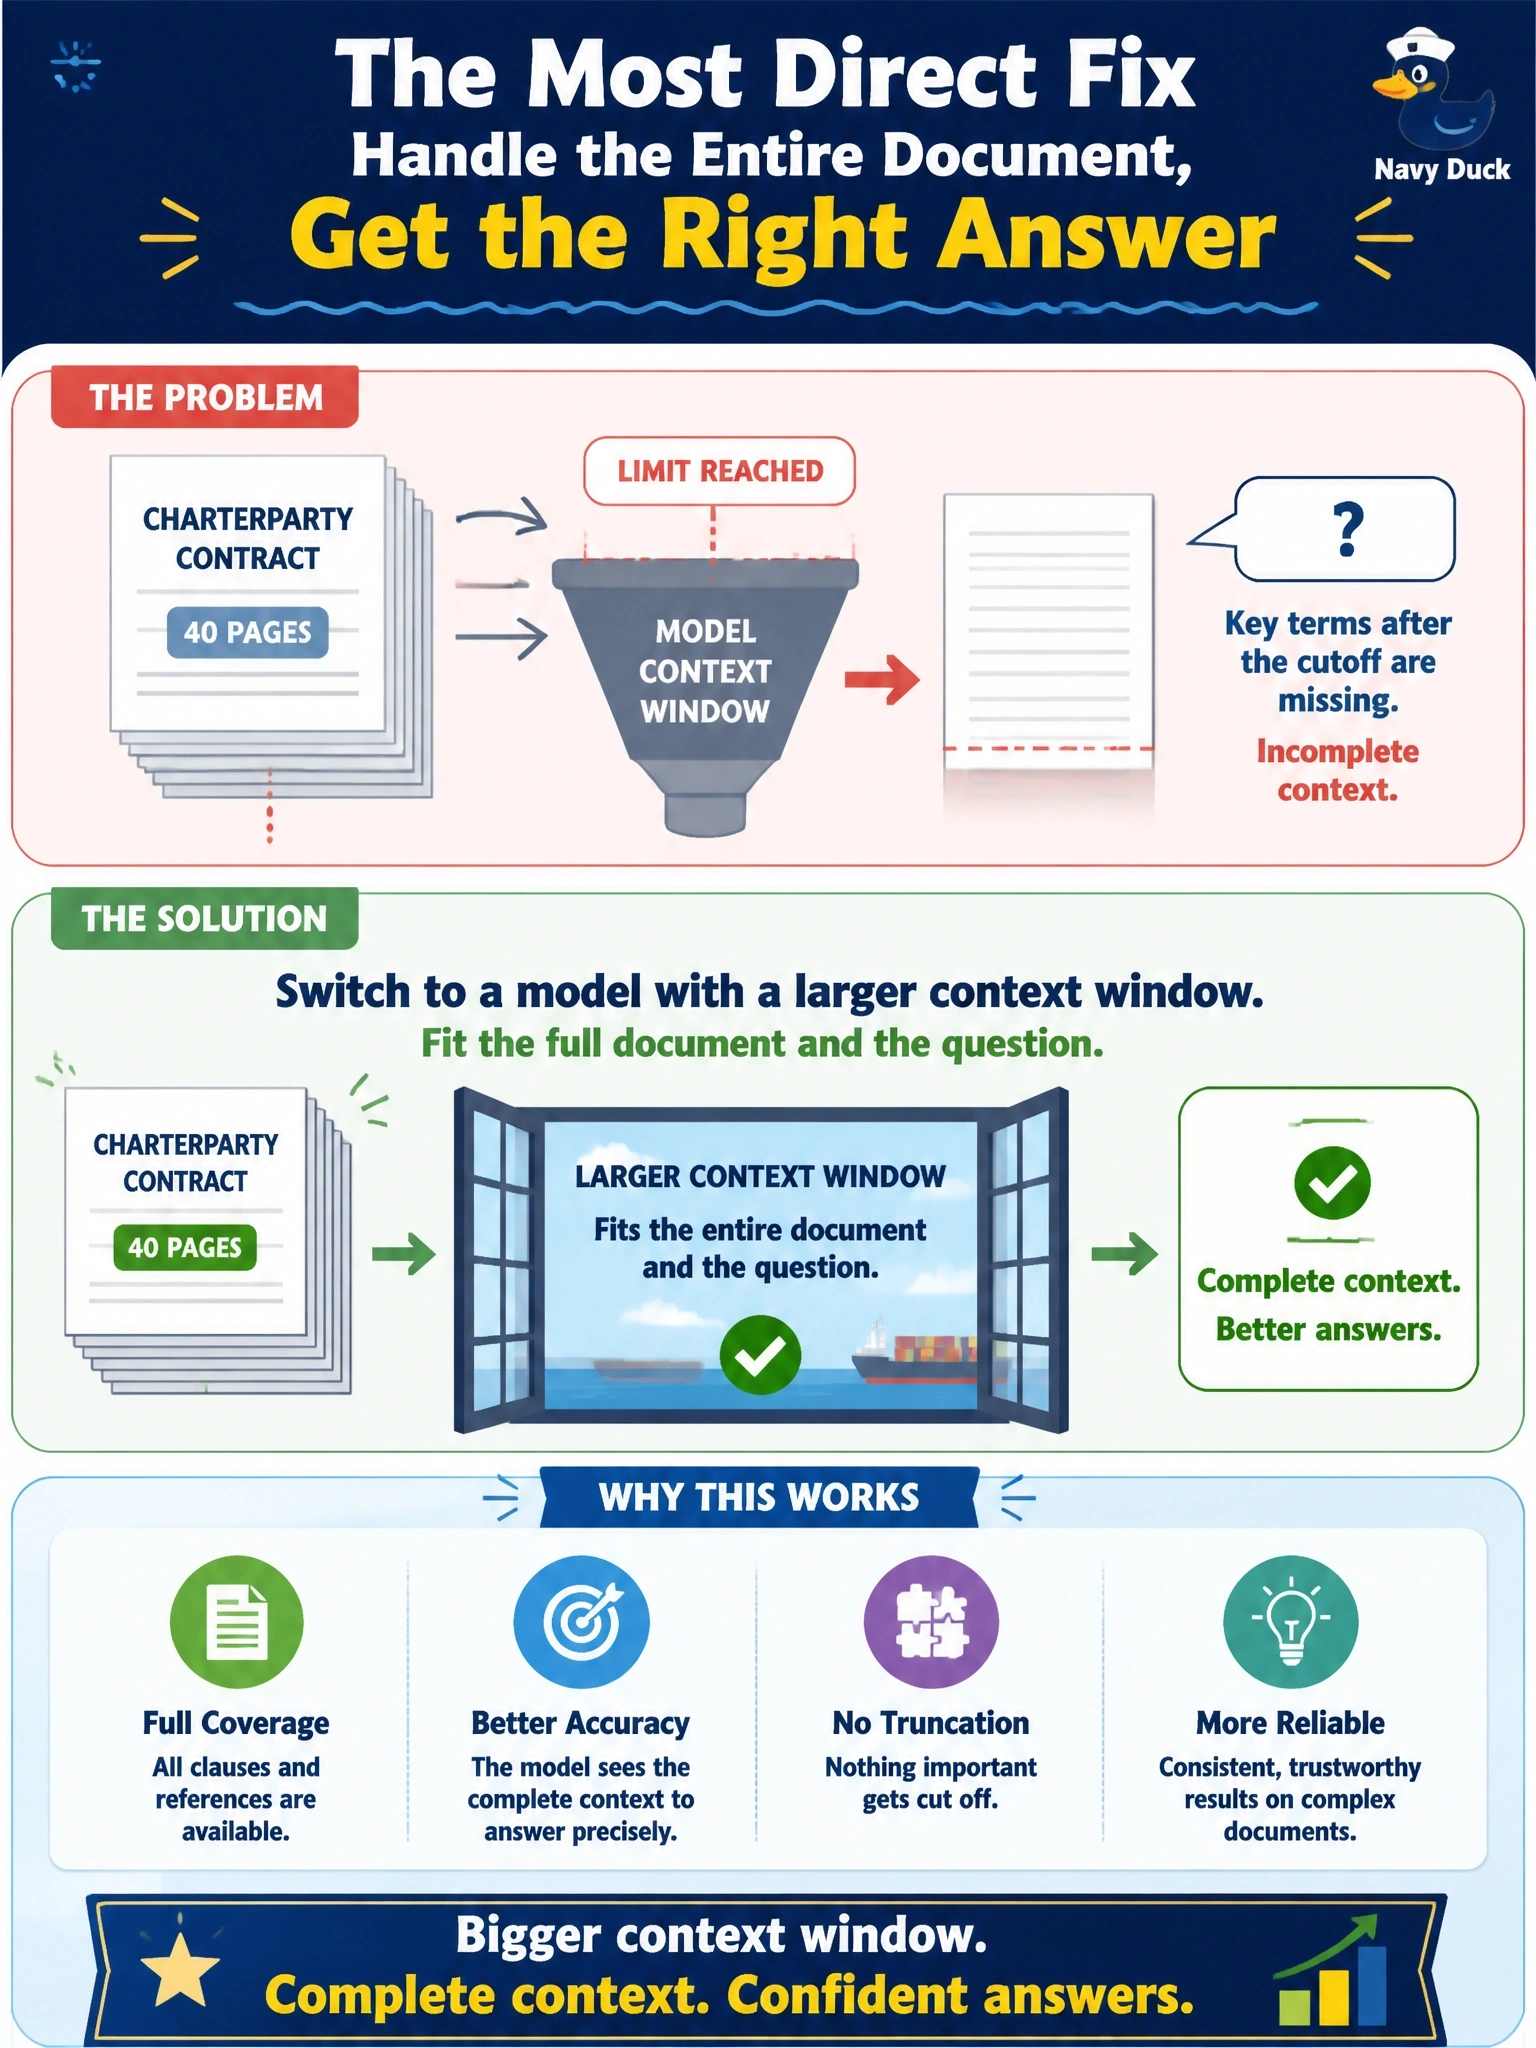
A charter-desk question sometimes needs the entire 40-page charterparty contract retrieved as context because the relevant terms are scattered across many clauses, and the currently selected model's context window truncates the input before the question even reaches the end of the document. What is the most direct model-selection fix?
Select an answer to reveal the explanation.
Short Explanation
If you need the entire 40-page contract in the prompt, you need a model whose context window can hold the document and your question. That’s a capacity issue, not something you can fix by changing the wording or temperature.
Full Explanation
Context window size is a model-selection variable: when the required input exceeds a model’s limit, the direct fix is to choose a model with a larger window that can accommodate the full document and question. Lowering temperature changes the randomness of generated output; it does not increase how much input the model can accept, so truncation remains. Asking the question twice does not create more room for the charterparty and uses additional tokens in an already insufficient window. Choosing a smaller, lighter model does not reduce the amount of source context needed to ground an answer about the full contract; smaller model families often have smaller windows, which may make truncation more likely. The key distinction is between a model’s ability to process the required input and settings that affect how it uses that input. Exam caveat: context length is one model-selection criterion to weigh alongside cost, latency, and quality, and is a named Section 3 objective. As a practical check, compare the model’s stated context limit with the token count of the entire charterparty plus the question, and allow enough room for the answer as well.