
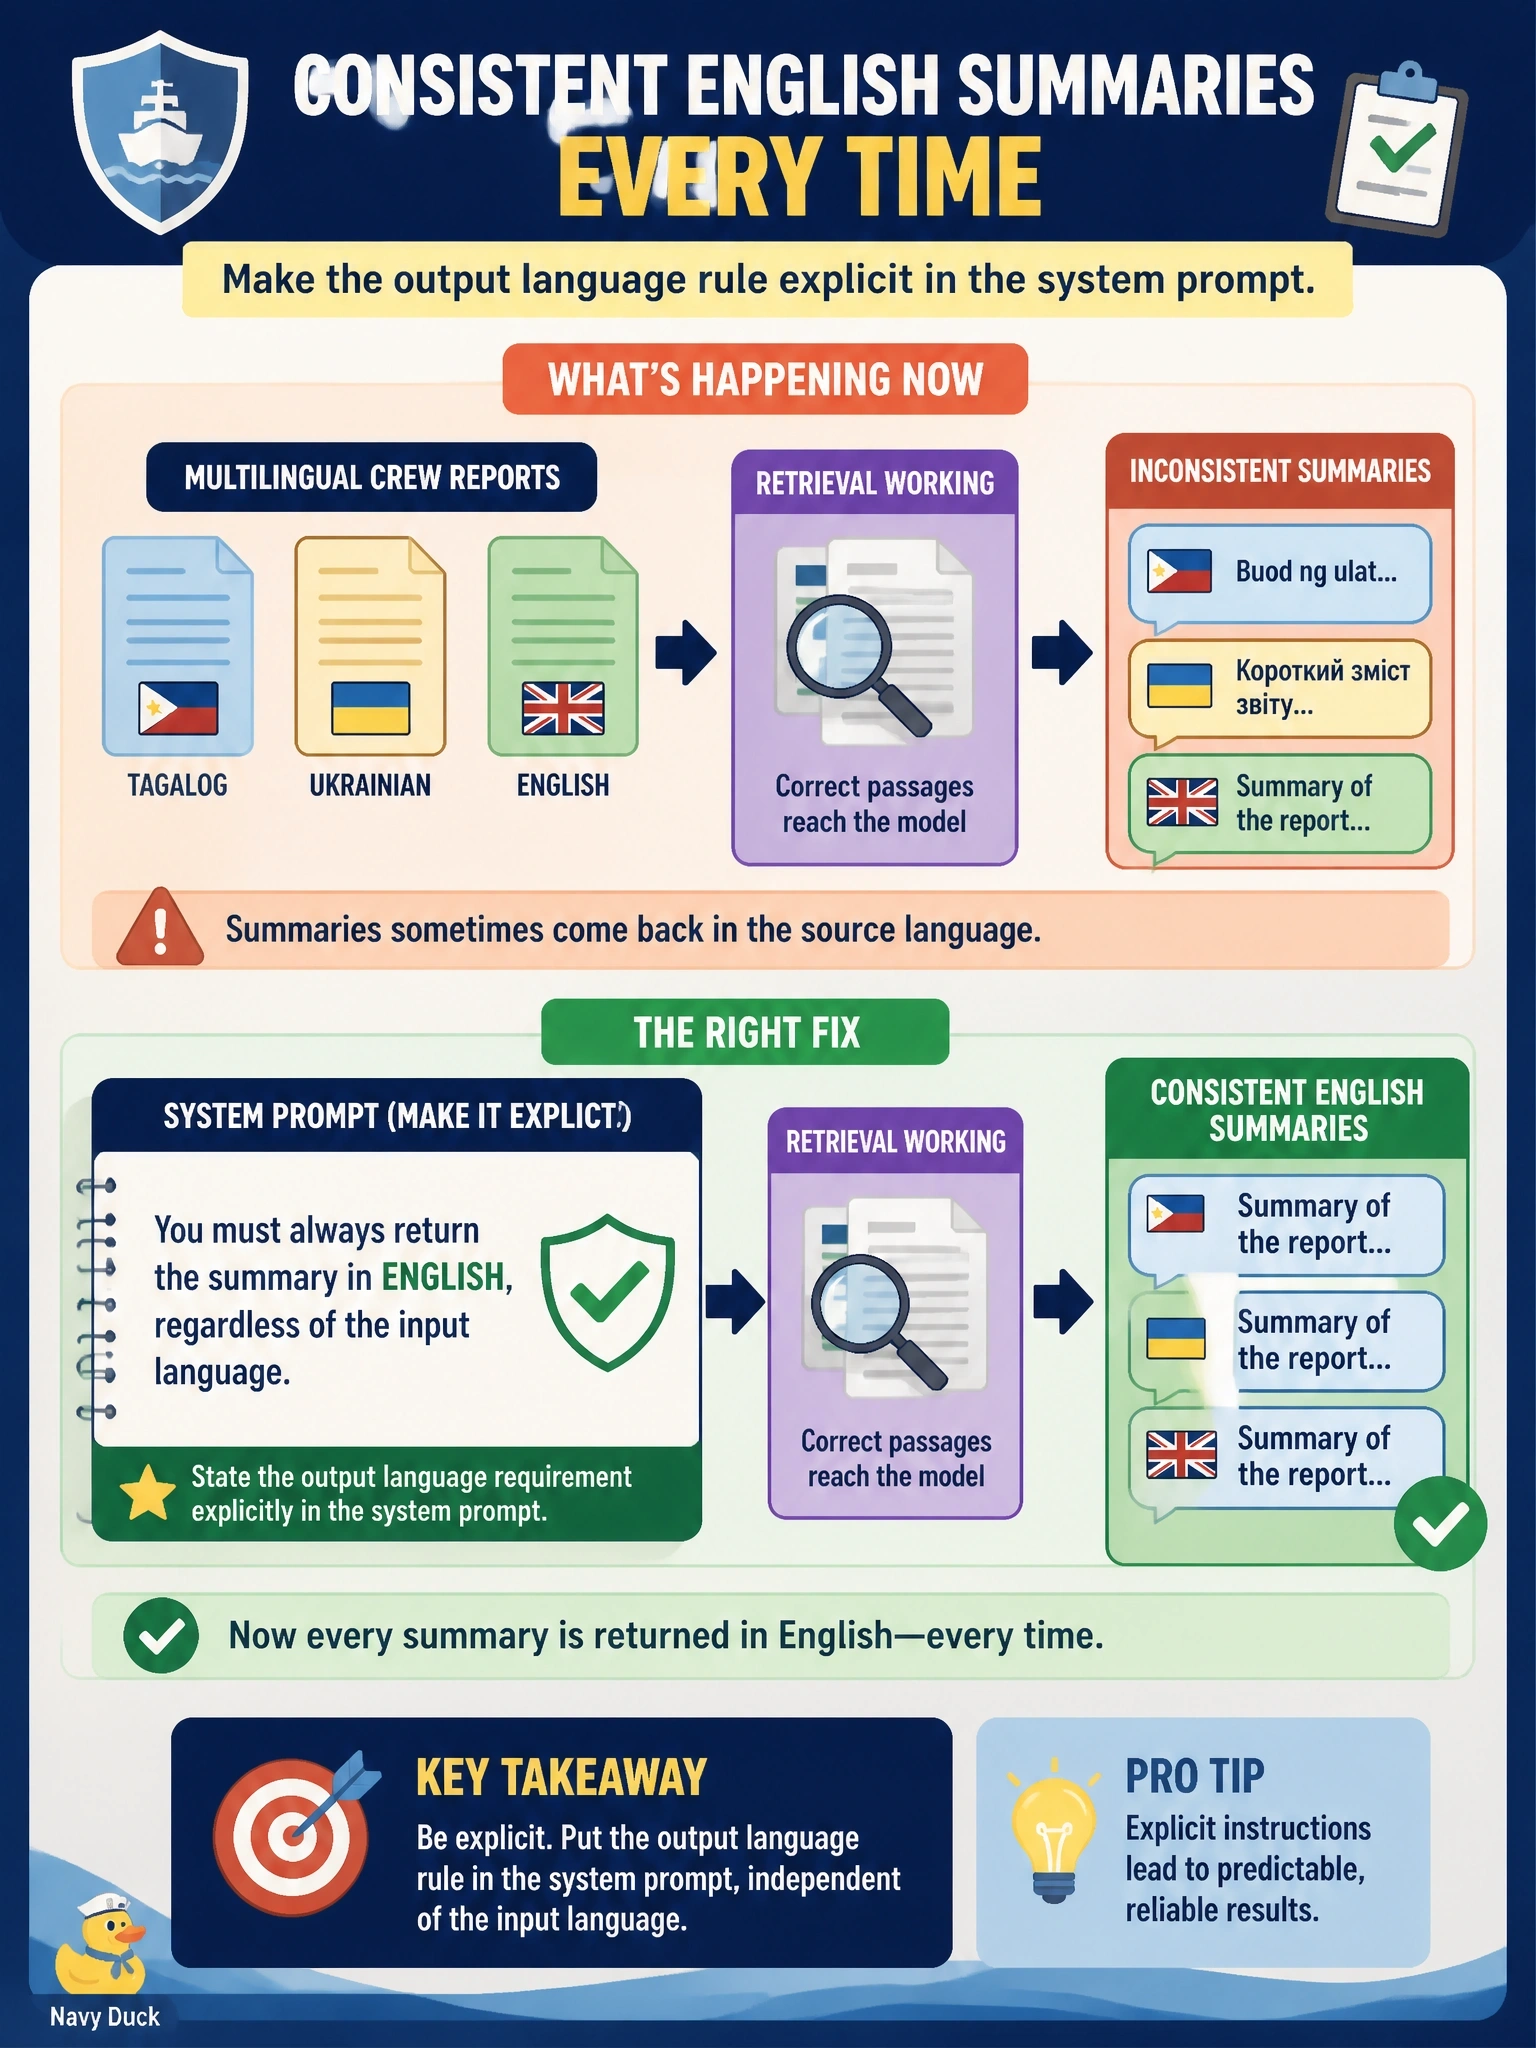
Meridian Line's crew reports are filed in Tagalog, Ukrainian and English, and the safety-review summarizer must return every summary in English regardless of source language. Retrieval is working and the correct passages are reaching the model, but summaries sometimes come back in the source language. What is the appropriate fix?
Select an answer to reveal the explanation.
Short Explanation
You can keep the original reports in their source languages and still require English summaries. State that requirement plainly in the system prompt: input language and output language are separate decisions.
Full Explanation
Multilingual models may continue in the input language, so reports in Tagalog, Ukrainian, and English can produce summaries in different languages unless the output language is explicitly required. Stating “summarize in English regardless of the source language” in the system prompt directly addresses the requirement while keeping input and output language independent. Translating all reports during ingestion is a possible architecture, but it can lose nuance and the audit trail in safety narratives, and introduces translation-quality risk before indexing; it is unnecessary when the model can be instructed to answer in English. Routing queries to models by detected language adds operational complexity for a problem one instruction solves, and detection may fail on code-switched reports. Setting temperature to zero reduces sampling variation but does not specify which language the model should use. Exam caveat: a multilingual corpus still needs a multilingual or cross-lingual embedding model for reliable retrieval, even though retrieval is already working in this scenario. Practical check: test the same summarization instruction with retrieved passages in each source language and confirm that every summary is in English; where legal fidelity matters, retain the original report and store any translation alongside it rather than replacing it.