
An ice-rink skate-rental team already stores comments, logs, and counts in their test-management tool. They want GenAI help with monitoring. What should the monitoring prompt primarily do?
Select an answer to reveal the explanation.
Short Explanation
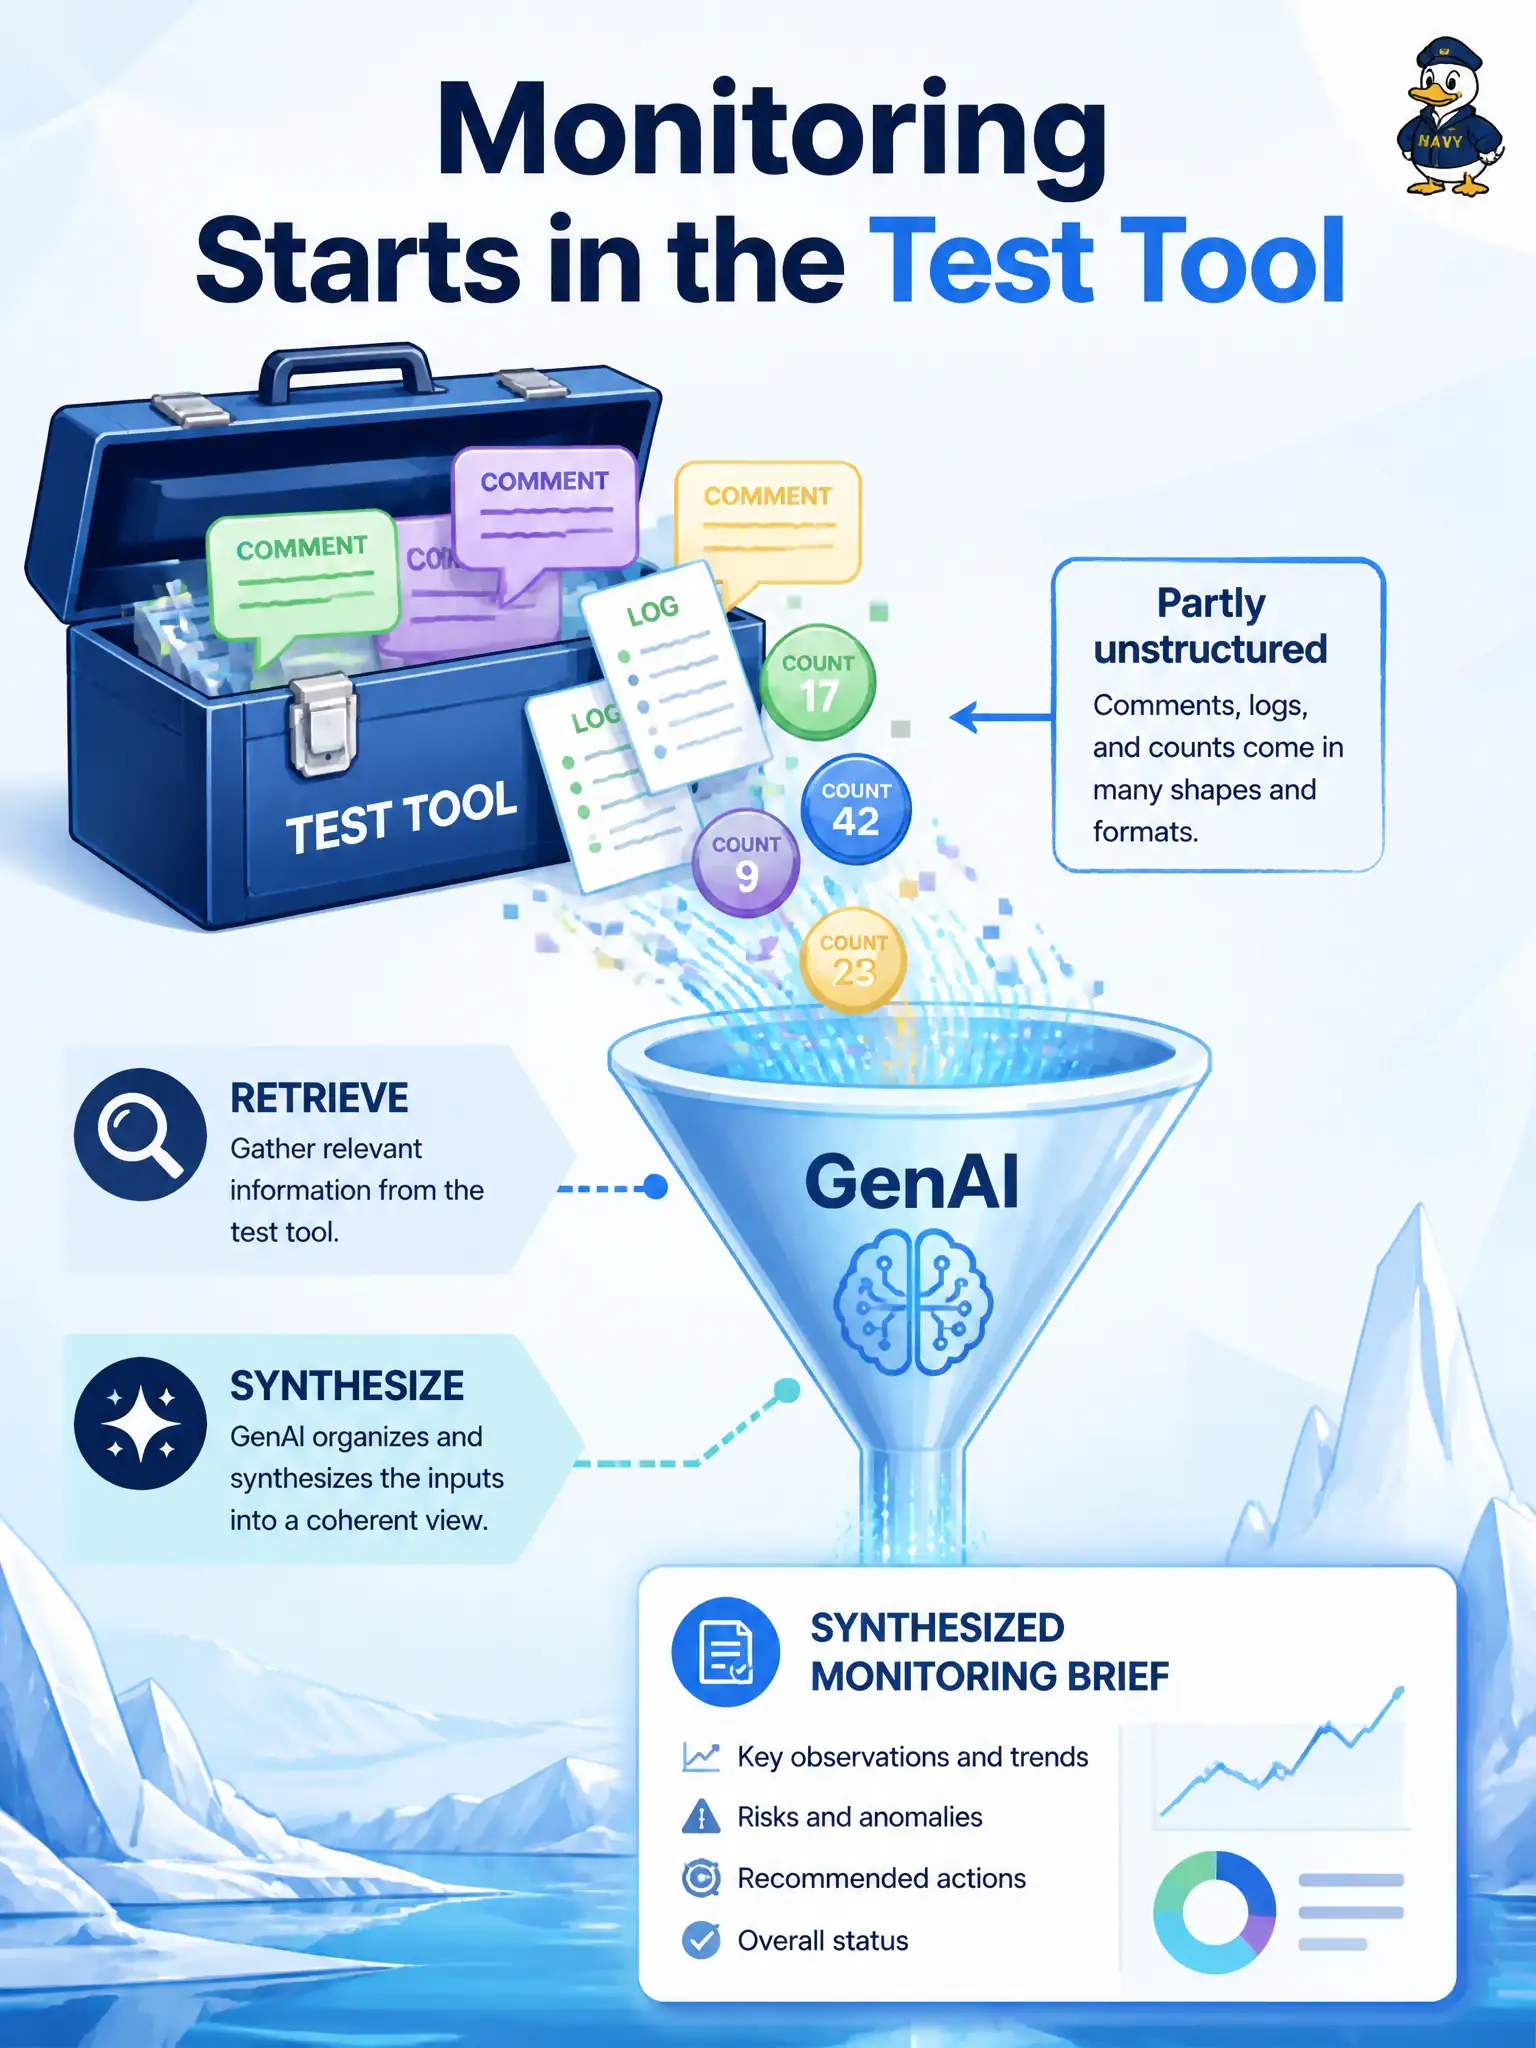
The good news is the data is already in the tool—comments, logs, and counts. Your prompt should pull that pile together, not invent a new model factory.
Full Explanation
When an ice-rink skate-rental team already stores comments, logs, and counts in their test-management tool and wants GenAI help with monitoring, the monitoring prompt should primarily ask GenAI to retrieve and synthesize that large, partly unstructured set of comments, logs, and counts. Civic recreation QA improves when scattered evidence becomes coherent signals about progress and risk. Asking GenAI to invent a new large-language-model architecture for skate rentals fails as unrelated research scope. Ignoring tool data to rely only on pretraining about ice rinks fails because monitoring must use the project’s actual civic evidence. Jailbreaking the test-management tool’s chatbot to “prove security coverage” fails by concept and ethics relative to ordinary monitoring synthesis. Exam caveat: monitoring assistance is chiefly retrieval-plus-synthesis over existing TM artifacts. Operational check: authorize read access to the municipal TM project, prompt GenAI to cluster comments and reconcile counts with logs, spot-check synthesized themes against raw entries, and update the rink dashboard only with verified civic findings. Keep civic stakeholders informed of residual risk and re-check the decision after the next monitoring cycle so public service quality remains auditable.