
A town-hall livestream-caption test manager needs non-testers to understand progress before tonight’s broadcast. Which GenAI prompt best helps?
Select an answer to reveal the explanation.
Short Explanation
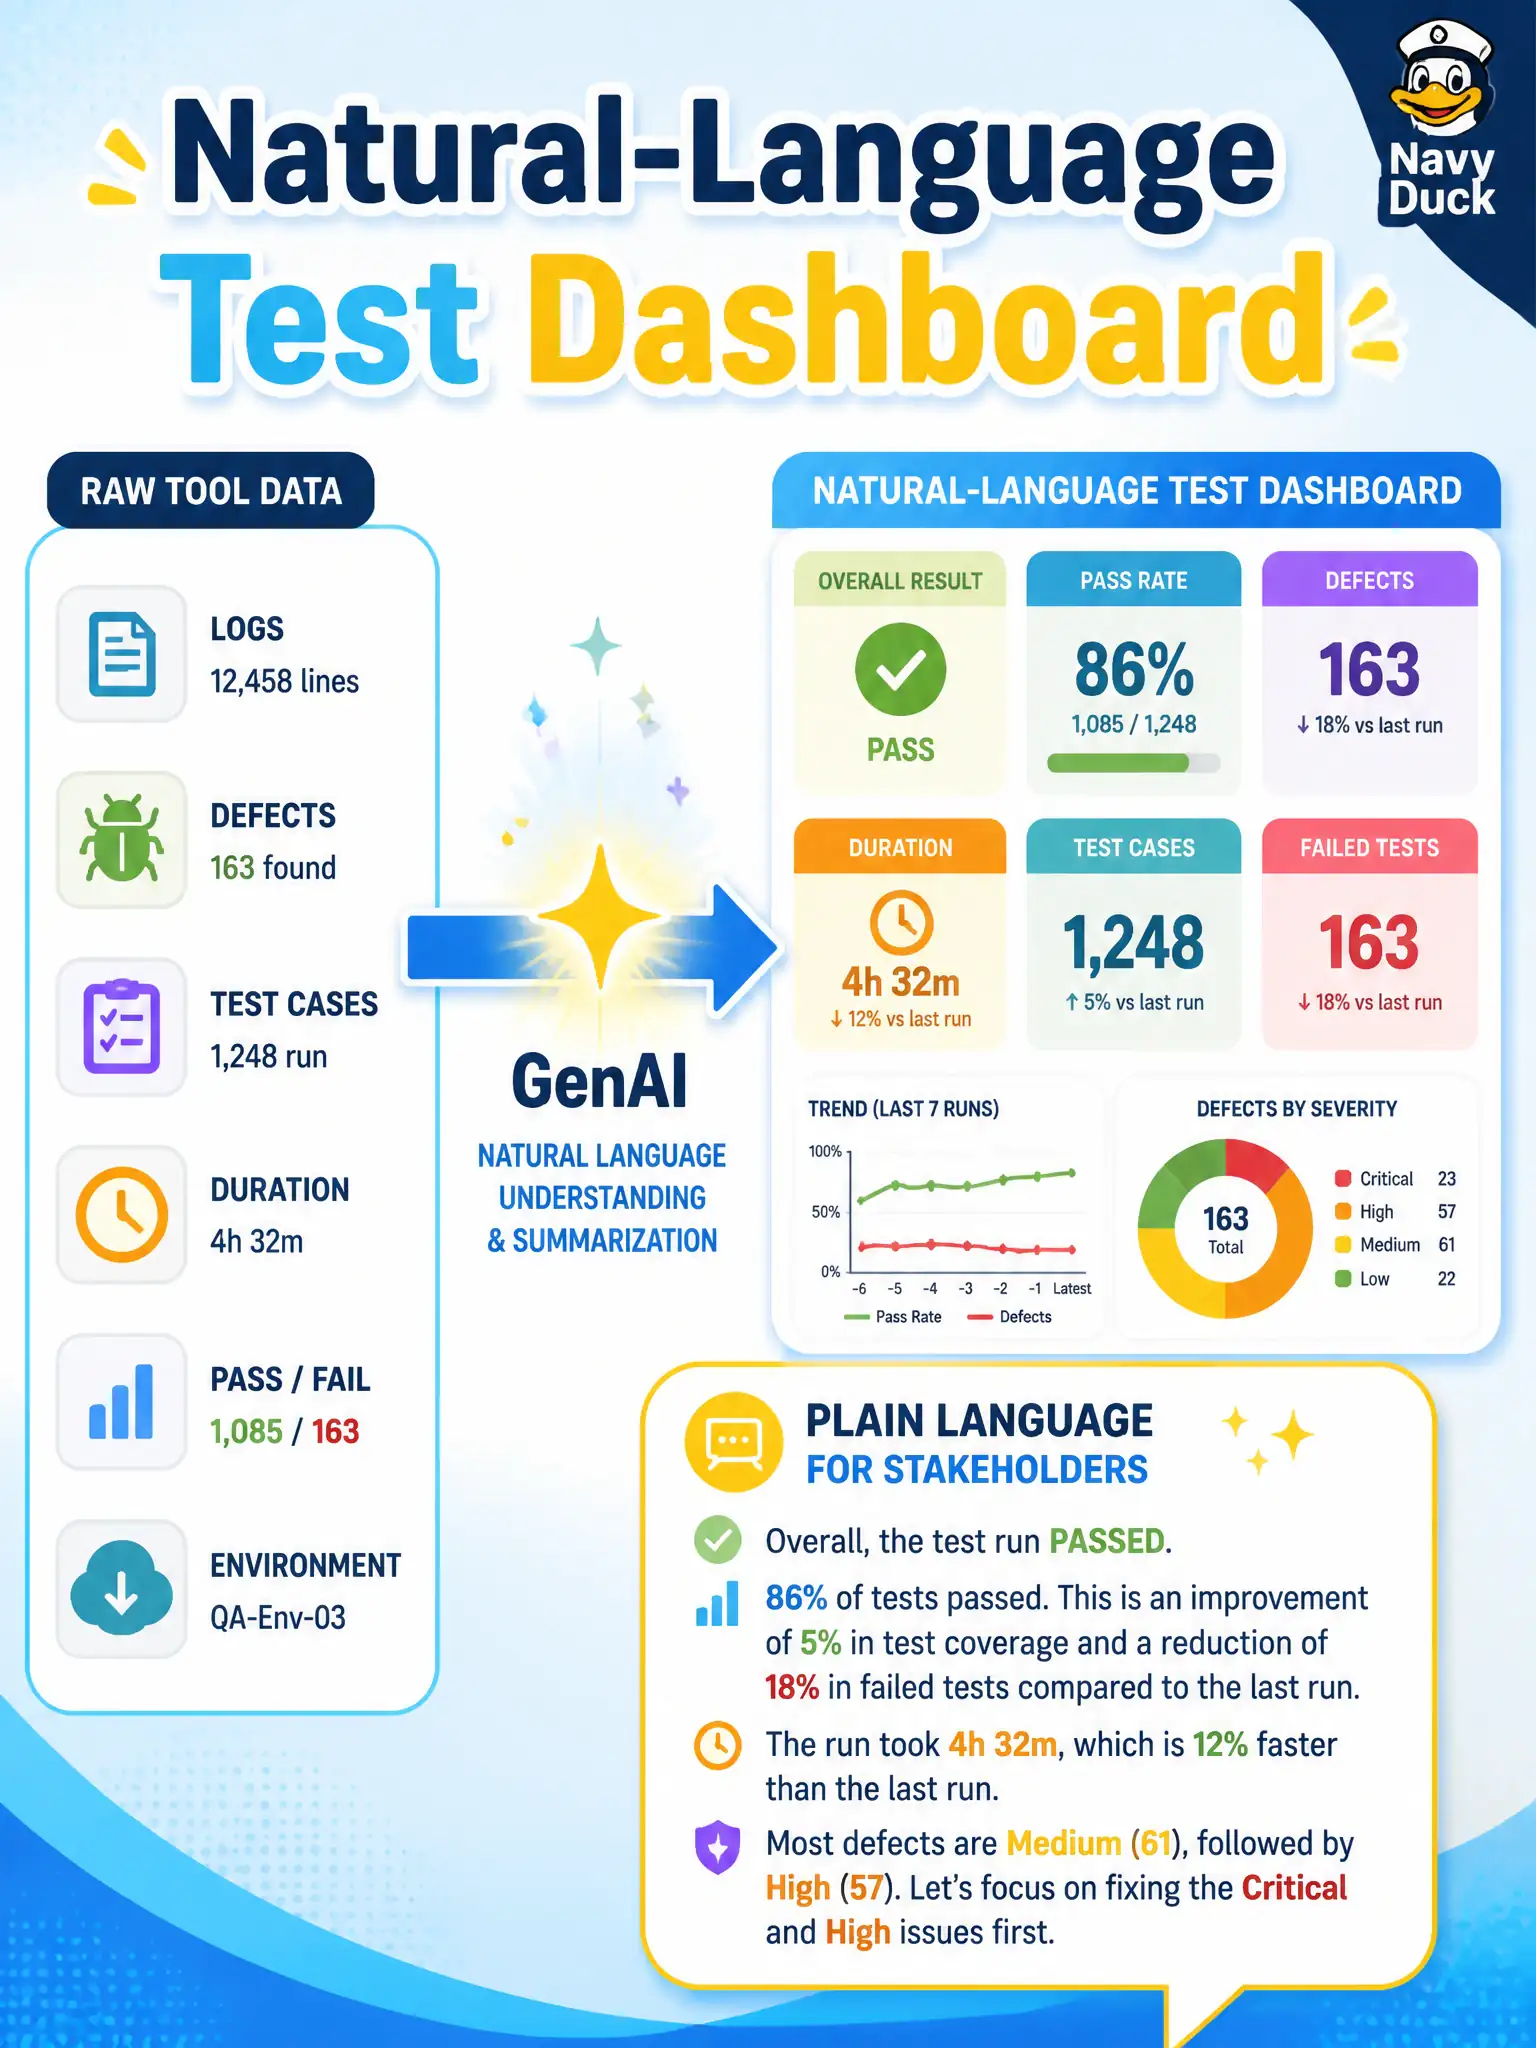
Stakeholders need a scoreboard in plain English, not a pile of raw tool exports. GenAI can turn the numbers into a dashboard and a friendly summary.
Full Explanation
A town-hall livestream-caption test manager who needs non-testers to understand progress before tonight’s broadcast should prompt GenAI to turn tool data into a dashboard plus a natural-language summary stakeholders can read. Civic transparency before a public meeting depends on understandable status, not only specialist scripts or model metrics. Generating keyword-driven scripts for every caption edge case while skipping stakeholder reporting fails because scripting does not meet the communication need. Evaluating the caption model with neuron coverage metrics for city council fails by concept: council stakeholders need progress narrative, not LLM white-box scores. Withholding metrics until after the livestream so the dashboard stays empty fails public stewardship by hiding status when decisions are still possible. Exam caveat: monitoring communication prompts translate tool data into stakeholder-readable dashboards and summaries. Operational check: export caption-test tool extracts, prompt GenAI for dashboard widgets plus plain-language status, fact-check numbers with a tester, and circulate the civic brief to non-testers at least two hours before broadcast. Keep civic stakeholders informed of residual risk and re-check the decision after the next monitoring cycle so public service quality remains auditable.