
A municipal boat-mooring waitlist shop wants to pick a model using only a public code-generation leaderboard. What should the team remember about benchmarks for software testing?
Select an answer to reveal the explanation.
Short Explanation
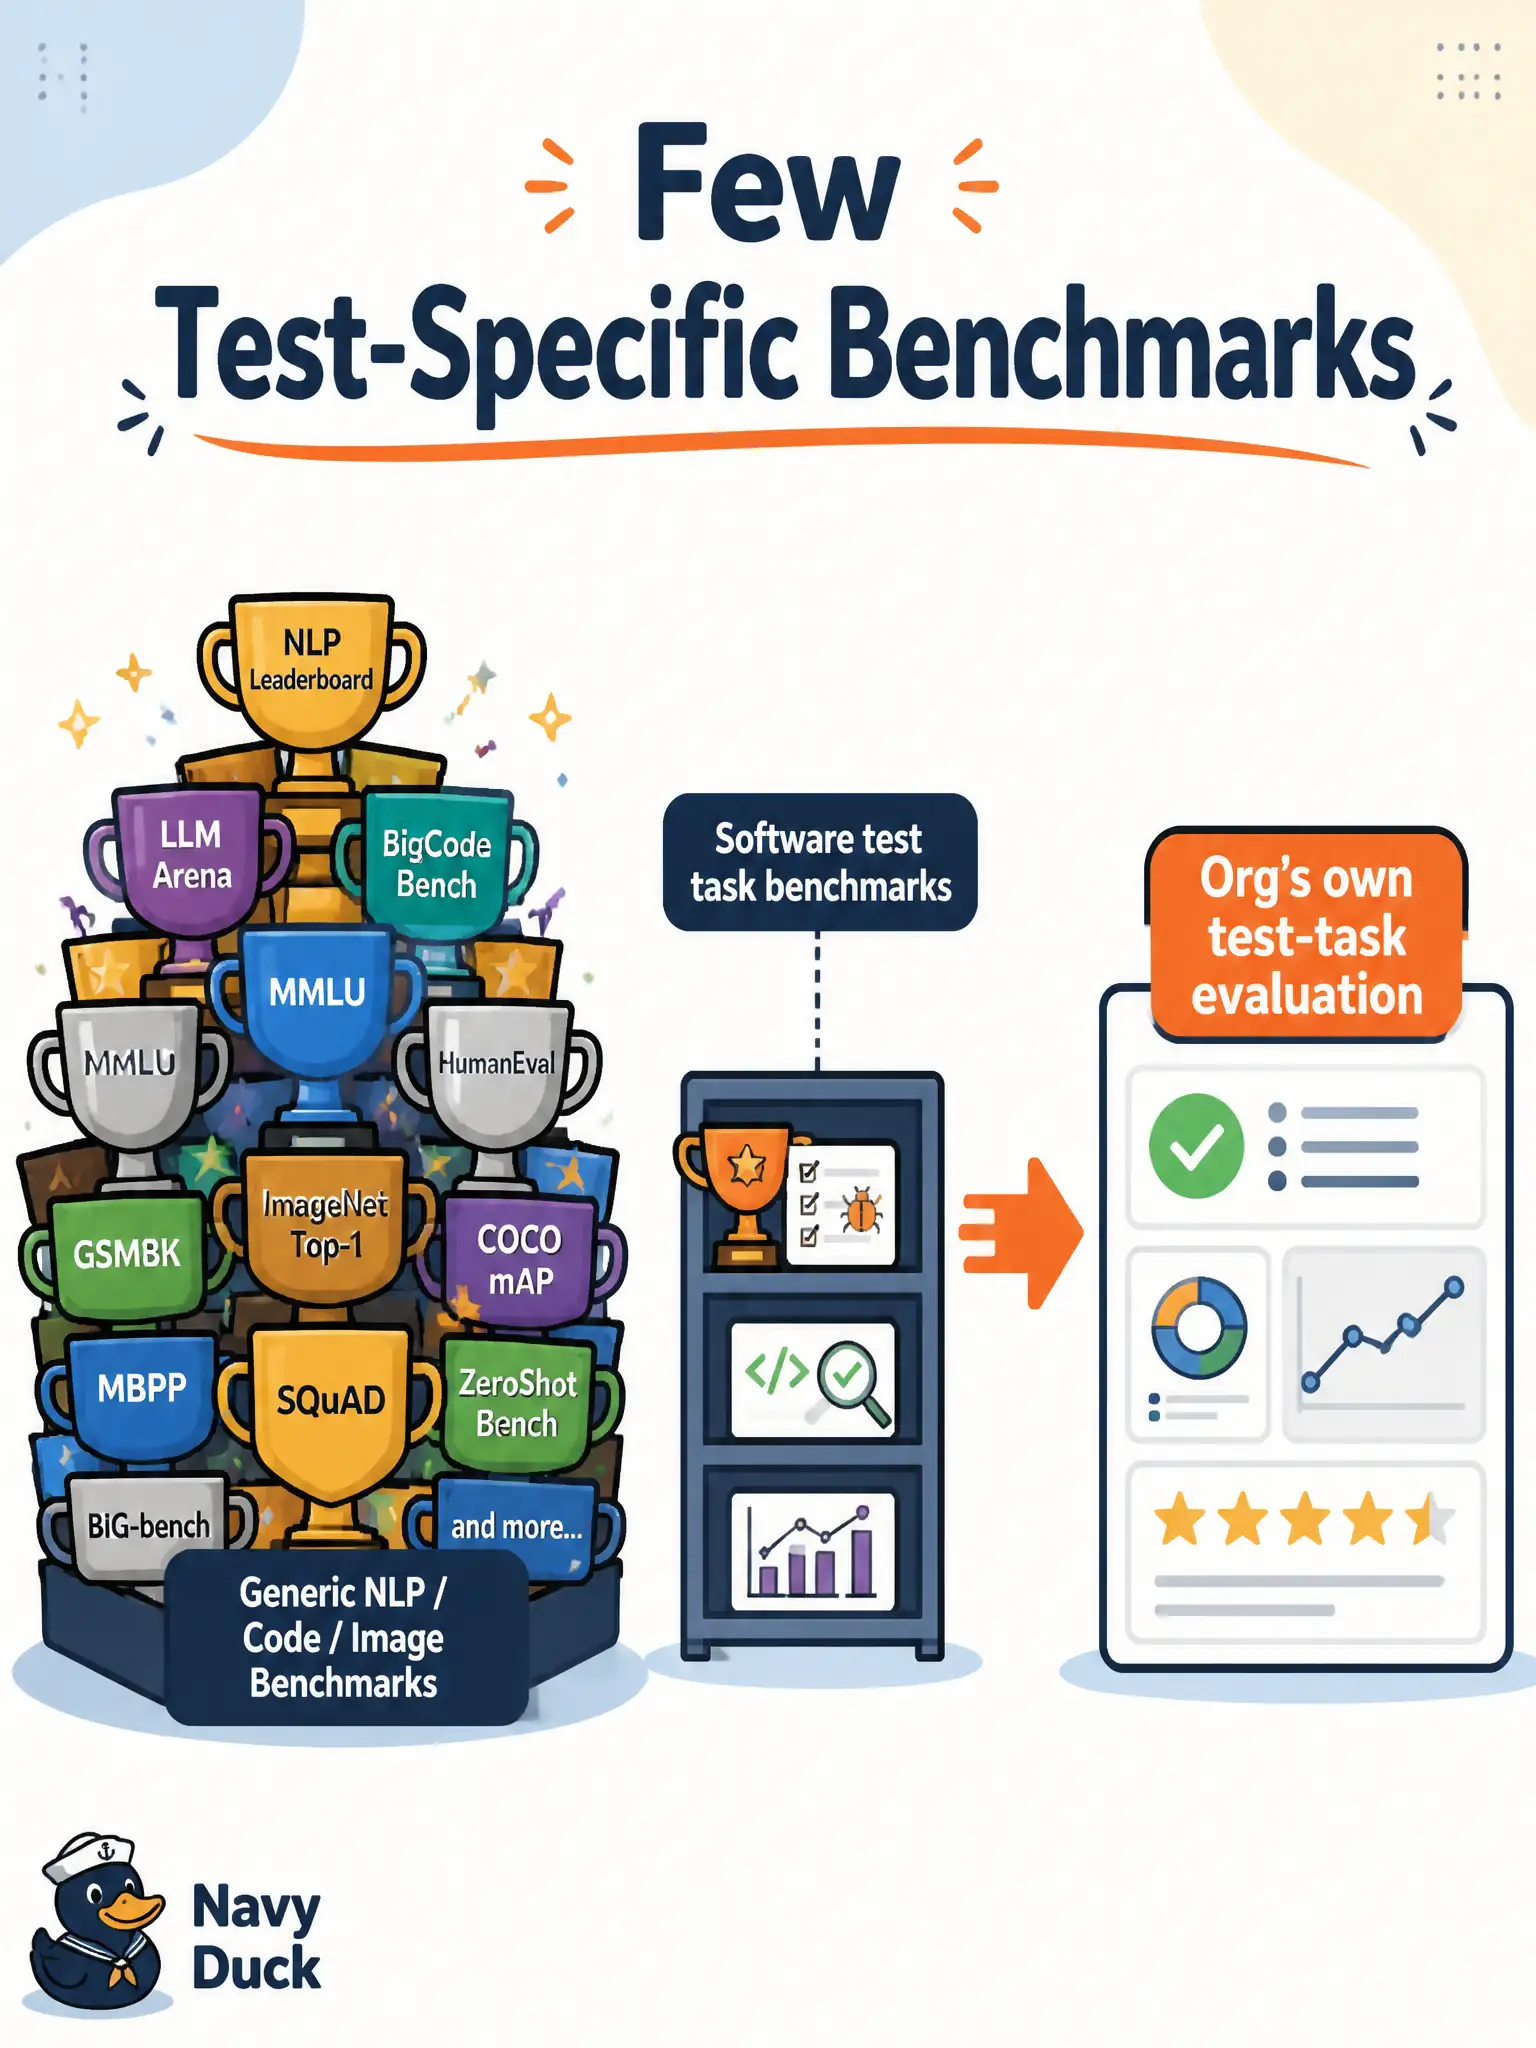
A code-generation trophy does not prove the model drafts usable weekend test cases. Few public benchmarks focus on software test tasks, so shops still need their own test-task evaluation. Leaderboard glory elsewhere is not enough.
Full Explanation
While many NLP, code, and image benchmarks exist, only a few focus on software testing tasks. Model selection for a municipal boat-mooring waitlist shop therefore still requires examining performance on the organization’s own test tasks rather than relying solely on a public code-generation leaderboard. Claiming every public NLP benchmark is already a software-test-task benchmark overstates coverage and misleads selection. Saying software-test benchmarks are illegal to use when choosing an LLM invents a ban and is false. Asserting that image-generation leaderboards fully substitute for test-case quality scoring confuses modalities and task fit. Exam caveat: scarcity of test-focused benchmarks is the point; do not treat general leaderboards as complete substitutes for org-task evaluation. Operational check: shortlist with public scores if useful, then run a structured look at how candidates draft and support the shop’s own mooring-waitlist test tasks before final selection. Keep civic testware subject to the same review discipline you would apply to human-authored packs. On the written exam, prefer syllabus terminology over vendor marketing language or lab choreography. Treat fluent output as a draft until organizational quality gates and data-handling rules are satisfied.