
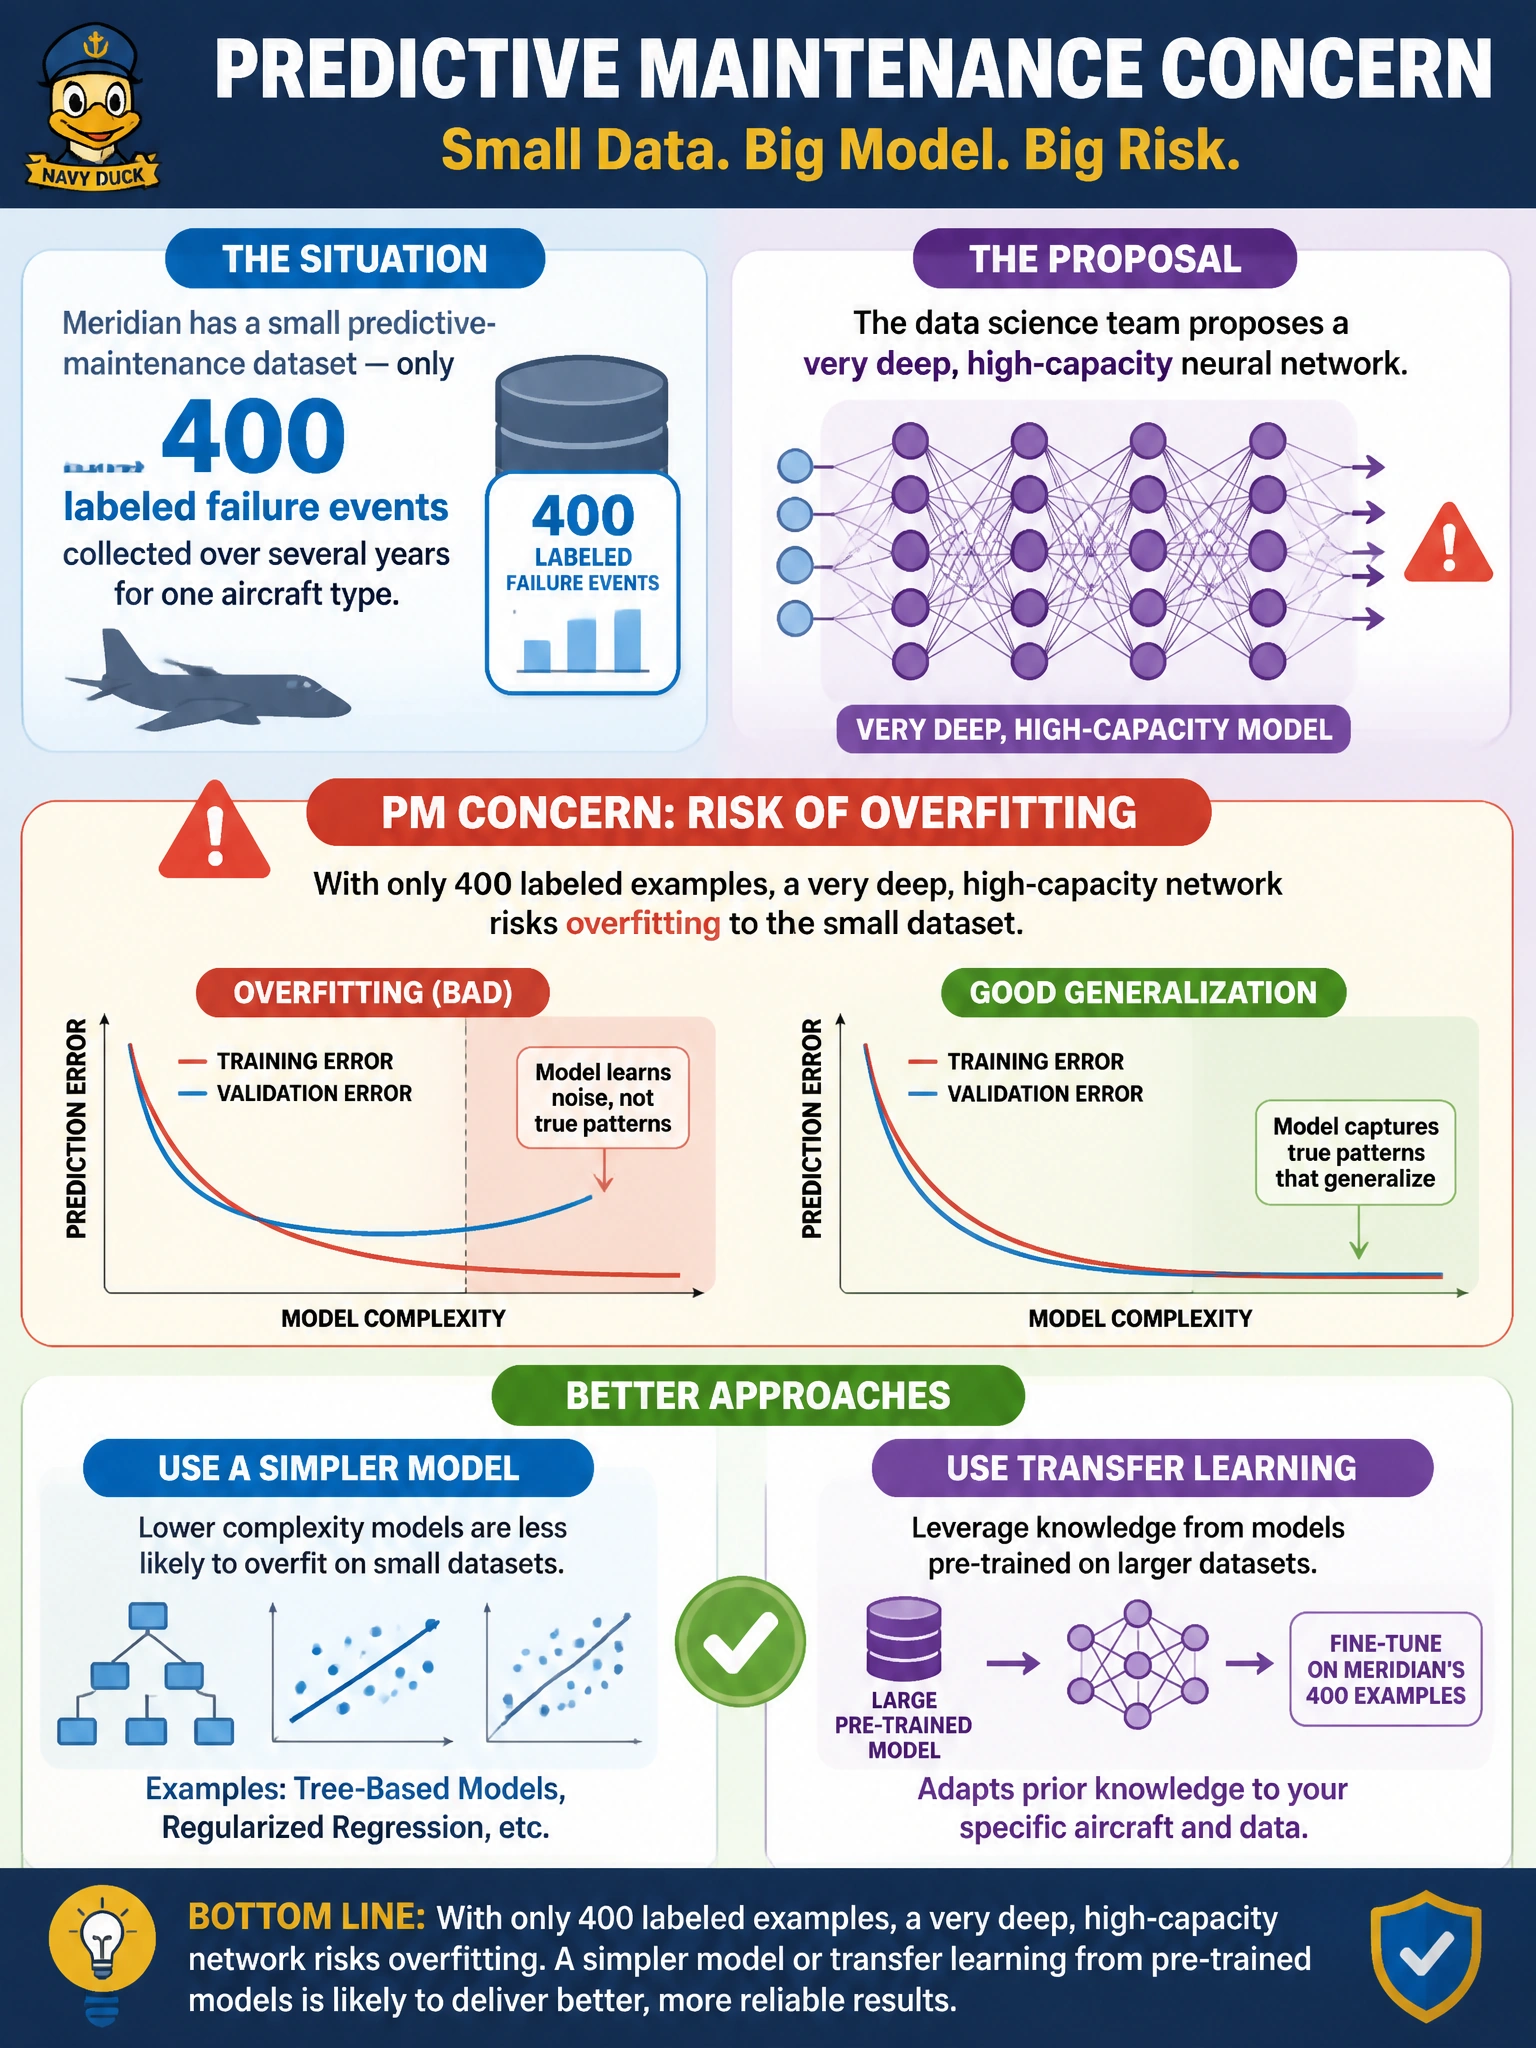
Meridian has a small predictive-maintenance dataset — only 400 labeled failure events collected over several years for one aircraft type. The data science team proposes a very deep, high-capacity neural network. What should the PM raise as a concern?
Select an answer to reveal the explanation.
Short Explanation
Match the tool to the shape of the data — pictures want a vision-style net, a rolling time series wants something built for sequence, not the other way around.
Full Explanation
A PM should flag the mismatch between a small labeled dataset (400 examples) and a high-capacity deep architecture, since more parameters generally require more data to avoid overfitting — memorizing the specific training examples rather than learning a generalizable failure pattern; a simpler model, stronger regularization, or leveraging pre-trained/transfer-learning approaches is a more appropriate recommendation to raise in review. Claiming deep learning always performs better regardless of data size is wrong and is exactly the kind of vendor-hype assumption CPMAI methodology warns PMs to challenge — model choice must be sized to the available data, not chosen for its own sake. Claiming 400 examples is more than enough for any network is also wrong and overconfident — for a high-capacity deep model, 400 examples is a genuinely small dataset. Dismissing the concern as irrelevant to network depth and redirecting to camera hardware is a non-sequitur; the scenario is about a maintenance failure-prediction model and its labeled dataset size, not a vision system.