
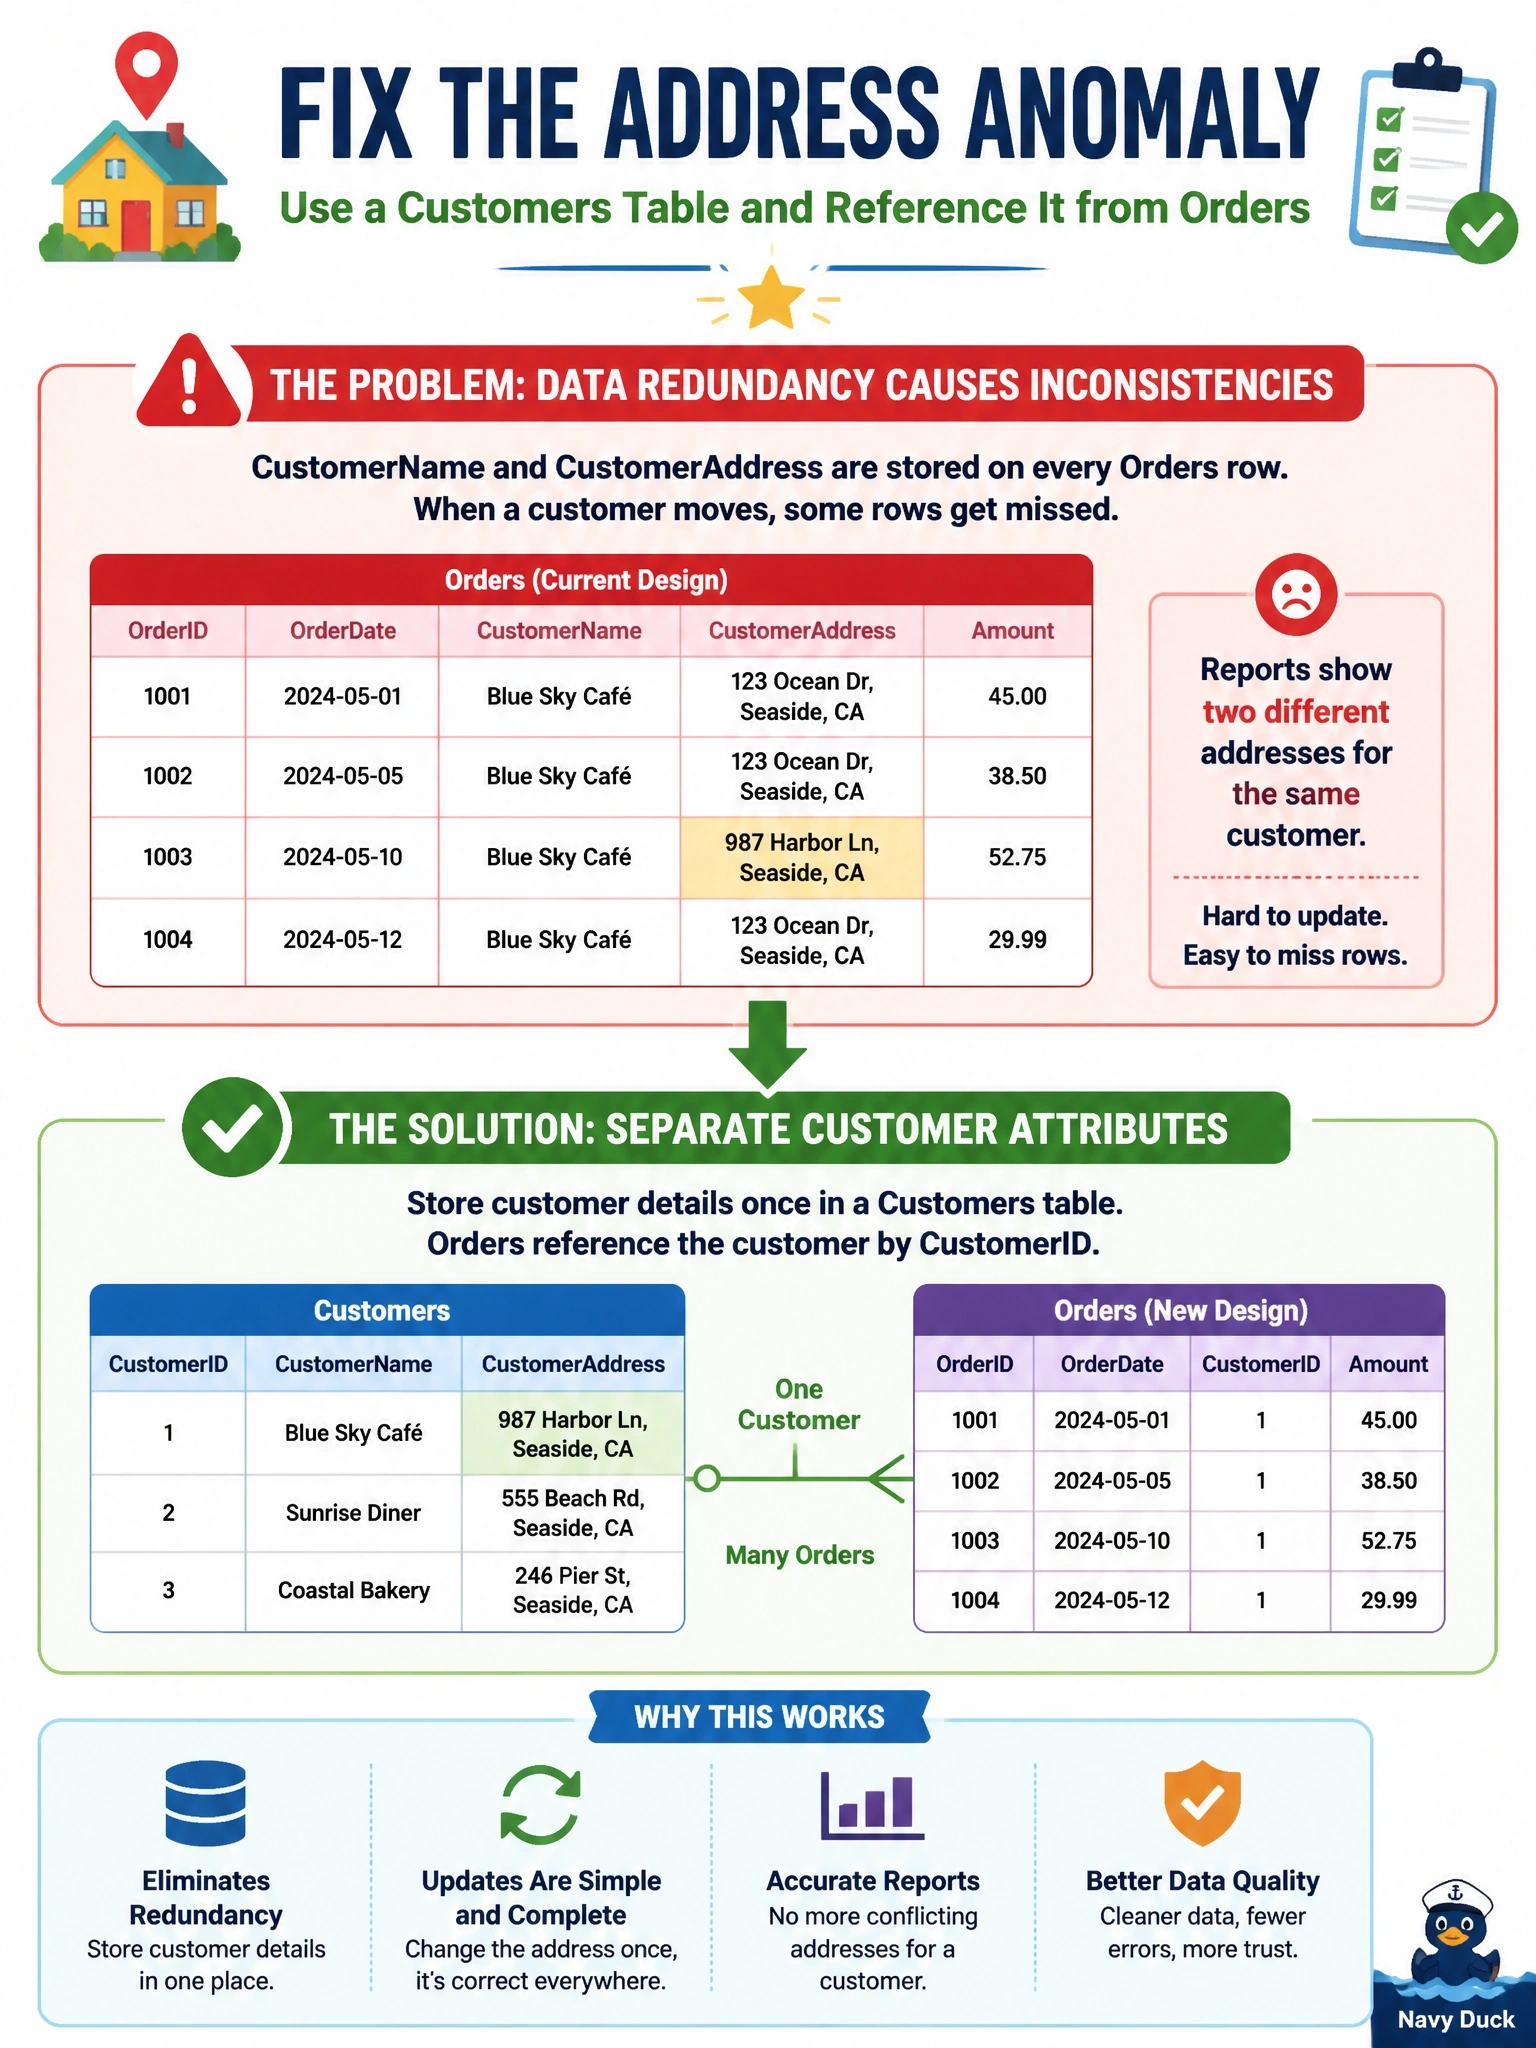
An Orders table stores CustomerName and CustomerAddress on every order row. When a customer moves, the update often misses some rows and reports show two different addresses for one customer. Which design change removes the cause of this anomaly?
Select an answer to reveal the explanation.
Short Explanation
If you write a friend's address on every letter you've ever filed, you'll miss one when they move. Store the address once, in a Customers table, and point each order at it. A trigger that patches all the copies is a band-aid; the redundancy is still there waiting to bite you.
Full Explanation
The table suffers an update anomaly: the same fact, a customer's address, is stored redundantly on many rows, so a change must be repeated everywhere and any missed row leaves the data inconsistent. Normalization removes the redundancy by placing customer attributes in their own Customers table, with one row per customer, and having Orders reference that row through a CustomerID foreign key. The address then exists in exactly one place, so a single update is automatically reflected in every order through a join. A trigger that rewrites every copy treats the symptom; the duplicated data remains, the trigger adds write overhead, and any bulk path that bypasses or disables it reintroduces the inconsistency. An index on the address column may help locate rows, but it does not reduce the number of copies that must be kept in agreement. Merging everything into one wide table is denormalization, which increases redundancy and multiplies the same anomaly. Exam caveat: if orders must preserve the shipping address as it was at order time, that snapshot is a distinct fact and may legitimately be stored on the order. Operational check: after migration, query for any customer with more than one distinct address value and confirm none remain.