
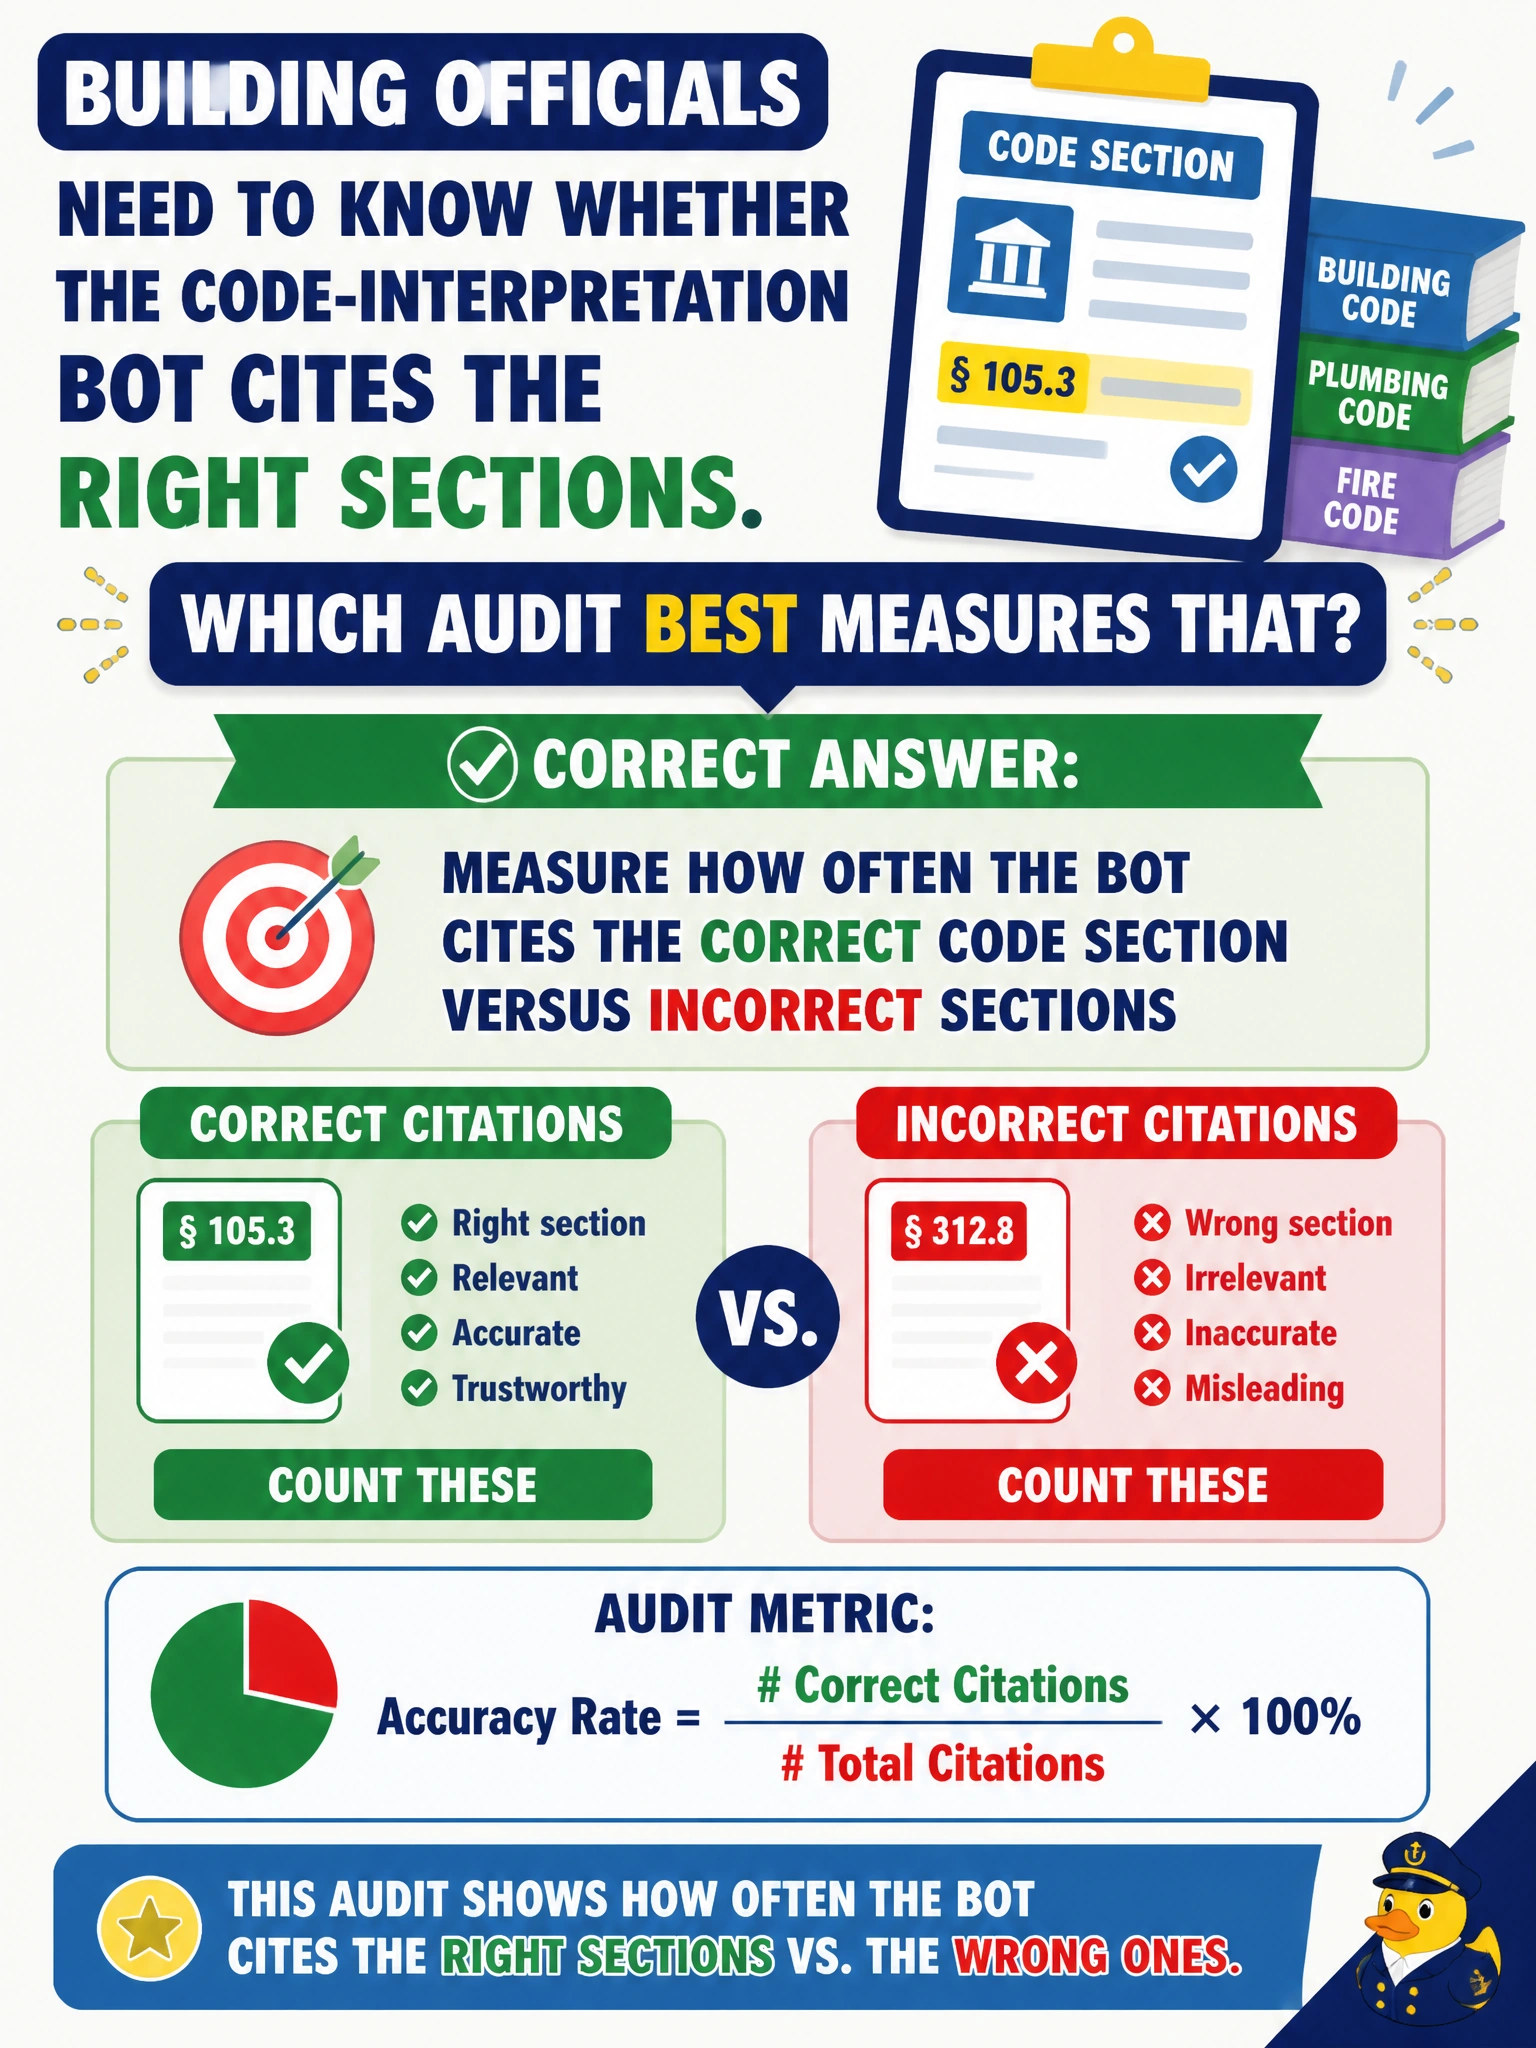
Building officials need to know whether the code-interpretation bot cites the right sections. Which audit best measures that?
Select an answer to reveal the explanation.
Short Explanation
Right section beats merely relevant section. Measuring how often the code bot cites the correct clause versus the wrong one is real accuracy auditing. You'll find it's not accurate just because the cited passage entails its summary, the retrieved sections look relevant, or it matches the vendor's code benchmark.
Full Explanation
Building officials need accuracy auditing that measures how often the code-interpretation bot cites the correct building-code section versus an incorrect one. Accuracy here is domain-grounded correctness against an authoritative code corpus, not generic fluency. Quantifying correct versus incorrect citations shows whether the assistant helps inspectors and applicants or systematically mispoints them to the wrong requirements—high-impact in permitting and compliance. Municipal sampling with labeled gold questions beats agreeing with the vendor benchmark for code queries because the city owns the acceptance criteria for its code edition and local amendments. Measuring how often the cited passage entails the bot's code summary explanation fails as an accuracy metric; a faithful summary of the wrong section says nothing about whether the cited section is correct. Measuring how often the retrieved sections are topically relevant to the query fails the construct—relevant sections that are not the correct requirement are still wrong. Measuring how often the bot agrees with the vendor benchmark for code queries fails independence and local validation; a vendor code benchmark does not replace city acceptance testing against the adopted code. Exam caveat: Accuracy auditing requires a ground-truth set tied to the jurisdiction’s adopted code version. Do not confuse a cited passage entailing the summary with citation correctness—a faithfully summarized wrong section number is still an accuracy fail. Retrieving topically relevant sections remains useful for search quality but answers a different question than accuracy. Operational check: Maintain a gold set of building-code questions with expected section citations; score the bot on correct vs incorrect citations after each model or corpus change; require minimum accuracy gates before production; and reject agreeing with the vendor benchmark for code queries as a substitute for municipal sampling.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.