
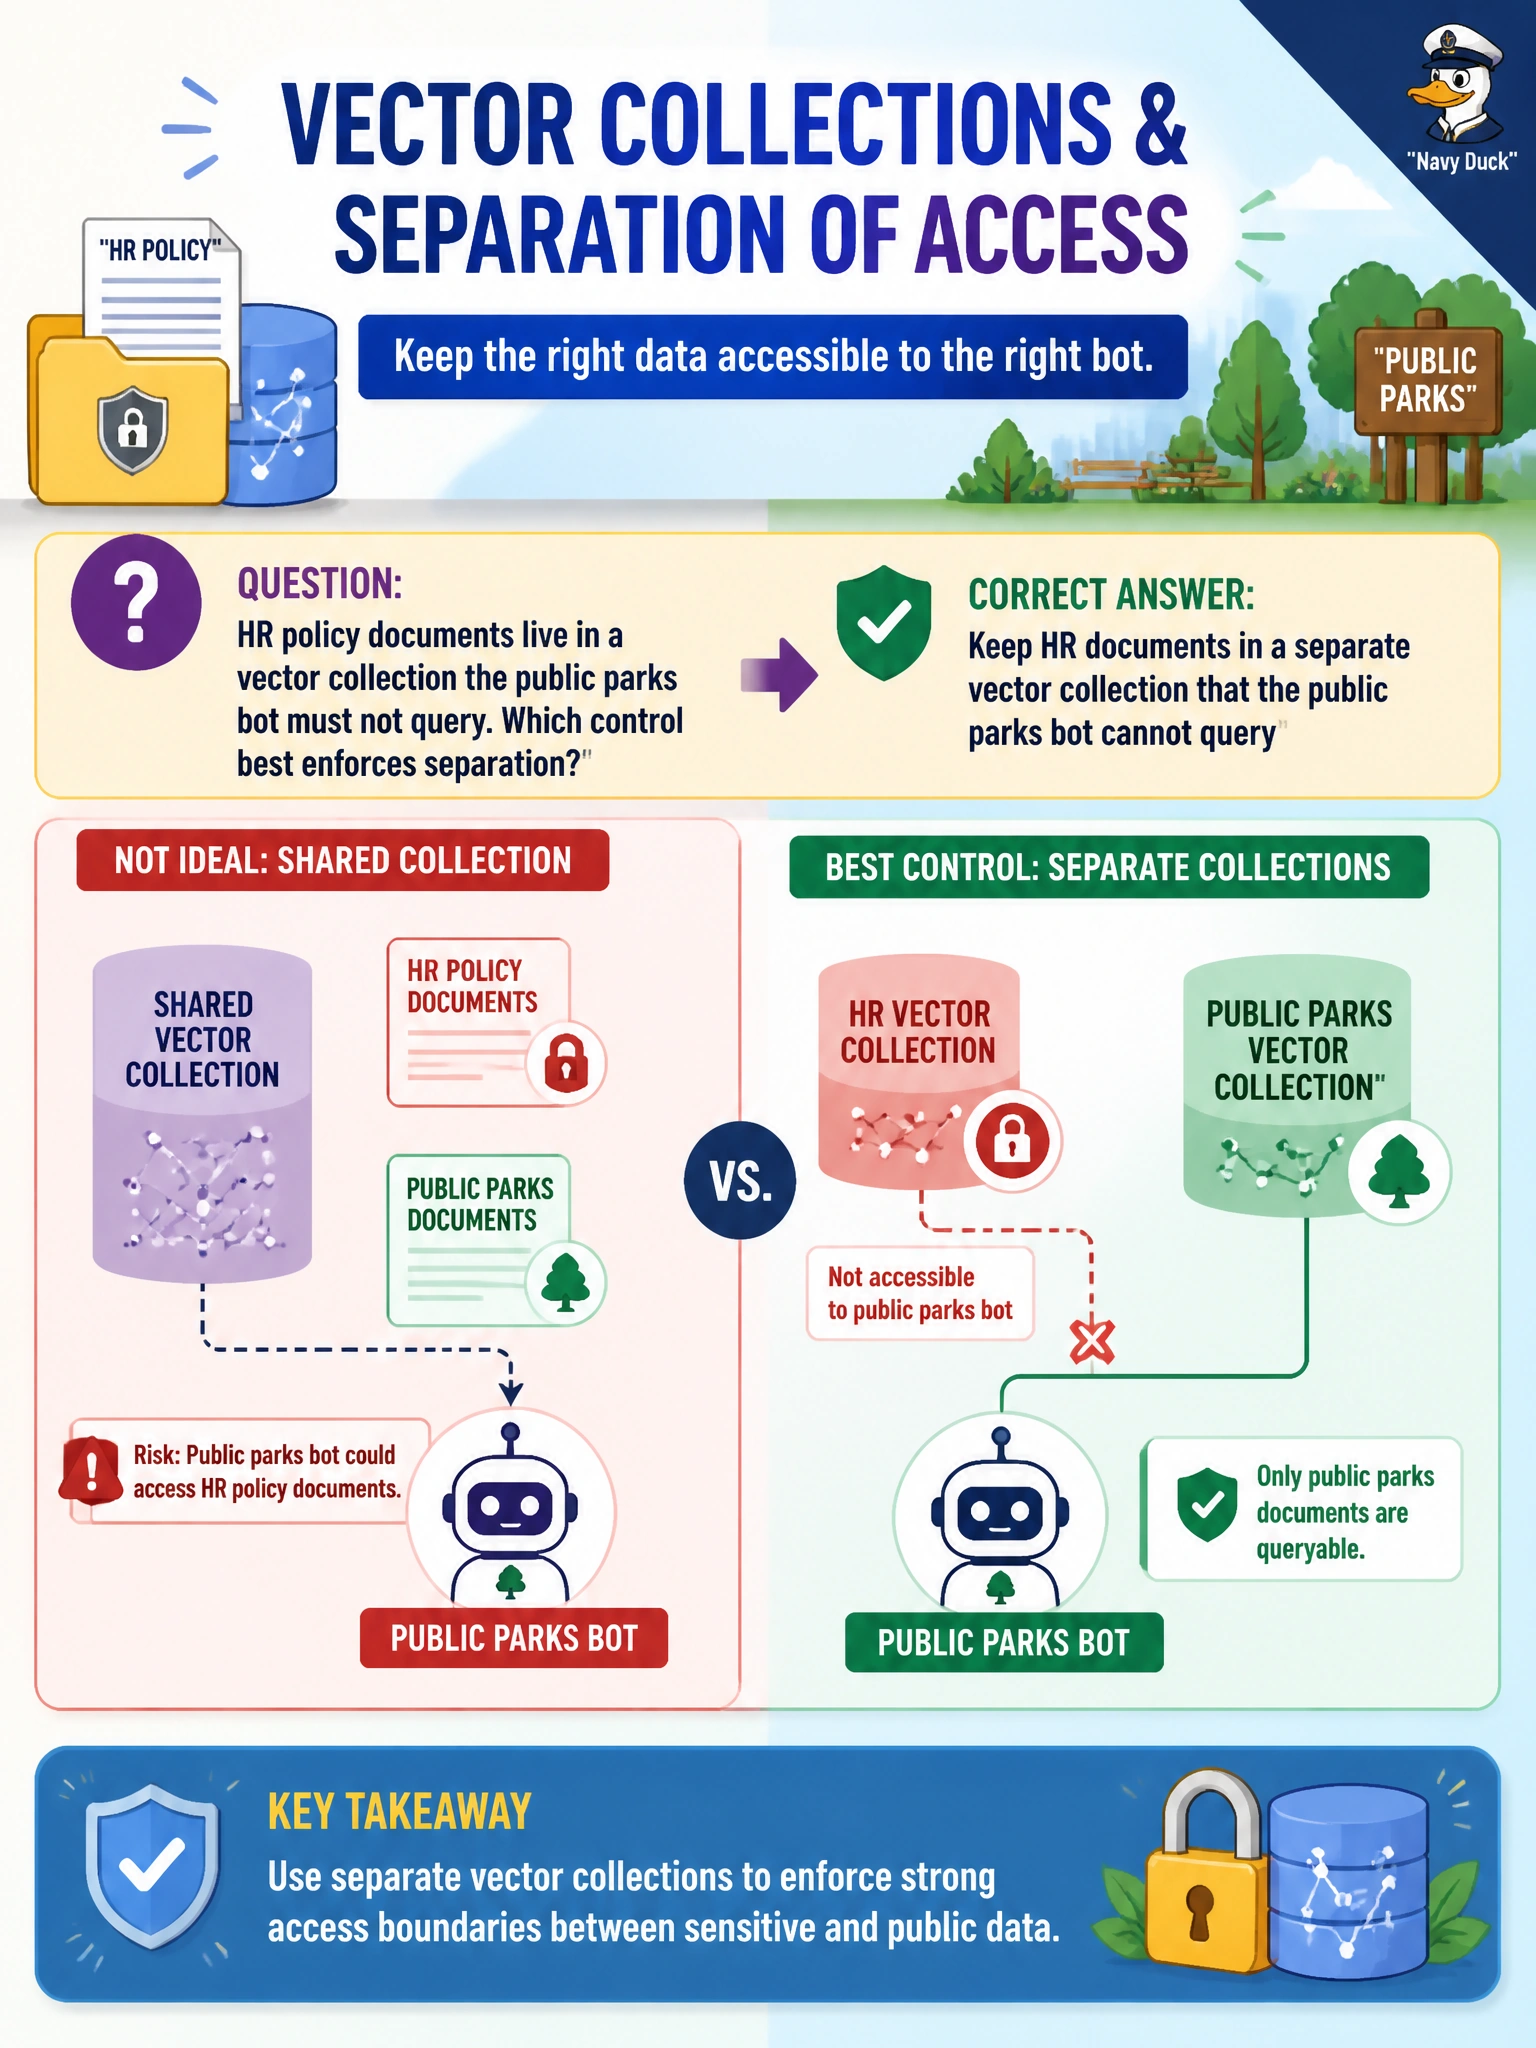
HR policy documents live in a vector collection the public parks bot must not query. Which control best enforces separation?
Select an answer to reveal the explanation.
Short Explanation
HR policies aren't trail-map content. Put them in a separate vector collection and block the public parks bot from querying it. If you keep them in a separate collection but let the parks bot rely on metadata tags to filter them out, you'll still risk HR text leaking when the tags fail.
Full Explanation
Keeping HR documents in a separate vector collection that the public parks bot cannot query is the control that enforces RAG corpus separation. Partitioned collections plus query authorization ensure a public-facing parks assistant cannot retrieve internal HR policy embeddings. That separation protects employee-related municipal content from leaking through an unrelated resident chatbot while still allowing the parks bot to use its own appropriate corpus. Keeping HR documents in a separate vector collection with parks bot filtering by metadata tags fails because the parks bot can still query the HR collection and metadata-tag filtering alone is not a reliable access boundary. Keeping HR documents in a separate vector collection replicated to the parks bot cache for latency fails because copying HR embeddings into the parks bot's cache puts them within the parks bot's retrieval reach and defeats separation for performance. Keeping HR documents in a separate vector collection blocked by parks bot system prompt policy fails because prompts are soft guidance, not access enforcement, and cannot reliably stop the bot from retrieving HR embeddings if its identity can still query the collection. Exam caveat: RAG security often hinges on corpus partitioning plus query-time authorization. Separate collections or system-prompt instructions that are not actually enforced against the consuming identity are frequent wrong answers when the stem requires separation of sensitive collections from public bots. Operational check: Place HR policies in a restricted vector collection, deny the parks bot's identity from querying it, attempt an HR-policy retrieval via the parks bot (denied), confirm parks documents still retrieve, and retain classification metadata on embeddings.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.