
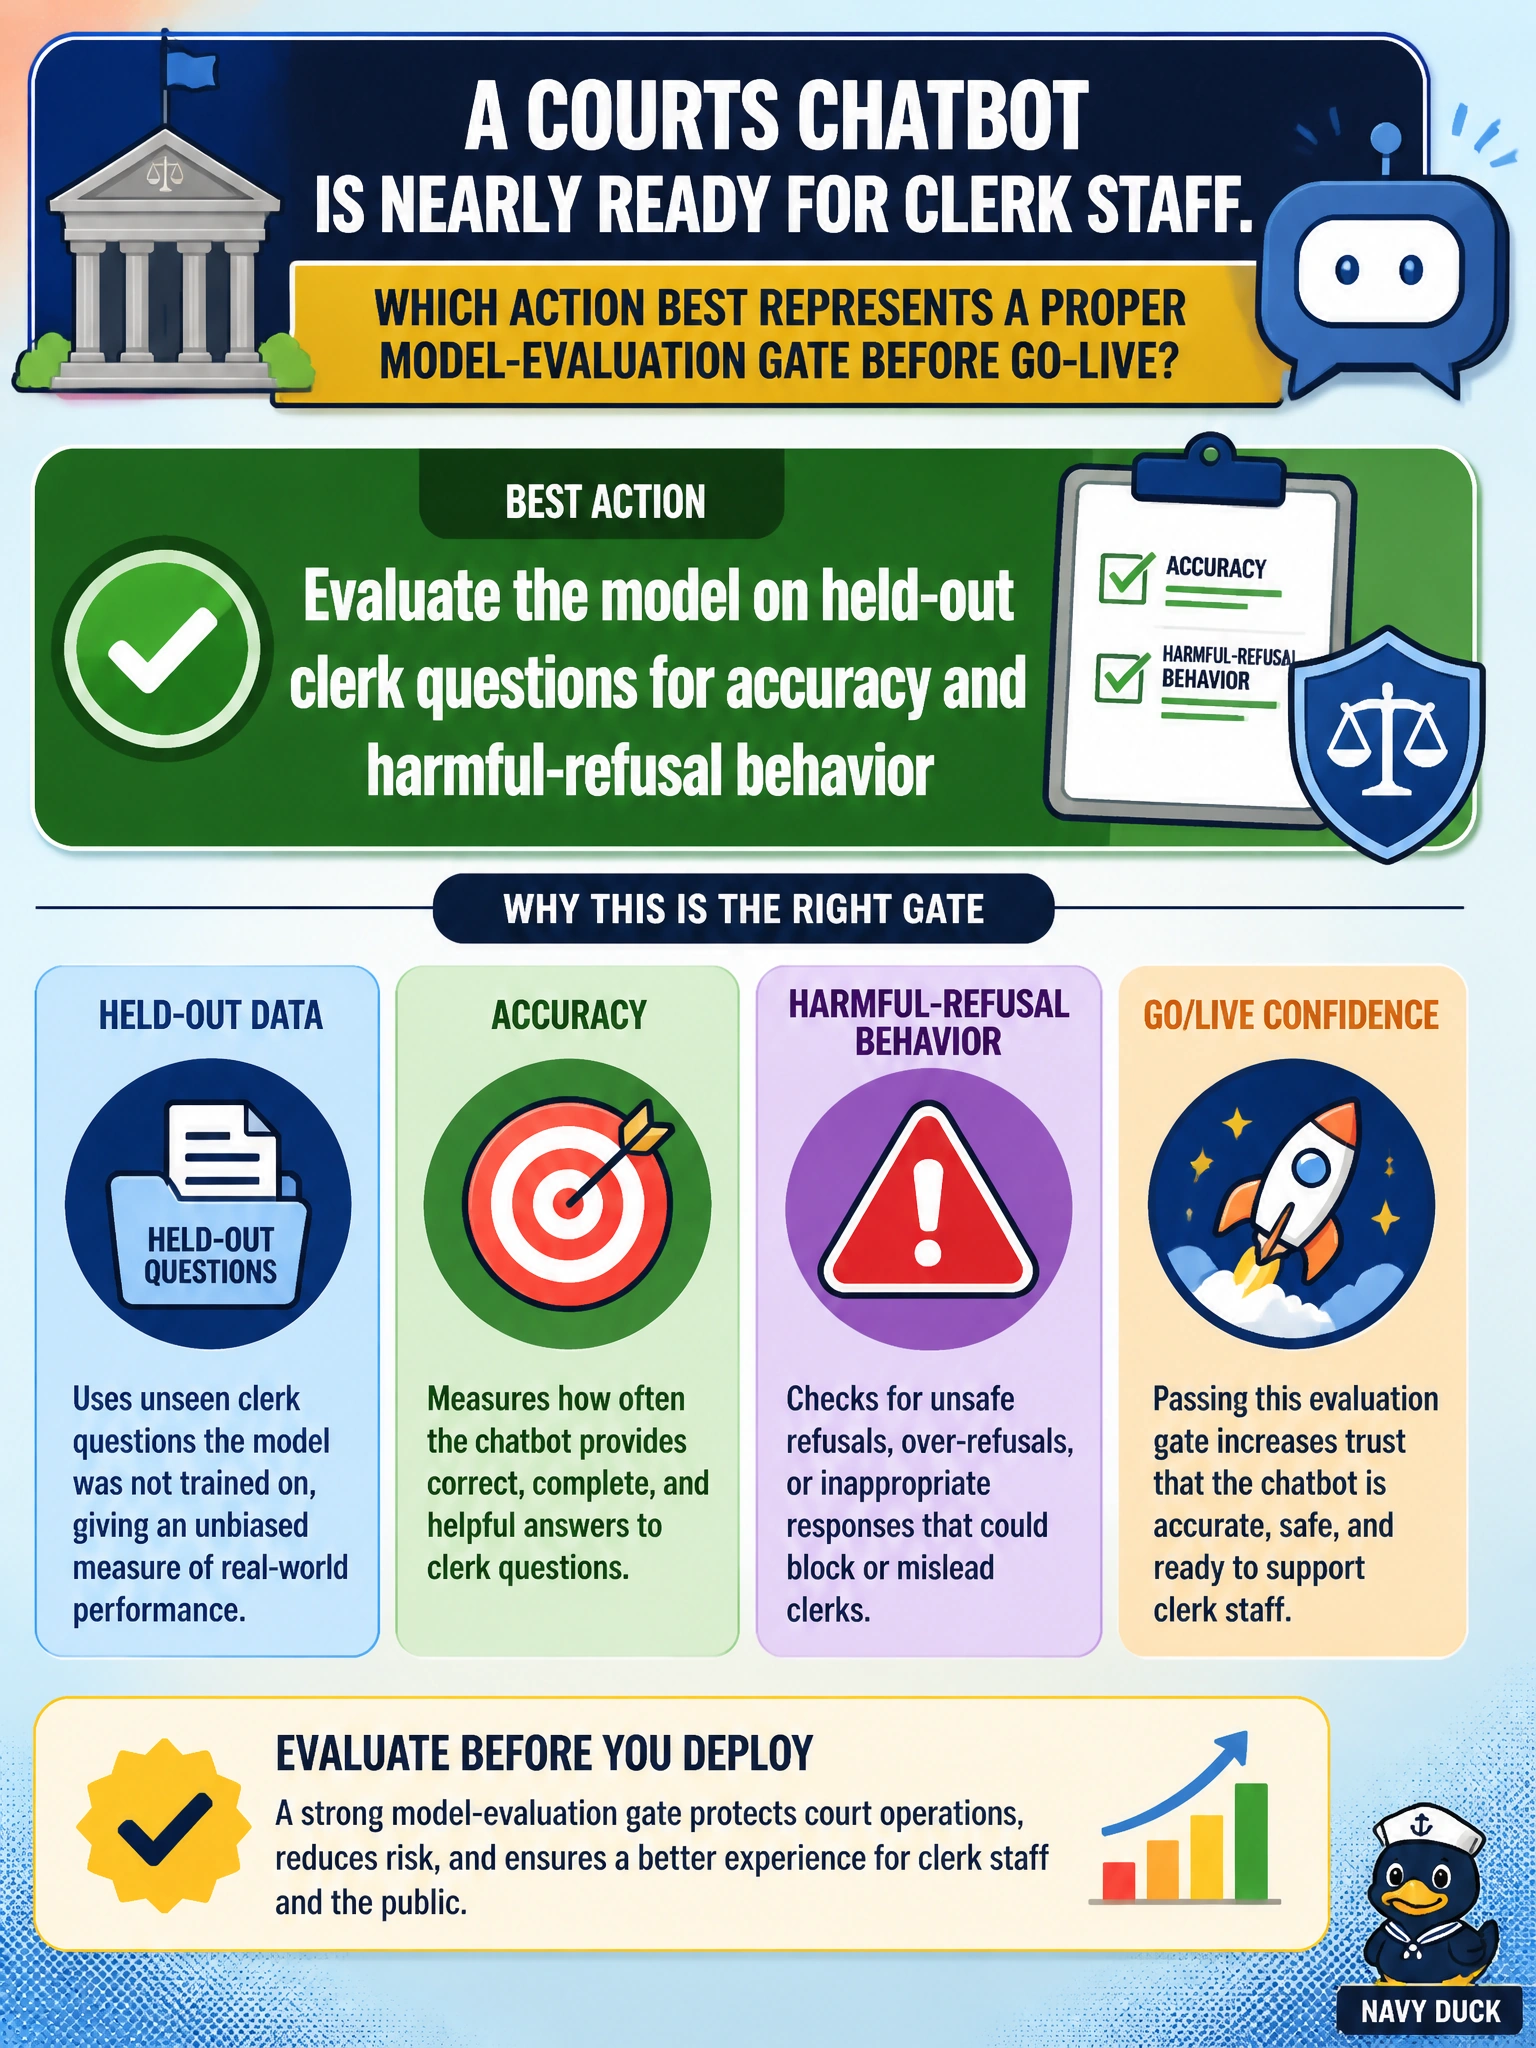
A courts chatbot is nearly ready for clerk staff. Which action best represents a proper model-evaluation gate before go-live?
Select an answer to reveal the explanation.
Short Explanation
Scoring training questions the model's already seen isn't a green light — you'll just measure memorization, not how it'll handle new clerk work. Held-out clerk questions for accuracy and harmful refusals catch bad habits before docket day. Public benchmarks miss your local docket rules and synthetic questions won't capture real clerk phrasing, so you've got to prove it beforehand.
Full Explanation
Model evaluation is a required go-live gate for municipal assistants that clerks will rely on. A courts chatbot must be scored on held-out clerk questions that measure factual accuracy against authoritative procedures and harmful-refusal behavior—whether the assistant declines unsafe disclosures about sealed matters, private party data, or improper advice. City-controlled test cases establish an independent acceptance bar that vendor marketing cannot substitute. Only after accuracy and refusal thresholds pass should the system move to limited production with clerks.
Evaluating the model on training clerk questions for accuracy and harmful-refusal behavior measures memorization of data the model has already seen rather than genuine generalization to new clerk requests. Evaluating the model on public legal benchmarks for accuracy and harmful-refusal behavior tests generic legal knowledge rather than local clerk procedures, docket language, and sealed-matter confidentiality rules. Evaluating the model on synthetic clerk questions for accuracy and harmful-refusal behavior relies on artificial prompts that may miss real clerk phrasing, local procedures, and sealed-matter risks rather than proving performance on representative held-out clerk work.
Exam caveat: scoring on training clerk questions for accuracy and harmful-refusal behavior is not a valid gate because memorization inflates scores; accuracy plus harmful-refusal testing on held-out clerk questions is the gate. Operational check: maintain a clerk-owned evaluation set with pass/fail thresholds for factual answers and unsafe prompts, re-run it before each release, and block go-live when either metric regresses.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.