
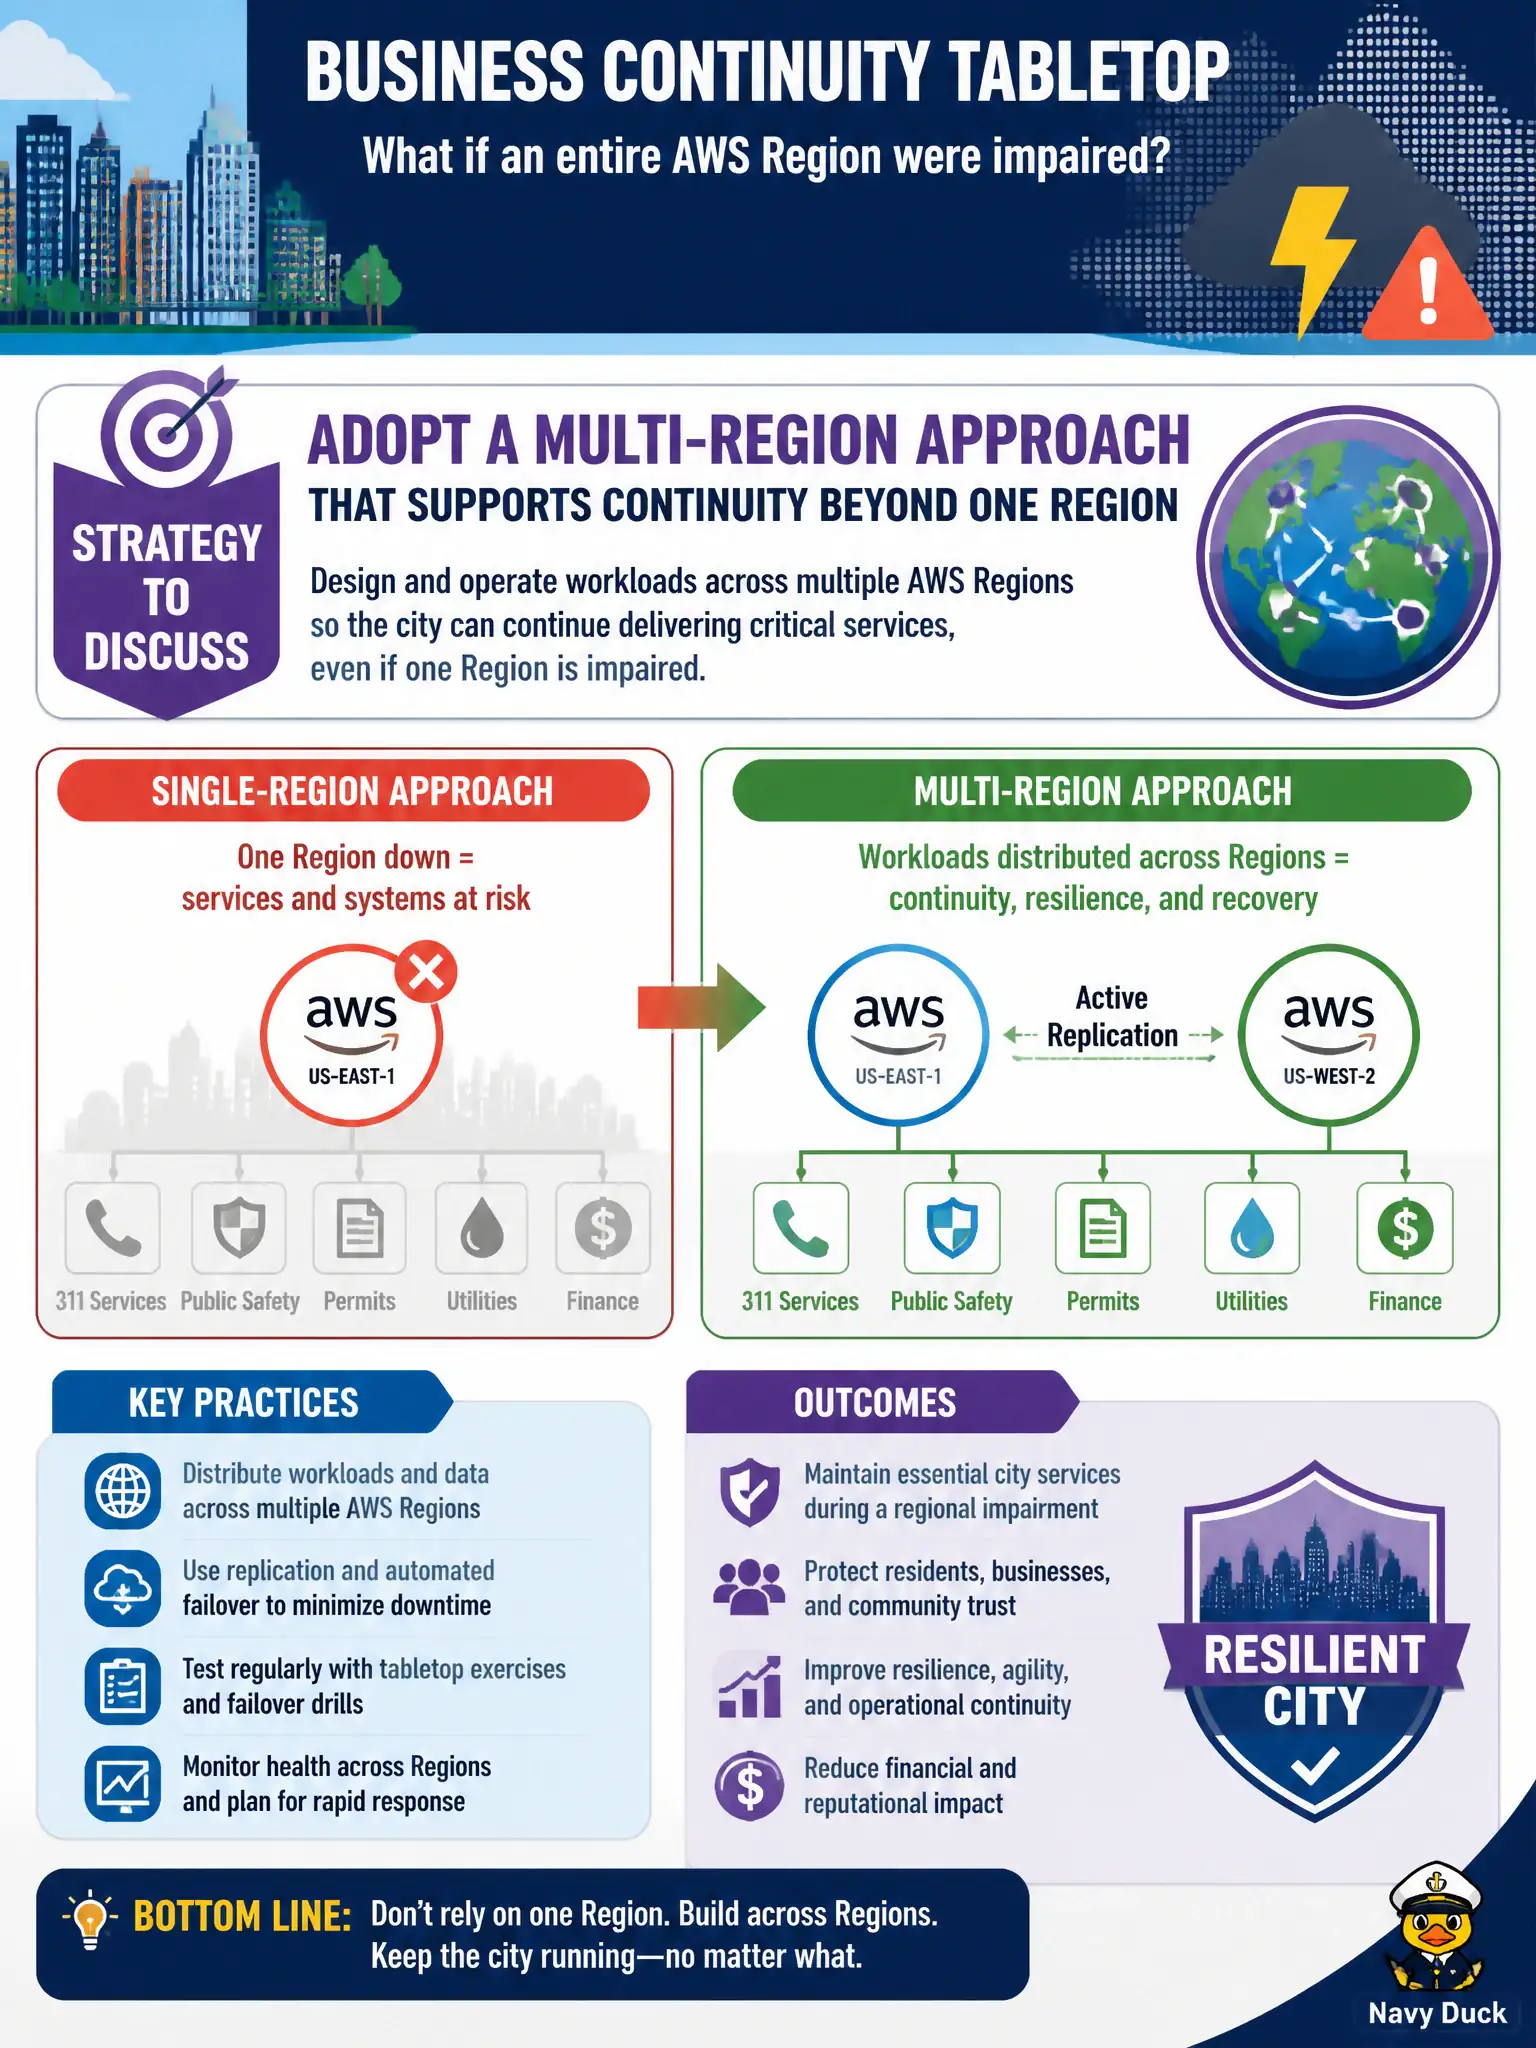
During a business continuity tabletop, leaders ask how the city would operate if an entire AWS Region were impaired. What strategy should be discussed?
Select an answer to reveal the explanation.
Short Explanation
Tabletop question: whole Region is gone—another subnet next door will not help. Leaders should talk multi-Region so continuity lives beyond one geography. Ignoring alarms or parking state on one instance's local disk makes a bad day worse.
Full Explanation
During a business continuity tabletop, when leaders ask how the city would operate if an entire AWS Region were impaired, the strategy to discuss is a multi-Region approach that supports continuity beyond one Region. Region impairment is a different failure domain than losing a subnet or an AZ. Continuity planning should cover data replication, standby capacity or rebuild procedures in a second Region, DNS failover, communications, and decision criteria for declaring a Regional event.
Depending only on a second subnet in the same impaired Region fails when the Region itself is the blast radius. Turning off monitoring so operators are not distracted removes situational awareness when it is most needed. Storing all state exclusively in instance store volumes on one host maximizes data loss risk and contradicts continuity goals.
Exam caveat: Continuity beyond one Region = multi-Region DR. Multi-AZ and multi-subnet designs remain necessary but insufficient for Region-level scenarios named in the stem.
Operational check: document RTO/RPO for critical citizen services, choose pilot-light or warm-standby patterns in a second approved Region, schedule tabletop exercises that explicitly inject Region loss, and ensure backups are not only co-located with the primary Region’s failure domain.