
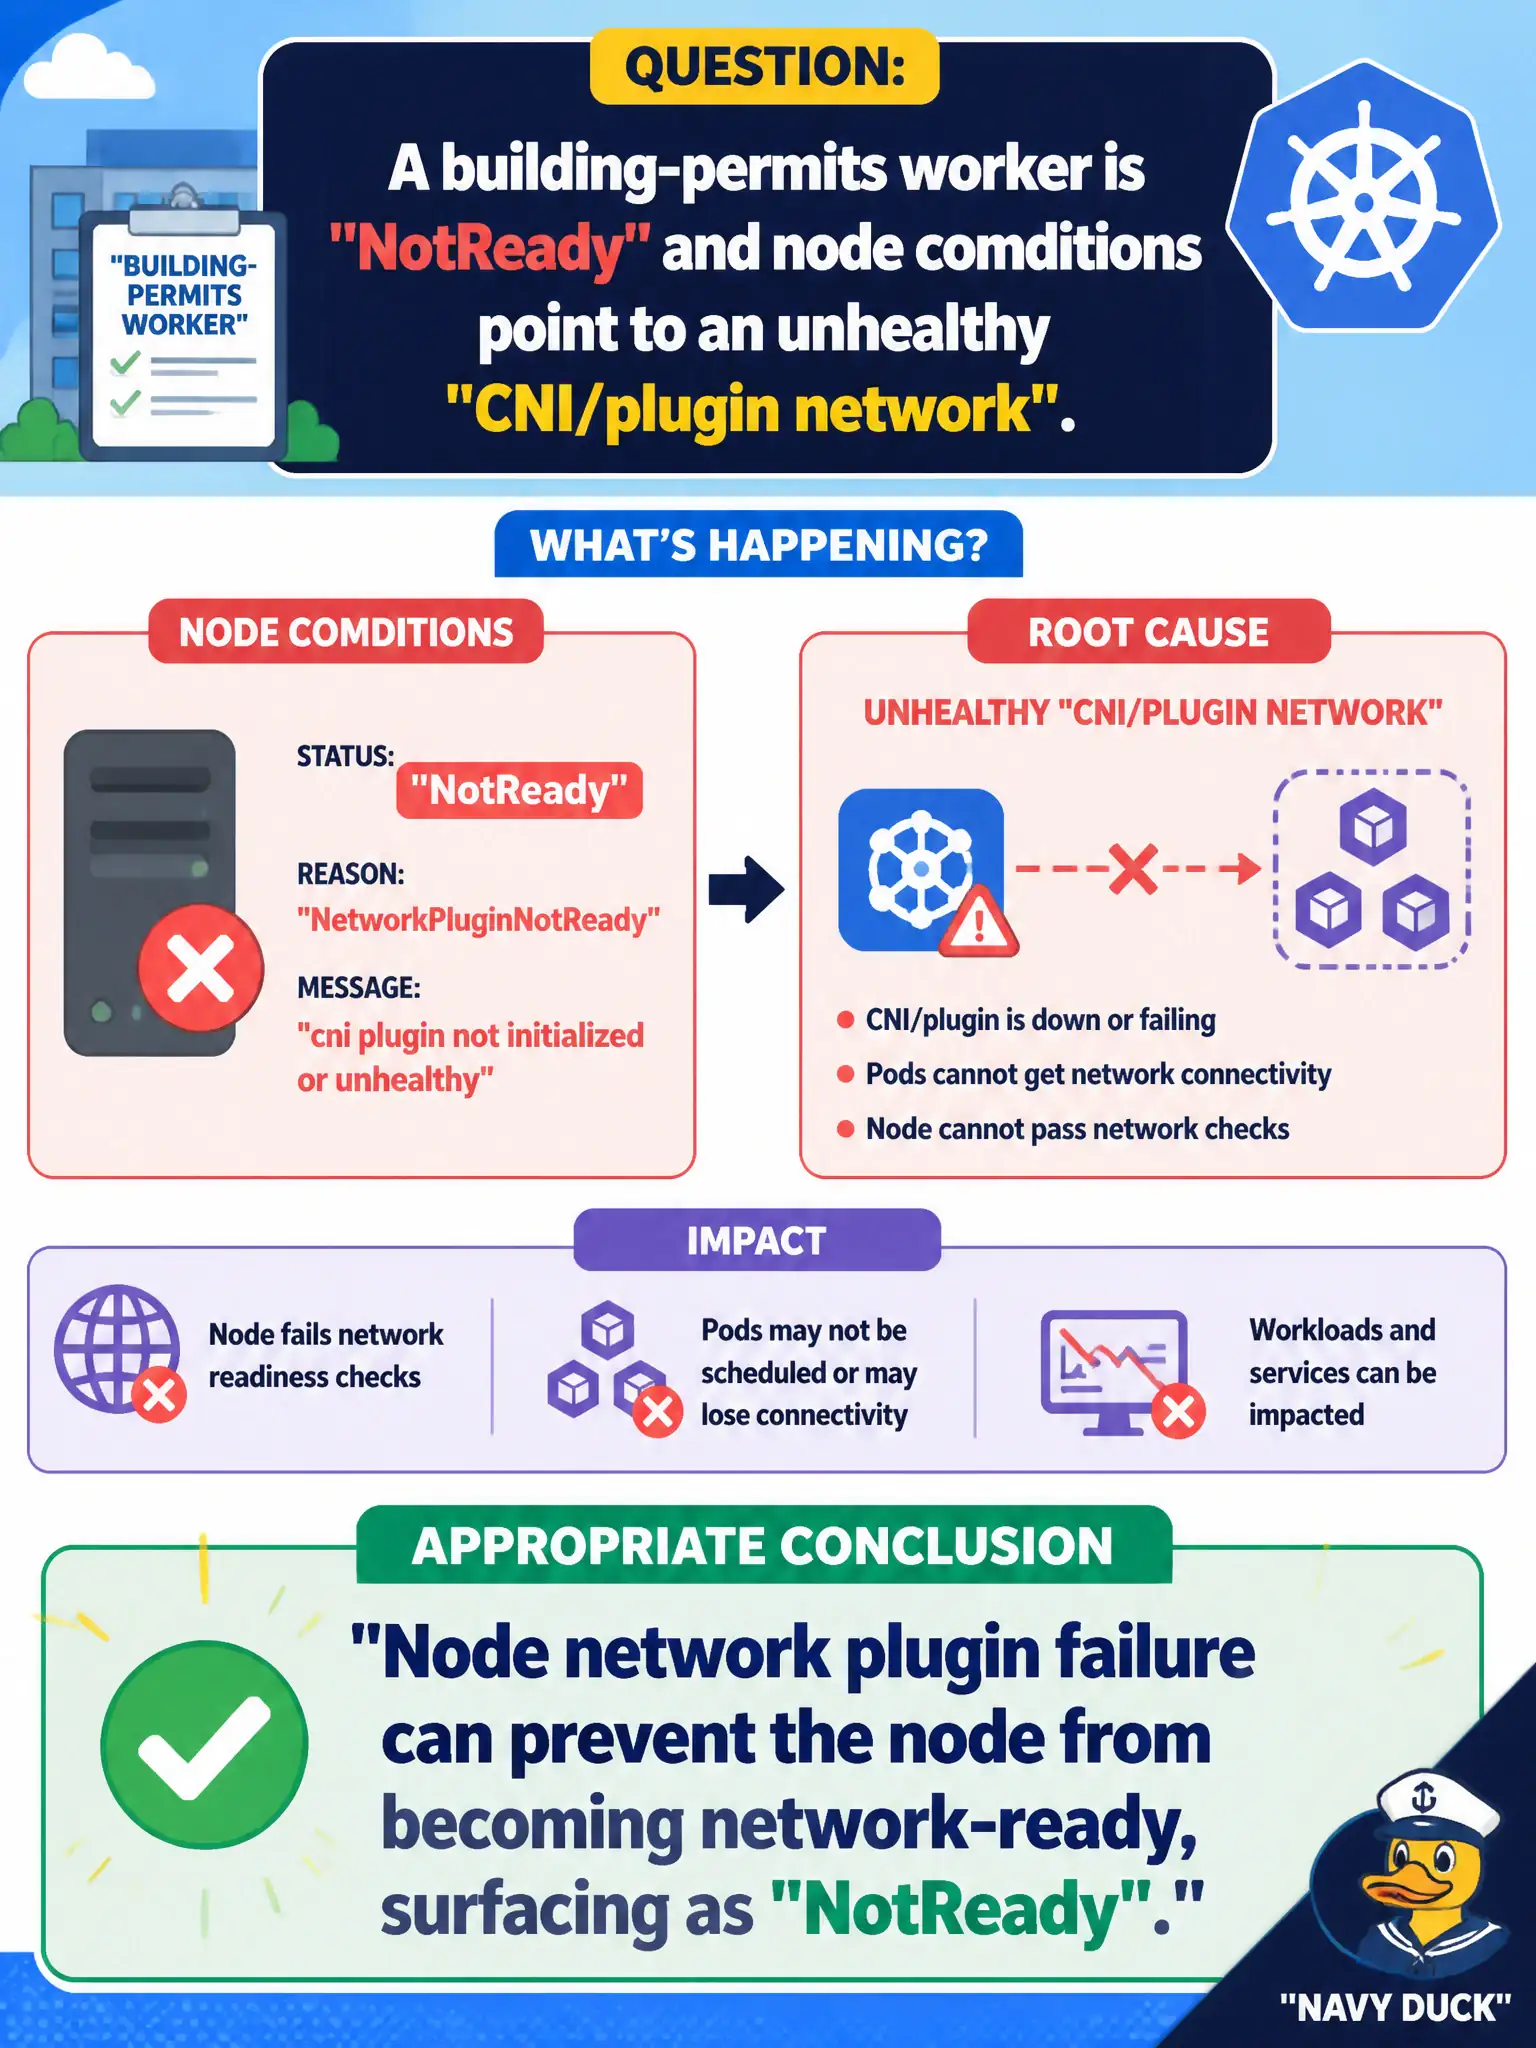
A building-permits worker is NotReady and node conditions point to an unhealthy CNI/plugin network. What is the appropriate conclusion?
Select an answer to reveal the explanation.
Short Explanation
If the CNI is sick, the node often can’t finish network setup—and NotReady is how that illness shows up on the roster.
Full Explanation
When a building-permits worker is NotReady and node conditions point to an unhealthy CNI/plugin network, the appropriate conclusion is that node network plugin failure can prevent the node from becoming network-ready, surfacing as NotReady. If the CNI is sick, the node often cannot finish network setup—and NotReady is how that illness shows on the municipal roster.
NotReady from CNI does not always mean the PVC StorageClass provisioner crashed. CNI health is not only a Windows concern—Linux workers absolutely depend on CNI. CNI failures are not limited to changing Service externalIPs without affecting readiness.
Exam caveat: inspect CNI DaemonSet Pods (Calico, Cilium, Flannel, and similar), node network conditions, and kubelet logs. Fixing storage provisioners will not heal CNI readiness problems.
Operational check: describe the NotReady node for network-related conditions, check CNI Pods on that node, restore the plugin, confirm pod CIDR/routes return, and verify the node returns Ready for permits workloads. Keep civic change tickets precise: record object names, namespaces, and before/after observations so the next on-call engineer can replay the fix without guesswork. Prefer reversible steps and verify Ready or Bound state before closing the incident.