
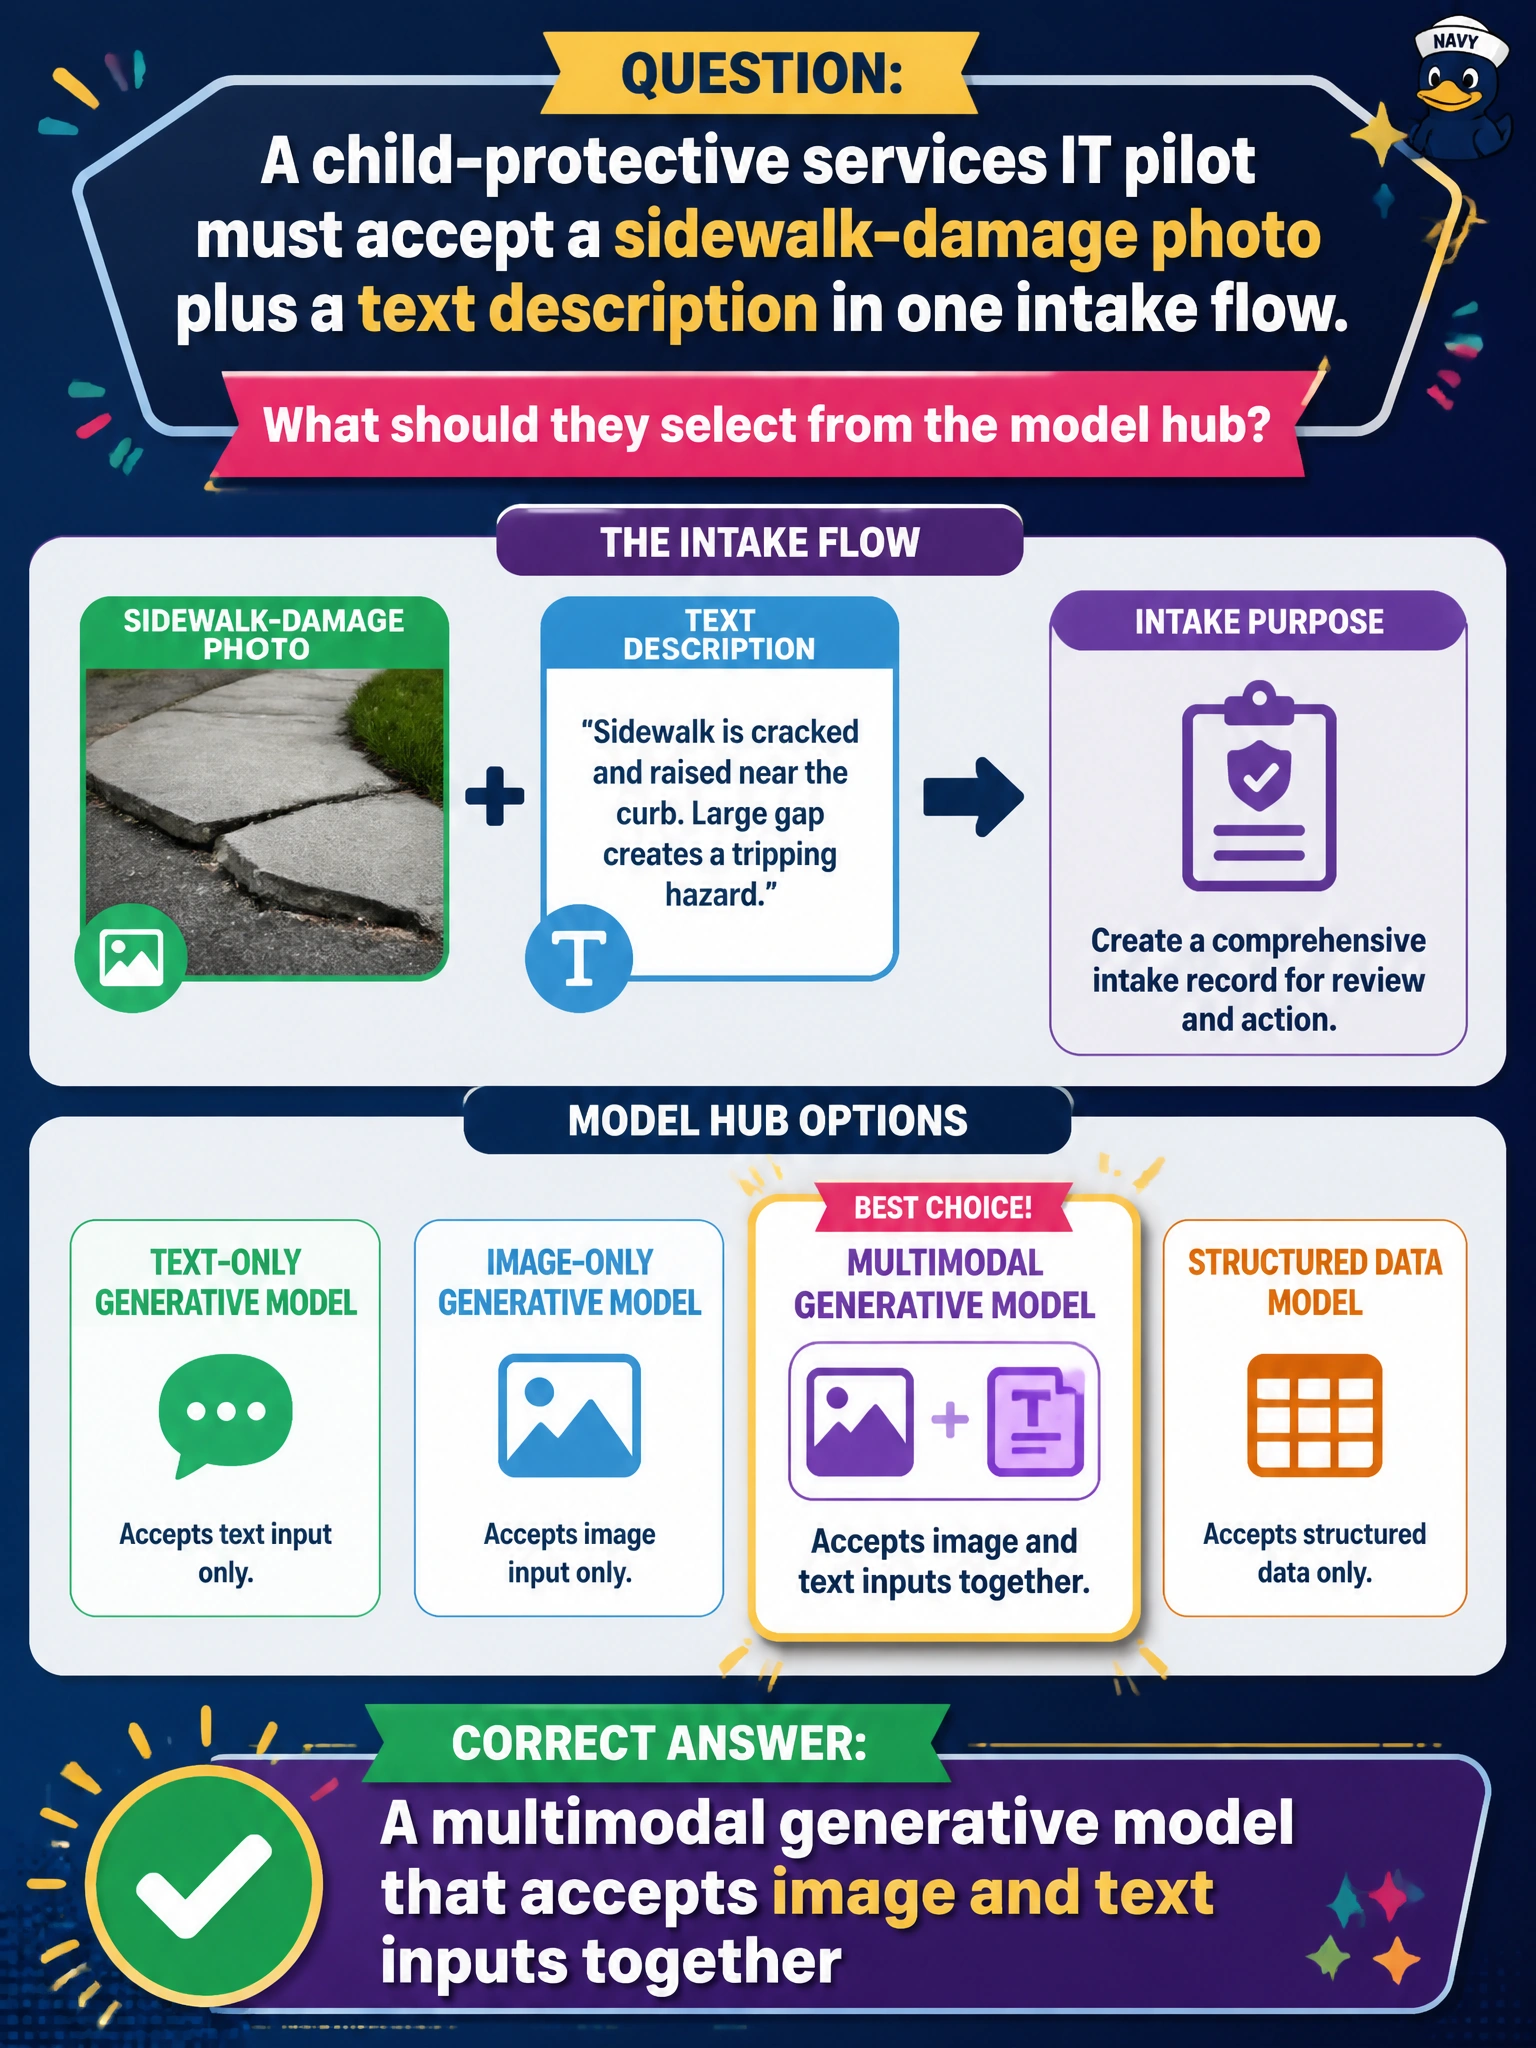
A child-protective services IT pilot must accept a sidewalk-damage photo plus a text description in one intake flow. What should they select from the model hub?
Select an answer to reveal the explanation.
Short Explanation
When the case starts with both a picture and a paragraph, you need a model that speaks both languages—multimodal. A text-only tool would leave the photo on the porch.
Full Explanation
A child-protective services intake pilot that accepts a sidewalk-damage photo plus a text description in one flow needs joint understanding of image and language. Selecting a multimodal generative model that accepts image and text inputs together matches that requirement and lets the assistant relate visual evidence to the written narrative. Modality fit is the primary hub filter for this pilot.
A text-only summarizer that rejects all image uploads cannot consume the photo half of the intake packet. An embedding model card with no generative decoder may support retrieval indexing but does not by itself produce the multimodal intake interpretation and response the workflow needs. A classical rules engine that cannot read photos or free text fails both modalities and cannot replace a multimodal generative assistant for this pilot.
Exam caveat: multimodal acceptance does not equal policy compliance—CPS deployments still need privacy controls, retention rules, and human review for high-stakes decisions. Operational check: verify the chosen hub card's documented input modalities, run sample photo-plus-text intakes, and confirm the model references both visual and textual cues before promoting the pilot.