
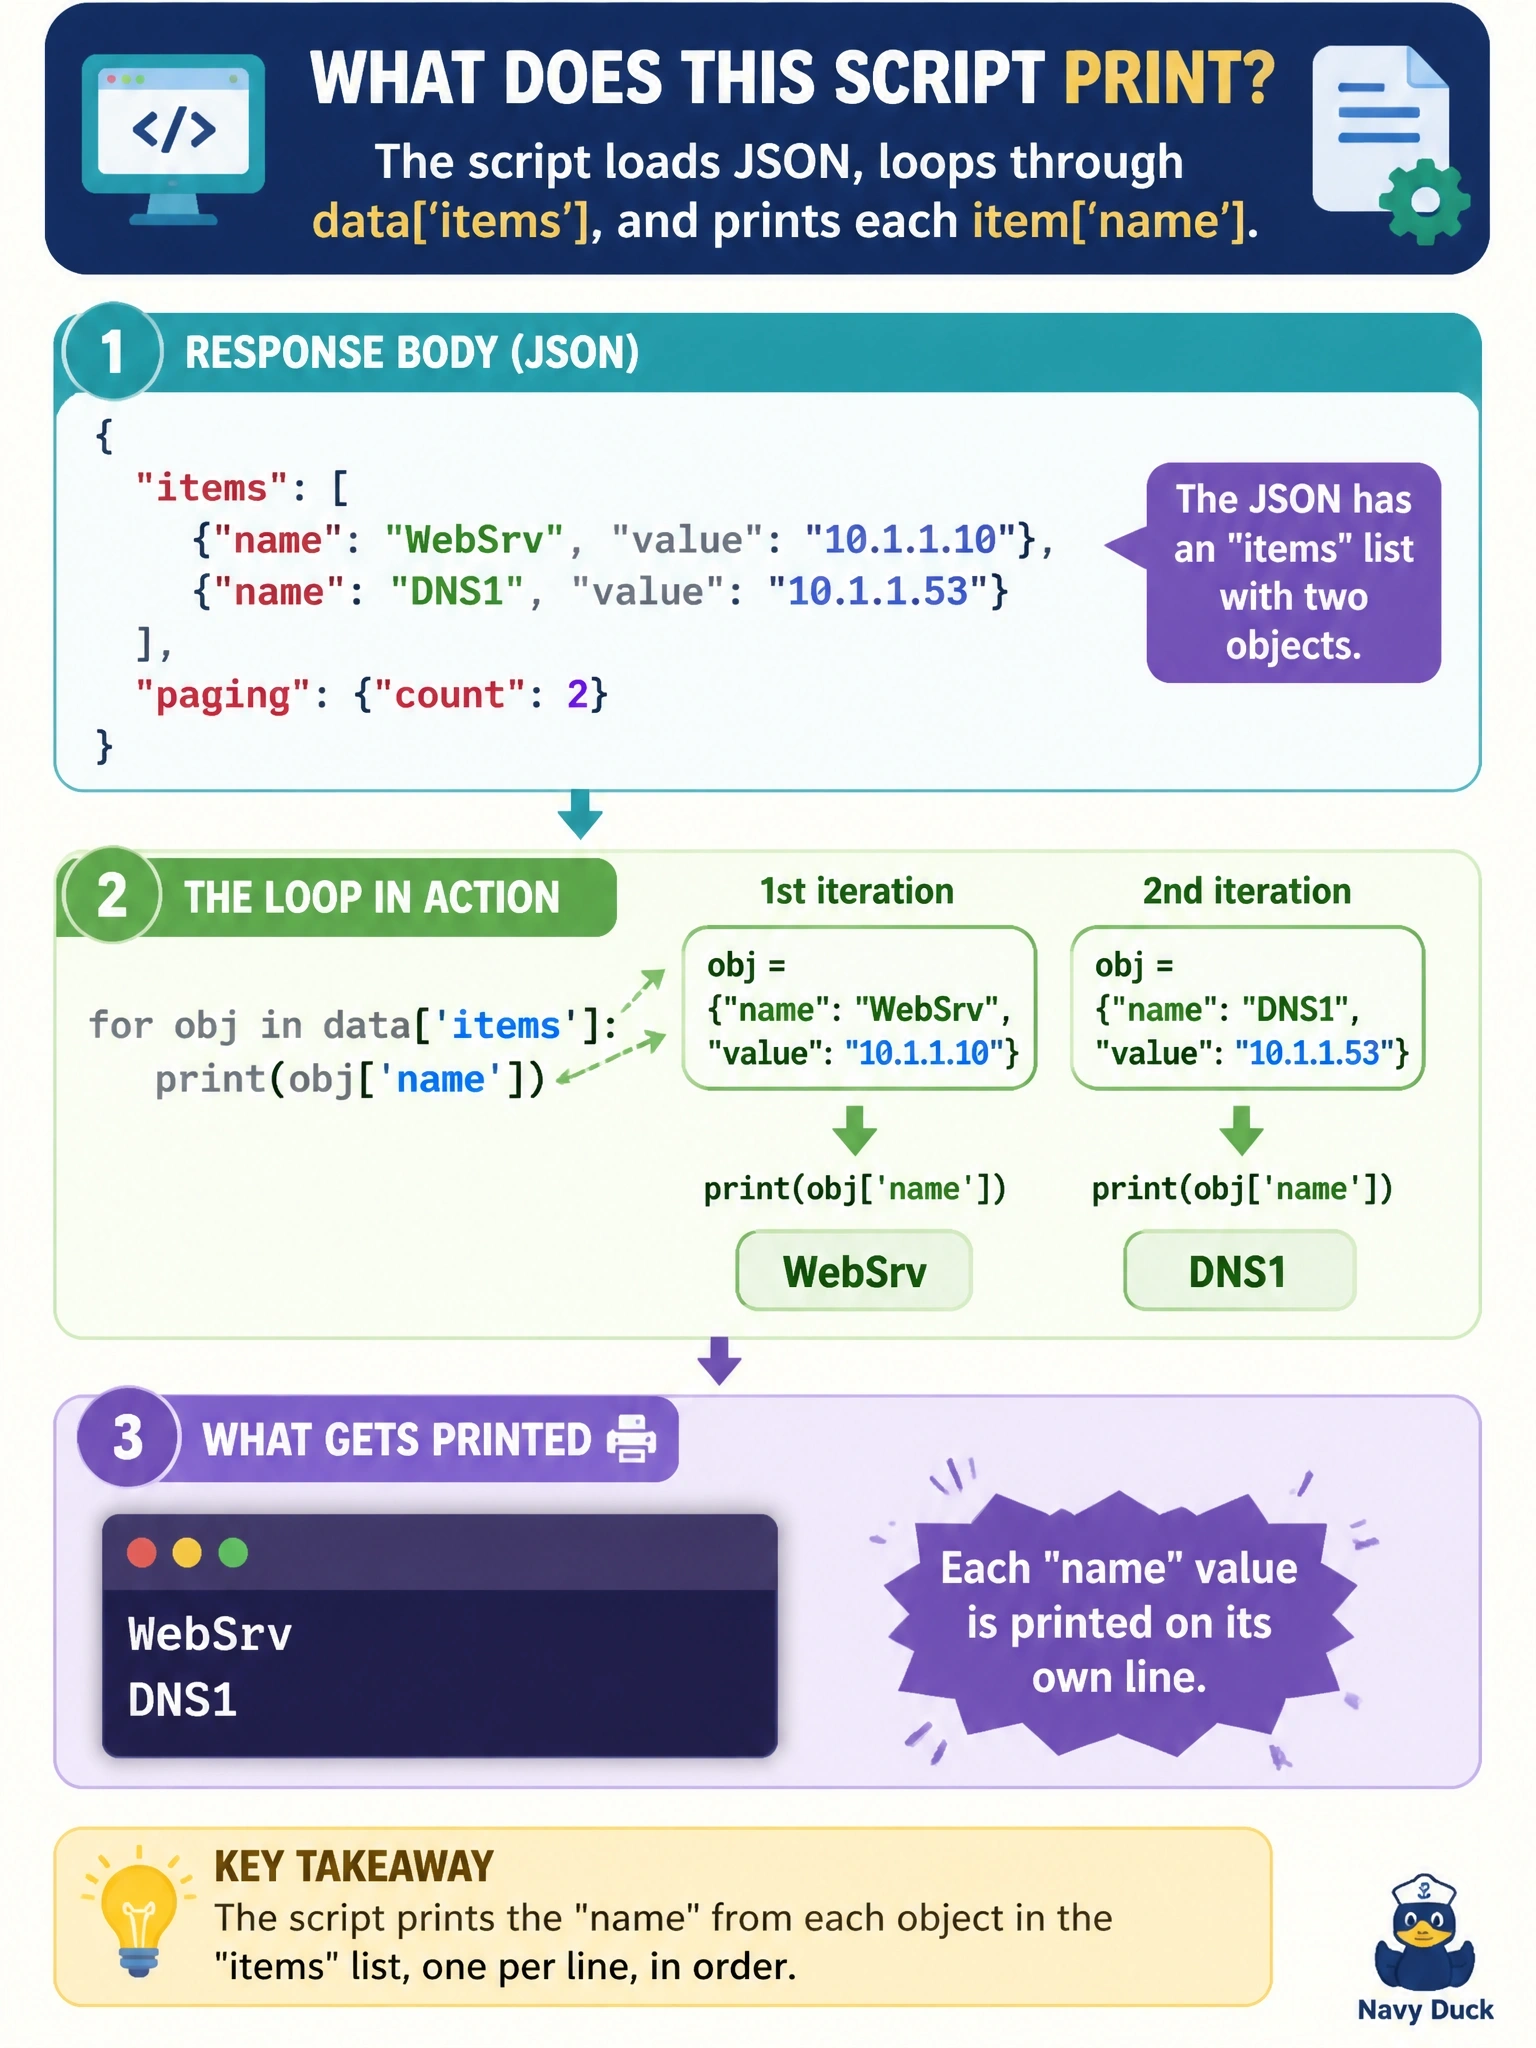
A script runs data = r.json() and then for obj in data['items']: print(obj['name']). The response body is {"items": [{"name": "WebSrv", "value": "10.1.1.10"}, {"name": "DNS1", "value": "10.1.1.53"}], "paging": {"count": 2}}. What does the script print?
Select an answer to reveal the explanation.
Short Explanation
Follow the data like a grocery list: you open the bag called items, pull out each thing, and read only its name tag. Two objects, two names, two lines. The trap is the value field sitting right next to it, which the script never asks for.
Full Explanation
r.json() parses the HTTP response body into Python structures: the outer JSON object becomes a dictionary and the JSON array becomes a list of dictionaries. data['items'] therefore returns a list with two dictionaries. The for loop iterates over that list, binding obj to each dictionary in turn, and print(obj['name']) outputs the value stored under the name key. Because print adds a newline by default, the output is WebSrv on one line followed by DNS1 on the next. The IP addresses are stored under the value key, which the script never references, so they are not printed. Printing the whole list as one string would require print(data['items']) without a loop; the loop prints individual fields. The paging count is in a separate dictionary that the script does not access; it is metadata describing how many items the page holds, often used to decide whether to request another page. Exam caveat: API interpretation items frequently place a tempting sibling field next to the one referenced; answer from the key the code actually uses. Operational check: when adapting such a script, confirm the response's real structure with print(json.dumps(data, indent=2)) and handle paging so that objects beyond the first page are not silently skipped.