
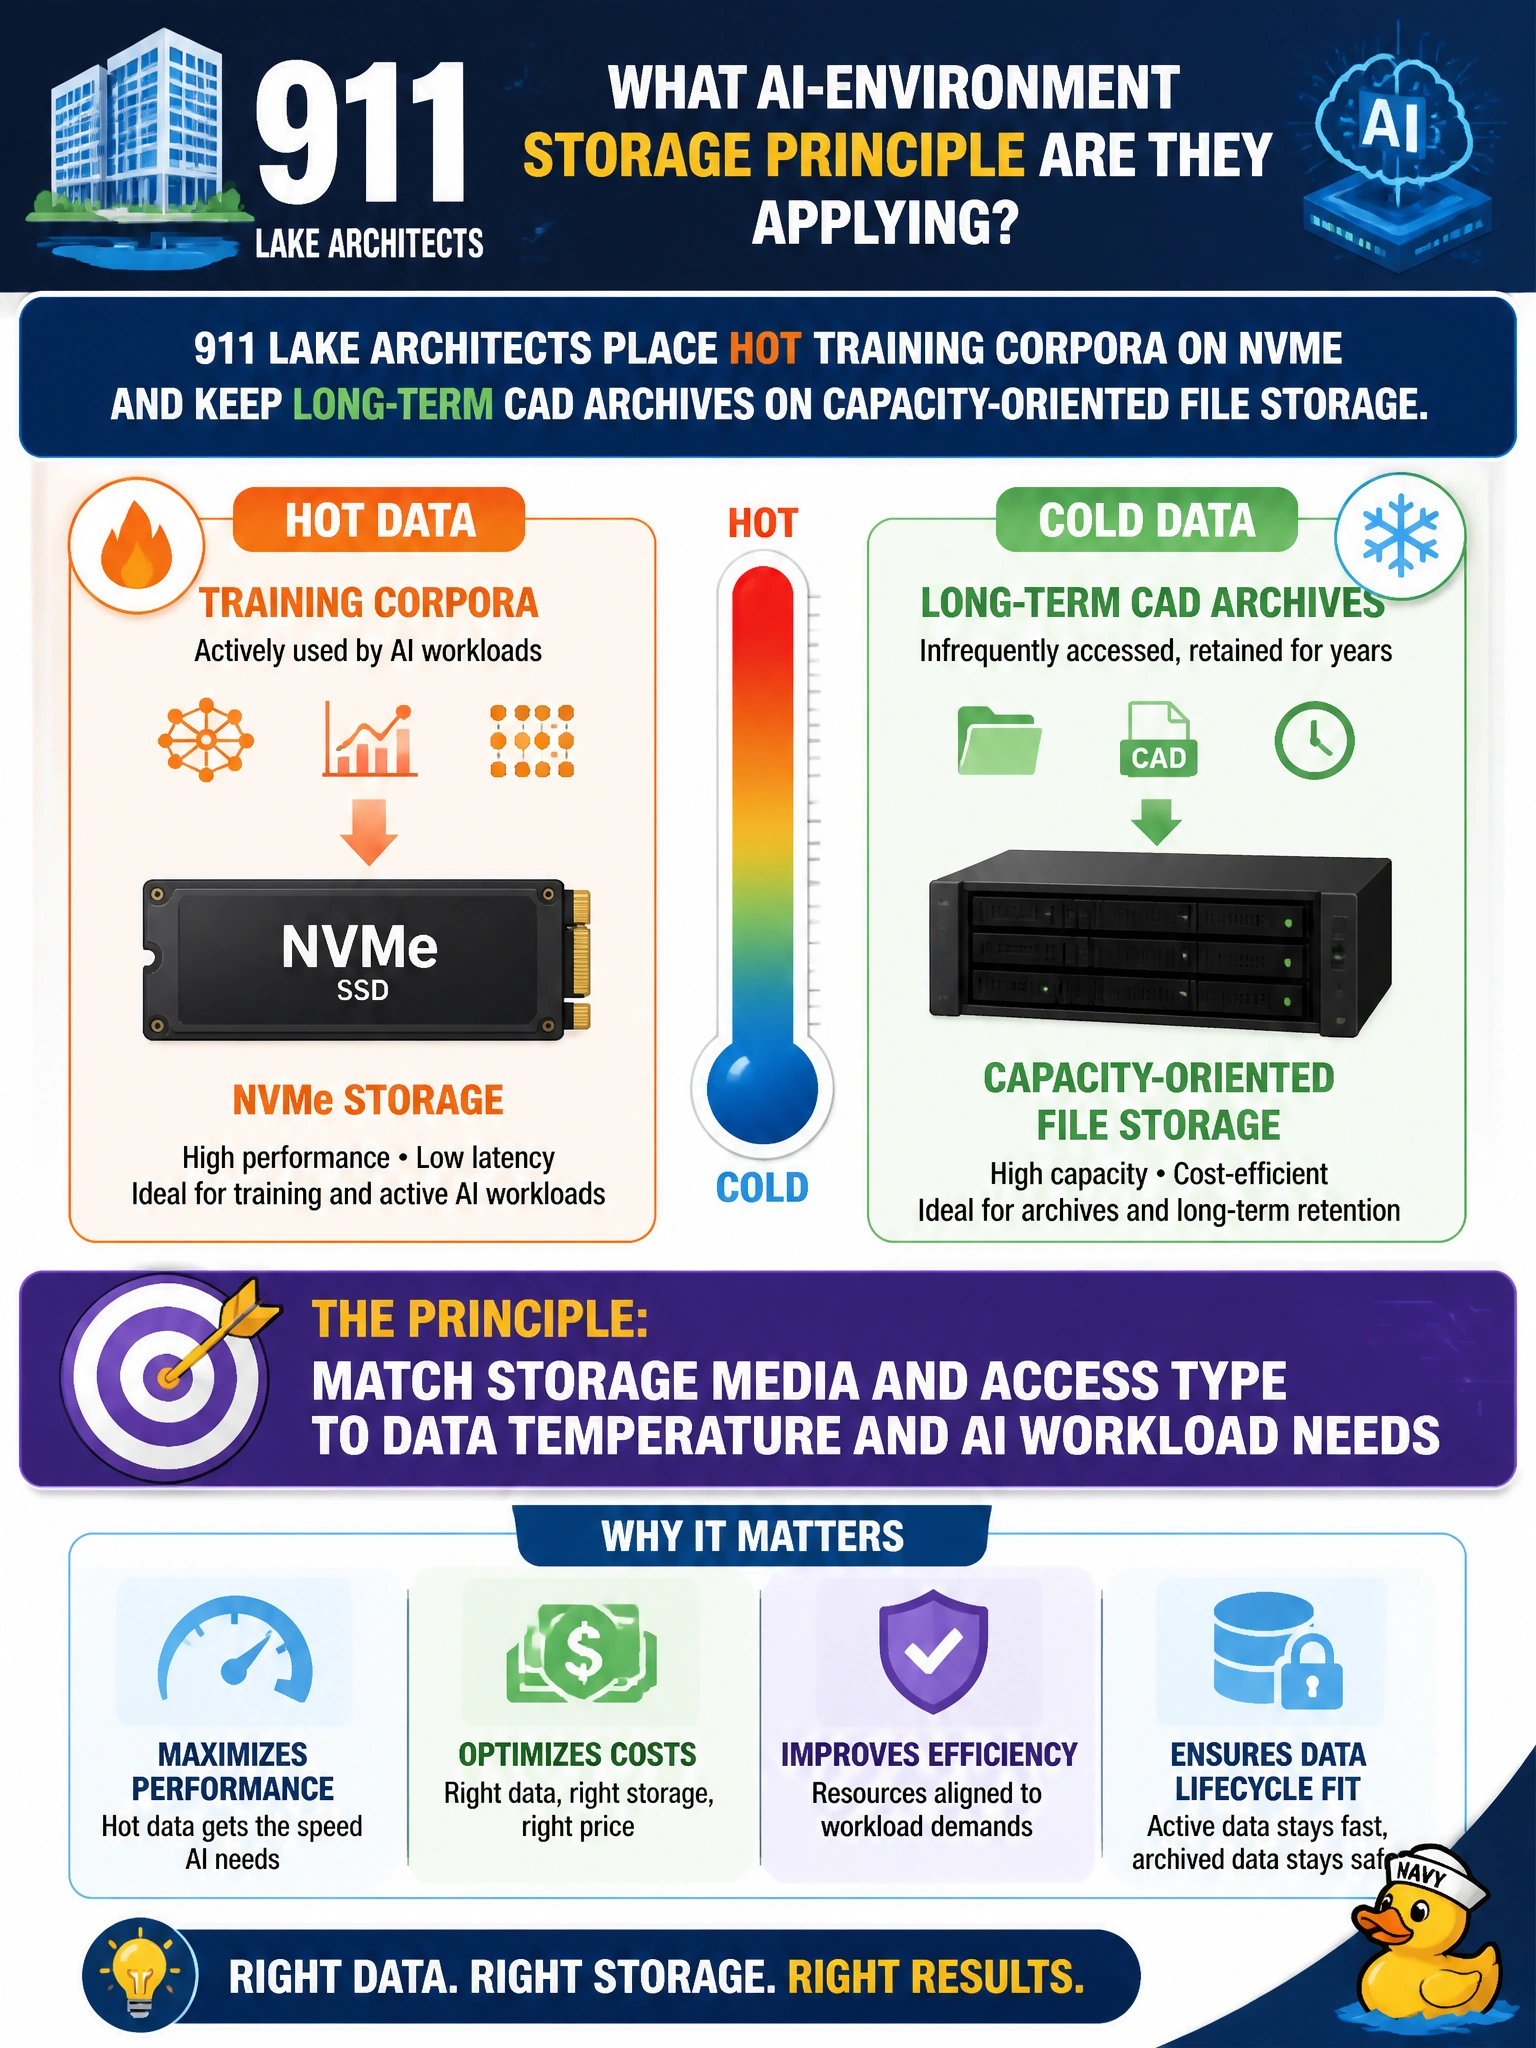
911 lake architects place hot training corpora on NVMe and keep long-term CAD archives on capacity-oriented file storage. What AI-environment storage principle are they applying?
Select an answer to reveal the explanation.
Short Explanation
Hot data wants a fast lane; cold archives can ride the slow bus. NVMe for active training sets keeps GPUs fed, while roomy file tiers hold the archives nobody reads every hour. Mixing tiers by temperature is just smart municipal storage planning.
Full Explanation
911 lake architects who place hot training corpora on NVMe and keep long-term CAD archives on capacity-oriented file storage are applying the principle of matching storage media and access type to data temperature and AI workload needs. Active training sets need low-latency, high-throughput media so GPUs stay fed; cold municipal archives need cost-efficient capacity with different access patterns. Tiering by temperature and workload is how civic AI environments avoid both starving trainers and overpaying for cold CAD history. Aligning parallel file striping to training checkpoint cadence for optimal IO balance describes stripe-tuning for checkpoint I/O, not the temperature-based choice of NVMe for hot corpora versus capacity file for cold archives in the scenario. Binding NVMe endurance rating to CAD archive retention policy for compliance assurance mixes drive write-endurance limits with retention compliance and still puts cold, rarely rewritten CAD history on expensive NVMe instead of capacity file storage. Mapping RDMA fabric priority to archive access frequency for serving throughput gains tunes fabric QoS for cold data that is rarely accessed, which does not explain or replace tiering hot training to NVMe and cold archives to capacity file. Exam caveat: AI-environment storage questions expect media and access type aligned to hot versus cold data and to training versus archive workloads—not aligning parallel file striping to checkpoint cadence, binding NVMe endurance to archive retention, or mapping RDMA priority to archive frequency as a substitute for proper tiering. Operational check: classify each municipal dataset by temperature and AI use, map hot training to NVMe or equivalent, map cold CAD archives to capacity file tiers, and measure GPU I/O wait to confirm the hot path is not the bottleneck.
Prefer to study offline? Printable PDF study book + test engine ($7.50, unofficial). These questions stay free here.