
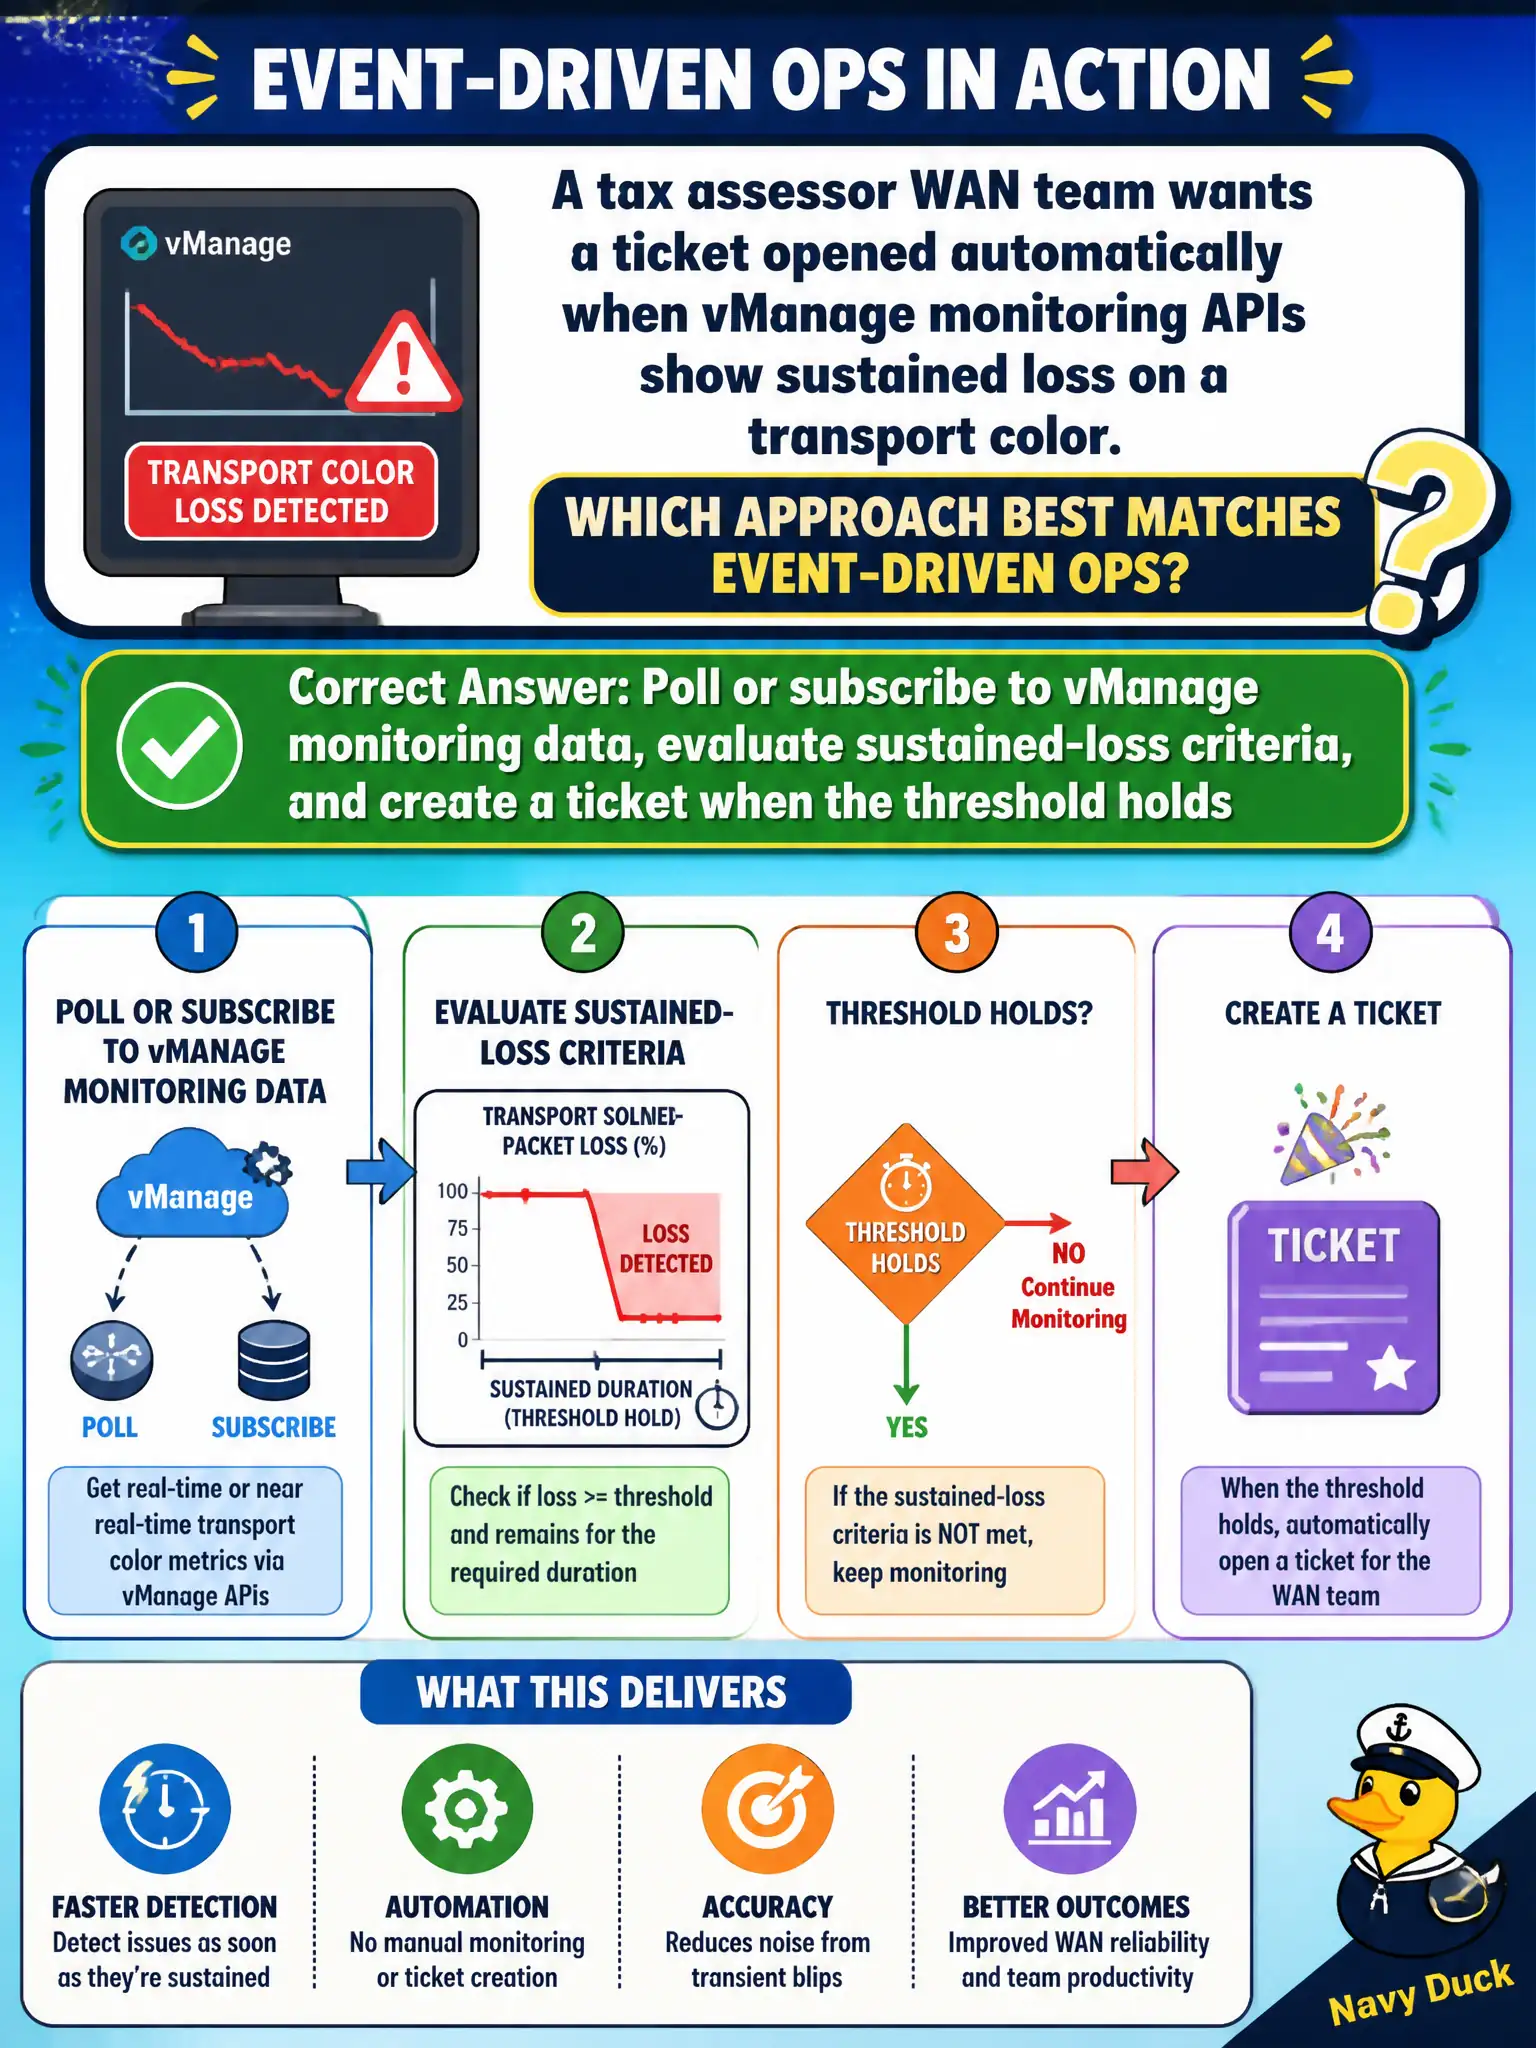
A tax assessor WAN team wants a ticket opened automatically when vManage monitoring APIs show sustained loss on a transport color. Which approach best matches event-driven ops?
Select an answer to reveal the explanation.
Short Explanation
If the underlay color is bleeding loss, do not wait for citizens to notice assessor apps are slow. Let automation watch vManage, decide when loss is sustained, and open the ticket. Weekly CSVs and silence are how problems age.
Full Explanation
Tax-assessor WAN teams wanting a ticket opened automatically when vManage monitoring APIs show sustained loss on a transport color should poll or subscribe to vManage monitoring data, evaluate sustained-loss criteria, and create a ticket when the threshold holds. Event-driven ops closes the loop from telemetry to ITSM without waiting for end users. Sustained criteria avoid flapping tickets on blips.
Waiting for end users to call after applications fail is reactive and slow. Emailing a weekly CSV of all colors regardless of thresholds buries signal. Disabling color monitoring so APIs stay quiet during loss events hides the problem.
Exam caveat: define sustained windows and severity mapping carefully—loss on a backup color may be warning while primary-color loss is critical. Operational check: simulate sustained loss in lab/monitoring fixtures, confirm ticket fields include site, color, and metric, then enable production with rate limits. Deduplicate tickets while loss persists. Record the chosen control and rejected alternatives in the municipal change record so future on-call engineers understand the failure modes avoided for city services. Re-validate after the next maintenance window that telemetry, API results, and device state still match the documented design intent.