
Thousands of assessor PDFs are queued for extraction. What should happen before the full batch?
Select an answer to reveal the explanation.
Short Explanation
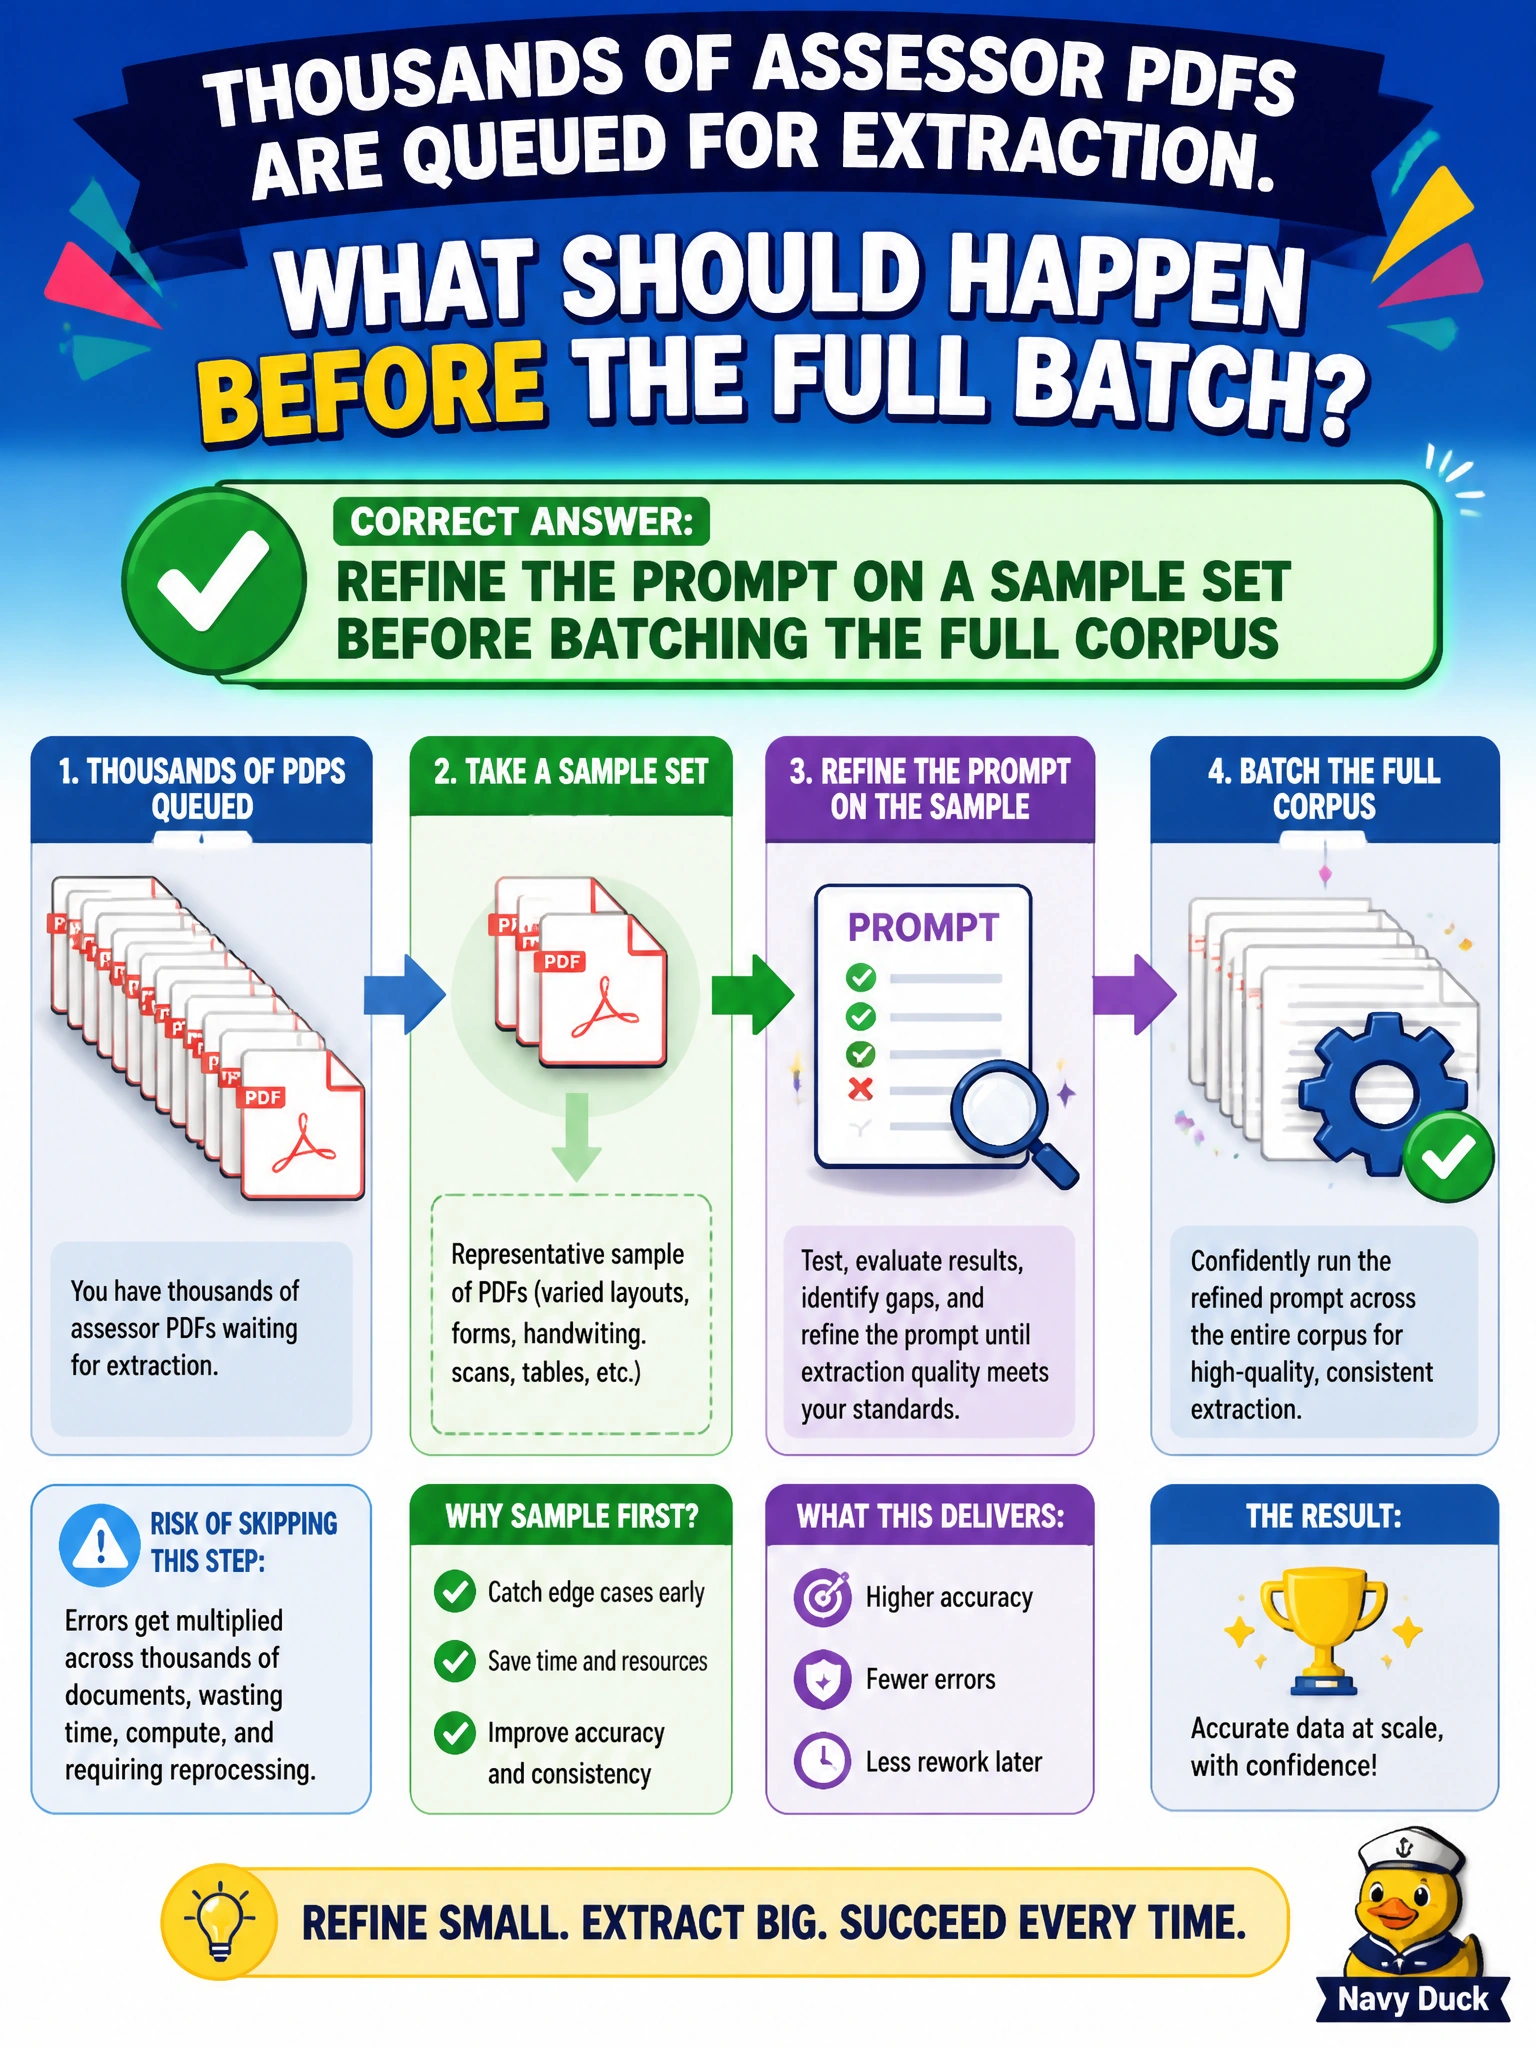
Taste-test a dozen PDFs before cooking for the whole county. Refine on a sample, then batch the thousands.
Full Explanation
Before enqueueing thousands of assessor PDFs into a full Message Batch, refine the prompt and schema on a representative sample set. Sample-first iteration catches systematic OCR edge cases, field misunderstandings, and fee or legal-description quirks while the blast radius is still small and cheap. Only after sample metrics look acceptable should the full corpus run. Shipping the untested prompt to the entire corpus immediately maximizes the cost of discovering a systemic bug across thousands of municipal documents. Skipping sampling because batch scale always improves quality confuses throughput with accuracy—larger volume does not magically fix a wrong instruction. Changing schemas only after all thousands of results return delays learning and forces expensive reprocessing of the whole set when a sample would have revealed the fix earlier. Exam caveat: the sample must reflect real diversity (scan quality, form versions, jurisdictions), not only clean happy-path PDFs. Operational check: define acceptance thresholds on a stratified sample of assessor packets, freeze the prompt and schema when those thresholds pass, then submit the full batch and spot-check residual failures against the same metrics before declaring the municipal extract complete.