
In a multi-agent 911-dispatch data pipeline, a specialist subagent encounters an unrecoverable error partway through validating incident records and cannot complete its task. What should happen next in a well-designed multi-agent workflow?
Select an answer to reveal the explanation.
Short Explanation
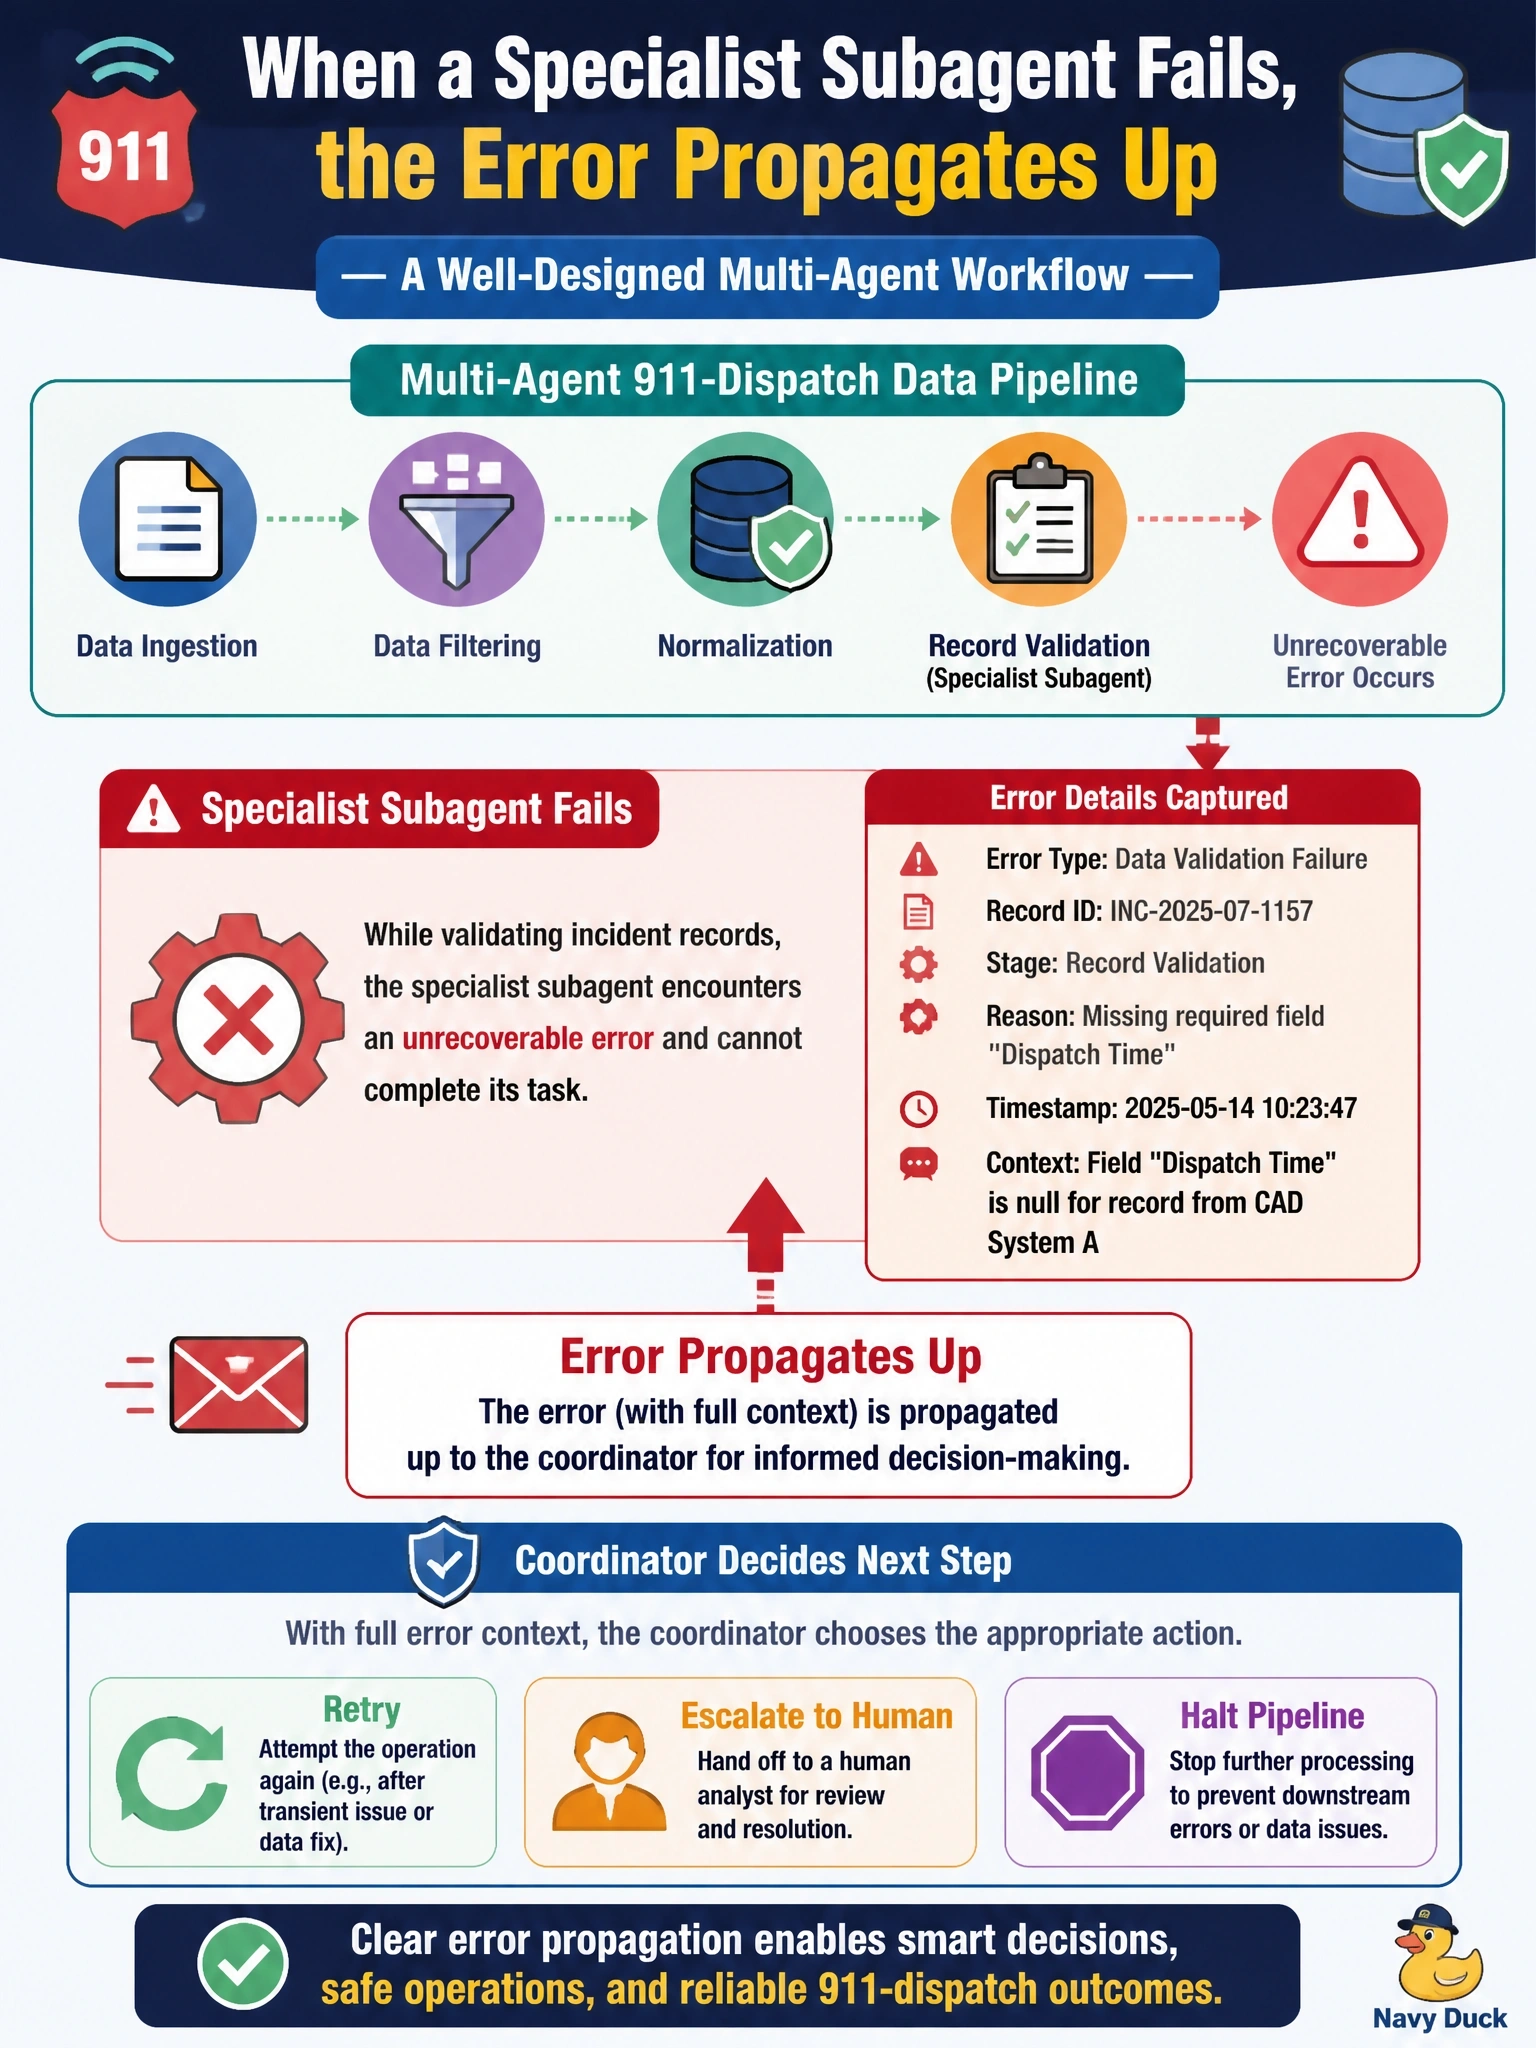
A field responder who hits a dead end does not invent a clean status update. A failing subagent should report the failure upward with enough detail for the coordinator to retry, escalate, or halt.
Full Explanation
In a multi-agent pipeline the coordinator is the only component positioned to decide what a failure means, because it alone knows what else is running, what the run is for, and what the stakes are. A specialist's job when it cannot complete is therefore to make its failure legible to that coordinator, not to resolve it locally or to hide it behind a normal-looking return value.
Propagating a clear, structured account of what went wrong gives the coordinator the information it needs to choose among retrying the validation, escalating to a human reviewer, or halting the affected part of the pipeline. For 911-dispatch incident records the alternative is worse than a stalled run, because opaque failure handling means downstream steps consume validation results that were never actually produced.
Fabricating a plausible result to avoid reporting failure is dangerous anywhere and indefensible for emergency-dispatch data, since decisions would then rest on invented records; ignoring the failure and proceeding as though the task succeeded lets missing or bad validation silently corrupt the output while the run reports success; and redesigning the entire pipeline from scratch is disproportionate to one runtime error and does nothing about the failure sitting in front of the coordinator right now.
Exam caveat: propagation is only useful if the coordinator actually branches on it, since an error that arrives as an unread string is functionally the same as a swallowed one. Operational check: inject a forced failure into one specialist, then confirm the coordinator's log shows a distinct retry, escalation, or halt decision rather than the run continuing unchanged.