
You train a computer vision model to classify different types of watercraft. The model performs exceptionally well in testing, but when deployed, it fails to identify boats that are dry-docked on land or sitting on trailers. What is the most likely cause of this failure?
Select an answer to reveal the explanation.
Short Explanation
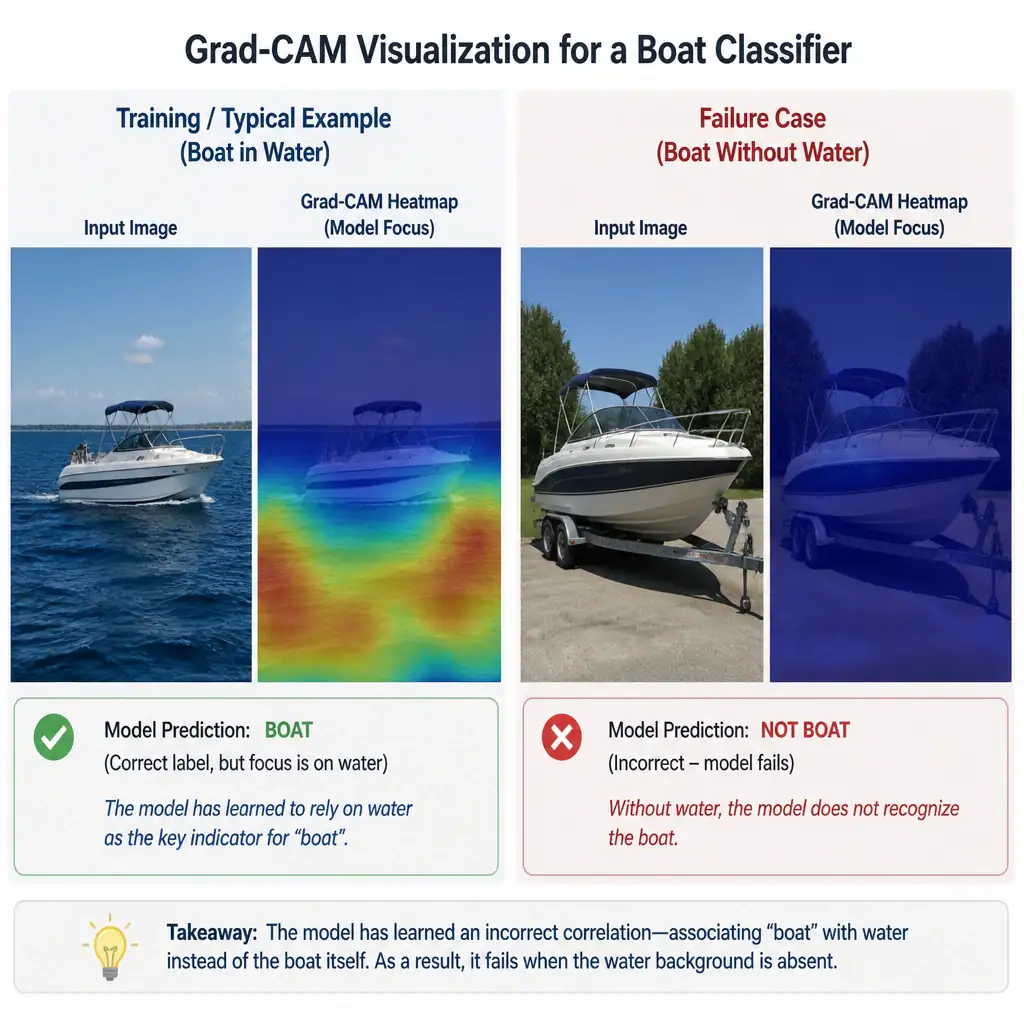
Pay close attention here, because this bites people in production all the time. If every boat photo shows water, you've trained the model to learn 'water equals boat' instead of the boat itself, so it fails when the boat is dry-docked or on a trailer. Make your training images have diverse backgrounds, or you'll deploy a model that works great in the lab but falls flat in the wild.
Full Explanation
In computer vision, convolutional neural networks are highly sensitive to correlation patterns in the training data. A common issue is the learning of spurious correlations, where a model associates the background context of an image with the target label, rather than focusing on the actual object of interest. This is a specific form of overfitting to background context: spurious correlations arise when all training images of a certain object, such as boats, contain a specific background, such as water, so the optimization algorithm finds that detecting water pixels is an easy shortcut to achieving low training loss. Generalization failure follows when the model is presented with a boat in an unusual context, such as dry-docked on land or sitting on a trailer, because the expected background features are missing even though the object features are clearly visible. To resolve this issue, machine learning engineers use several techniques: data augmentation, applying transformations like random cropping, background swapping, or mixing images; dataset diversity, ensuring the training data includes objects set against varied and diverse backgrounds; and saliency maps or explainability, utilizing tools like Grad-CAM to visualize which pixels the model is focusing on to verify that it is looking at the object rather than the background. The other explanations are incorrect: the high-bias claim that the model has not learned enough features to represent any boat category is wrong because high bias would cause the model to perform poorly on all data, including the training set; the black-box claim that the model mathematically cannot process terrestrial background pixels during inference is wrong because the black-box nature of neural networks describes their lack of interpretability but is not a physical barrier to processing pixels; and the too-many-pooling-layers claim that spatial variance is completely flattened is wrong because pooling layer configuration affects resolution and spatial invariance but does not target background features specifically.