
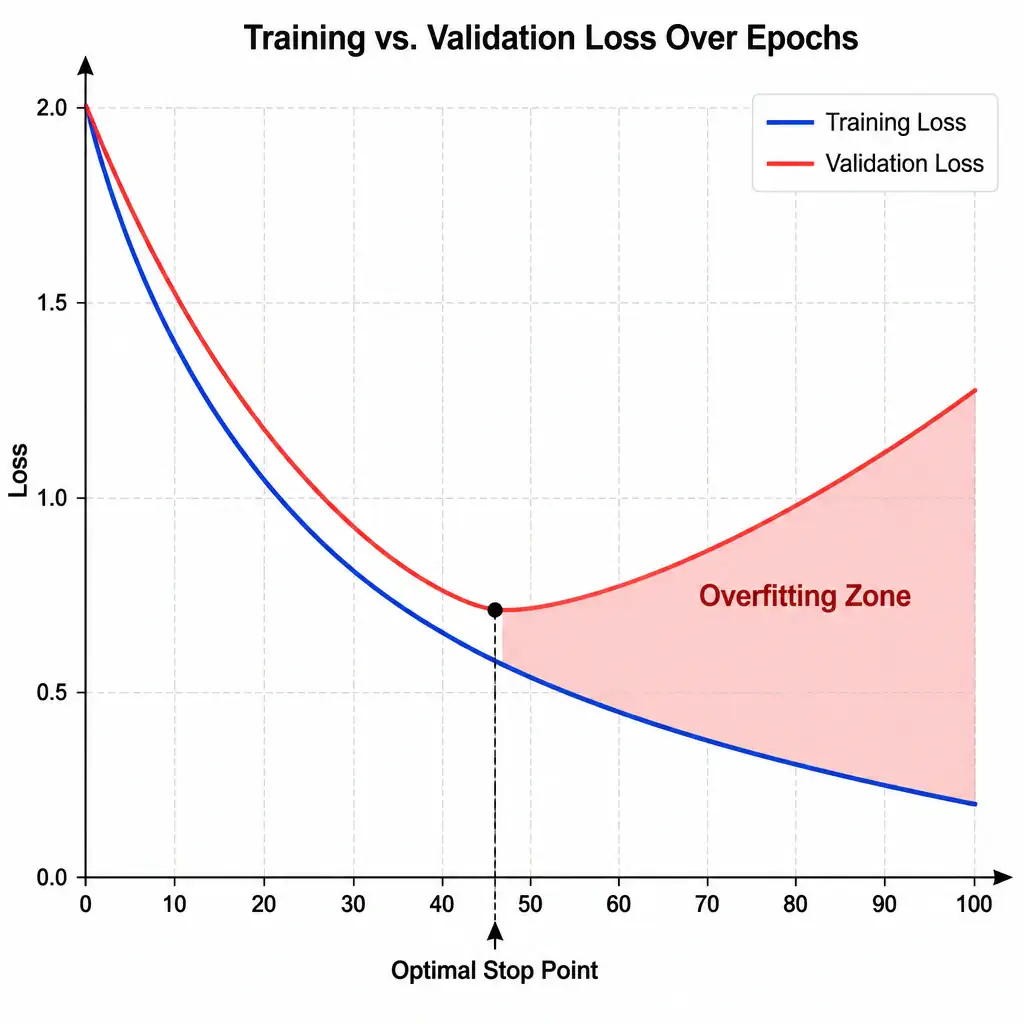
While training a deep learning model, you plot the loss curves. You notice that the training loss continues to drop steadily, but the validation loss reaches a minimum and then begins to climb upward. What problem is the model experiencing?
Select an answer to reveal the explanation.
Short Explanation
You're seeing classic overfitting. The model keeps improving on training data but starts memorizing noise instead of general patterns, so validation loss climbs. Watch that gap closely, because it bites people in production all the time.
Full Explanation
Overfitting occurs when a machine learning model learns the training data too well, capturing the noise, random fluctuations, and specific details of the training set rather than the underlying general relationships. This degrades the model's ability to generalize to new, unseen data.
The classic signature of overfitting is a diverging trend between training and validation metrics. As training progresses: - The training loss continues to decrease because the model parameters are continuously optimized to fit the training examples. - The validation loss initially decreases but eventually hits a minimum and starts to increase. This divergence indicates that while the model is getting better at predicting the training set, its performance on validation data (unseen data representing real-world generalization) is actively worsening.
Common causes of overfitting include excessive model complexity (too many parameters relative to the amount of training data), training for too many epochs, or lack of regularization. Solutions include early stopping, applying dropout, adding L1/L2 regularization, or collecting more training data.
Let's address the distractors: - The insufficient dataset size condition can make a model more prone to overfitting, but the direct signal described (training loss decreasing while validation loss increases) is the definition of overfitting itself, not the dataset size. - The underfitting condition is characterized by both training and validation loss remaining high because the model is too simple to learn the data. - The extremely low learning rate condition would result in extremely slow convergence where both losses decrease very slowly, but it would not cause validation loss to diverge and increase.
Therefore, overfitting is the correct answer.