
When processing long sequences of text or time-series data, standard Recurrent Neural Networks (RNNs) often fail because gradients shrink to zero during backpropagation, causing the network to forget early information. Why does a Long Short-Term Memory (LSTM) network solve this issue?
Select an answer to reveal the explanation.
Short Explanation
Standard RNNs forget early information because gradients shrink toward zero during backpropagation. LSTMs fix this by adding a cell state and gates that control what information is kept, updated, and passed forward, so long-term dependencies can survive training.
Full Explanation
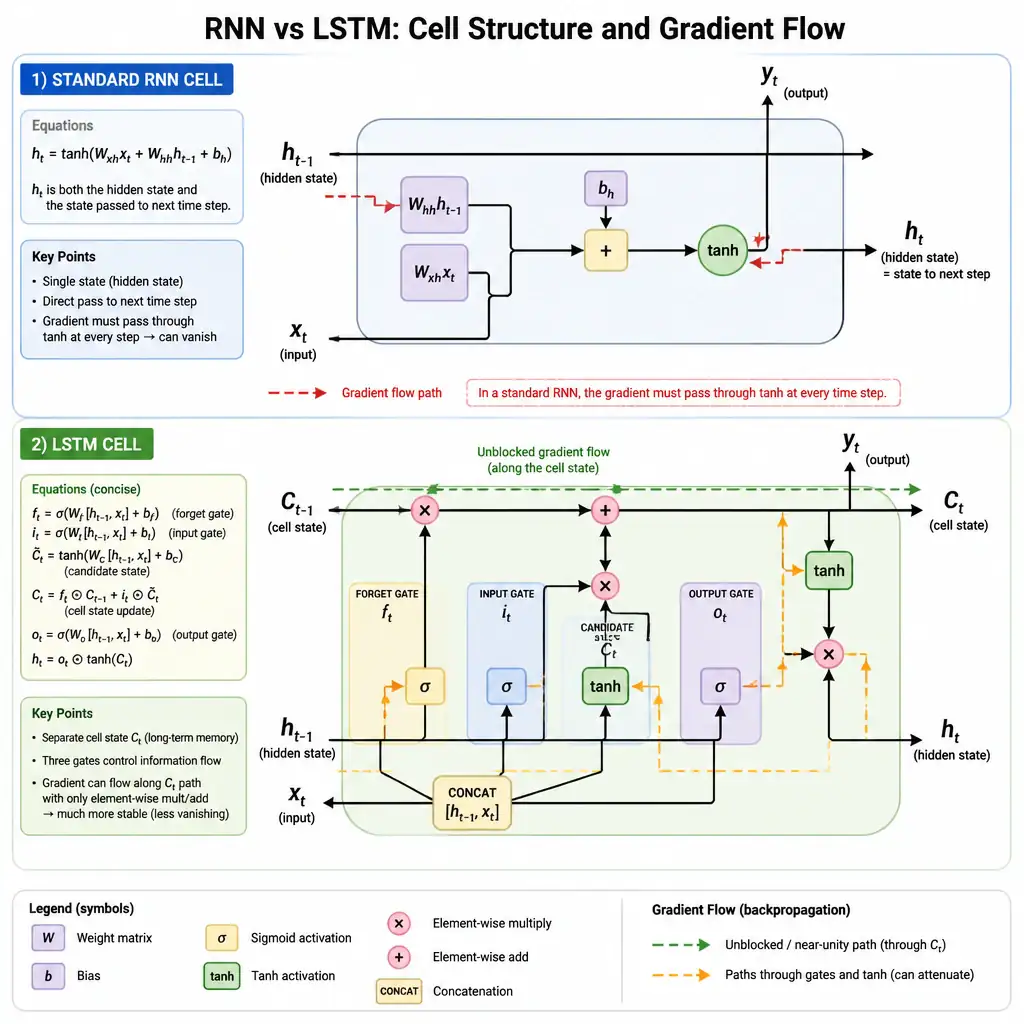
Standard Recurrent Neural Networks (RNNs) suffer from the vanishing gradient problem. When backpropagating through long sequences, the gradients are repeatedly multiplied by weights. If these weights are small, the gradient shrinks exponentially, preventing the network from updating the weights of its earliest layers. Consequently, standard RNNs fail to learn long-term dependencies in sequential data.
Long Short-Term Memory (LSTM) networks solve this issue by introducing a more complex node structure. Instead of relying on a single simple recurrent update, LSTMs use a cell state that acts as a continuous memory line running through the steps, along with three interactive gates: 1. Forget Gate: Decides what information from the previous cell state should be discarded. 2. Input Gate: Decides which new information should be stored in the cell state. 3. Output Gate: Controls what information from the current cell state is output as the hidden state.
Mathematically, the cell state allows gradients to flow backward through time with minimal attenuation, using addition operations instead of pure multiplications, which directly mitigates the vanishing gradient problem. This allows LSTMs to capture long-term context in text translation, speech recognition, and time-series forecasting.
The distractors are incorrect. The claim that the network replaces the recurrent structure with convolutional layers and is limited strictly to two-dimensional image datasets is wrong because LSTMs are sequence models, not image-only architectures. The claim that the network simplifies the architecture by removing the hidden state is wrong because an LSTM is structurally far more complex than a standard RNN, containing multiple internal neural network layers per cell and retaining a hidden state alongside the cell state. The claim that the network uses a stateless feedforward design requiring significantly less computational power and training time is wrong because LSTMs are actually more computationally expensive to train than standard RNNs due to this added complexity and the sequential nature of recurrence, which prevents parallel training.