
You're preparing a dataset of text reviews for a sentiment classification model. To clean the text and reduce the overall size of the vocabulary, you need to strip out common filler words (like "the" and "is") and convert verbs and nouns back to their root dictionary form. Which preprocessing techniques should you apply?
Select an answer to reveal the explanation.
Short Explanation
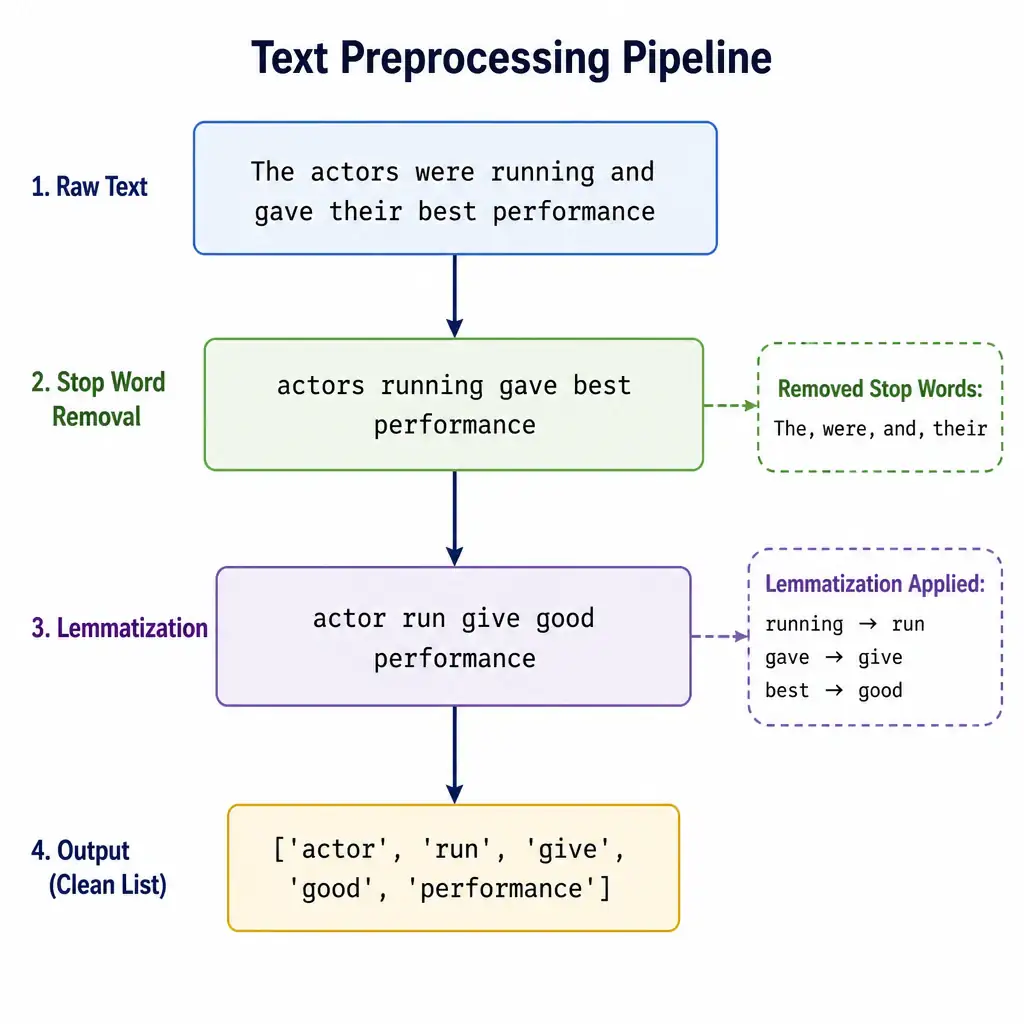
When you're cleaning text reviews, drop stop words like 'the' and 'is' and use lemmatization to map words like 'running' and 'ran' back to 'run'. That trims filler and shrinks the vocabulary so your sentiment model focuses on meaningful words.
Full Explanation
In Natural Language Processing (NLP), text preprocessing is a critical step to convert raw, unstructured text into a clean format suitable for machine learning models. For tasks like sentiment analysis, two foundational preprocessing techniques are stop-word removal and lemmatization.
Stop-word removal targets words that appear frequently in a language but carry minimal semantic value for sentiment (e.g., articles like 'the', 'a', prepositions like 'in', 'under', and auxiliary verbs like 'is', 'was'). Removing them reduces noise and allows the model to focus on content-rich terms that dictate sentiment (e.g., adjectives like 'fantastic' or 'disastrous').
Lemmatization is the process of grouping together the inflected forms of a word so they can be analyzed as a single item, identified by the word's lemma (its dictionary form). Unlike stemming, which crudely chops off word endings, lemmatization uses vocabulary and morphological analysis to accurately return roots (e.g., converting 'better' to 'good' or 'studies' to 'study'). This reduces the dimensionality of the text representation and helps the model generalize across different tenses and pluralities.
The one-hot encoding of raw sentence tokens represents categories as binary vectors but does not clean text or reduce vocabulary size when applied to raw text directly. The Principal Component Analysis dimensionality-reduction approach is a mathematical dimensionality reduction technique for numeric matrices, not a text-cleaning step. The K-Means clustering approach for grouping raw strings is an unsupervised learning algorithm, not a text preprocessing technique. Thus, lemmatization and stop-word removal are the correct preprocessing steps for this NLP task.