
A data scientist trains a deep neural network for image classification. They observe that the model achieves 99.5% accuracy on the training dataset, but when evaluated on the independent test dataset, the accuracy drops to 65.2%. What training phenomenon is this model exhibiting?
Select an answer to reveal the explanation.
Short Explanation
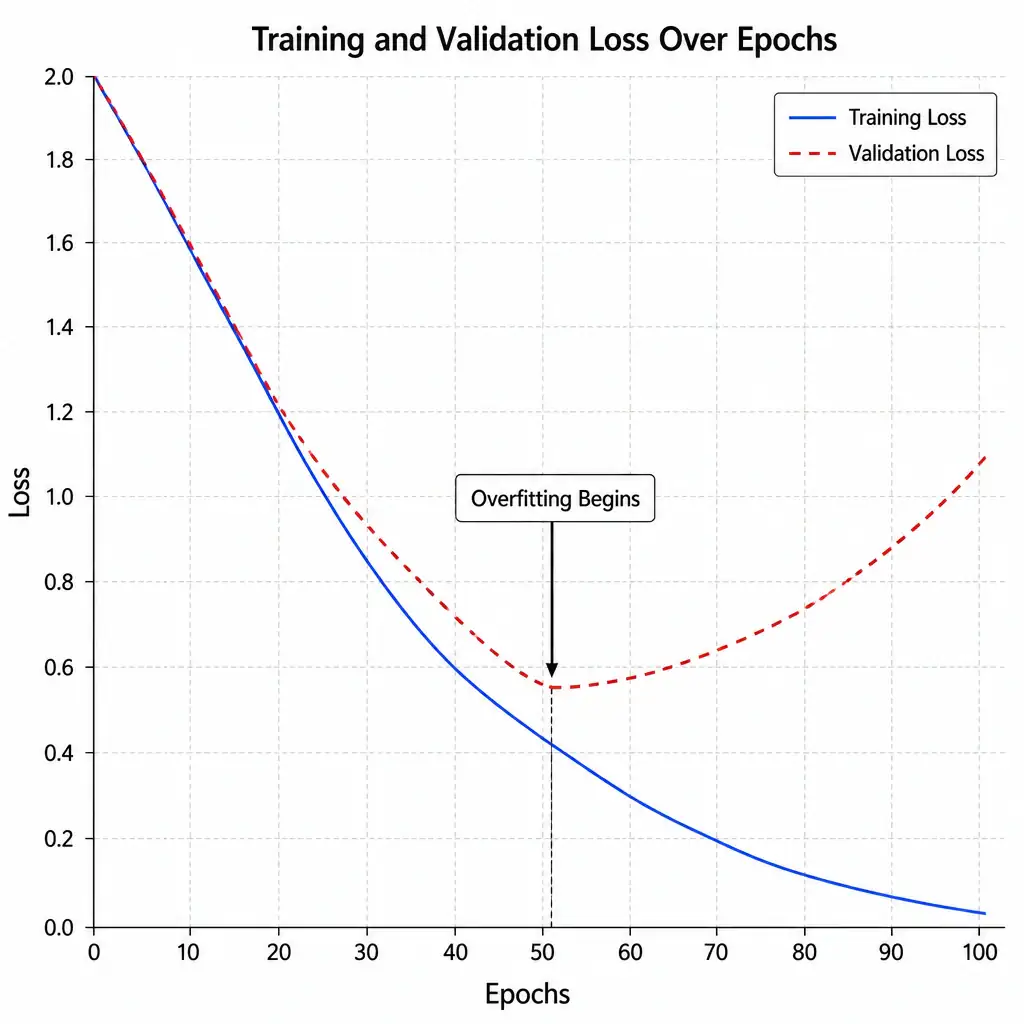
You train a deep model, it nails the training set at 99.5%, then tanks on unseen test data at 65.2%. That's overfitting, or overlearning: the model memorized noise instead of real patterns. Fix it with regularization, dropout, or more data.
Full Explanation
The discrepancy between a very high training accuracy and a significantly lower testing accuracy is the classic signature of overfitting, also known as overlearning. Overfitting occurs when a model learns the detailed patterns, noise, and statistical fluctuations in the training dataset to such an extent that it negatively impacts the model's ability to generalize to new, unseen data.
Overfitting (Overlearning) is correct because a model that overfits has high variance, meaning its predictions are highly sensitive to the specific training data points it was exposed to.
The high-bias choice is incorrect because high bias indicates that the model is too simple to learn the underlying patterns, resulting in poor performance on both the training and testing datasets.
The underfitting choice is incorrect because underfitting is characterized by low training accuracy, which is the opposite of the scenario described.
The low-learning-rate choice is incorrect because a low learning rate affects the speed of convergence during training but is not the structural cause of a generalization gap between training and testing data.