
A machine learning team deployed a model that recommends streaming content to users. A few weeks later, a major international sporting event begins, and the recommendations suddenly become highly irrelevant for a large portion of the user base. The engineering team analyzes the system and finds that the statistical distribution of the incoming user feature data has changed significantly, while the model's logic remains untouched. What specific issue does this represent?
Select an answer to reveal the explanation.
Short Explanation
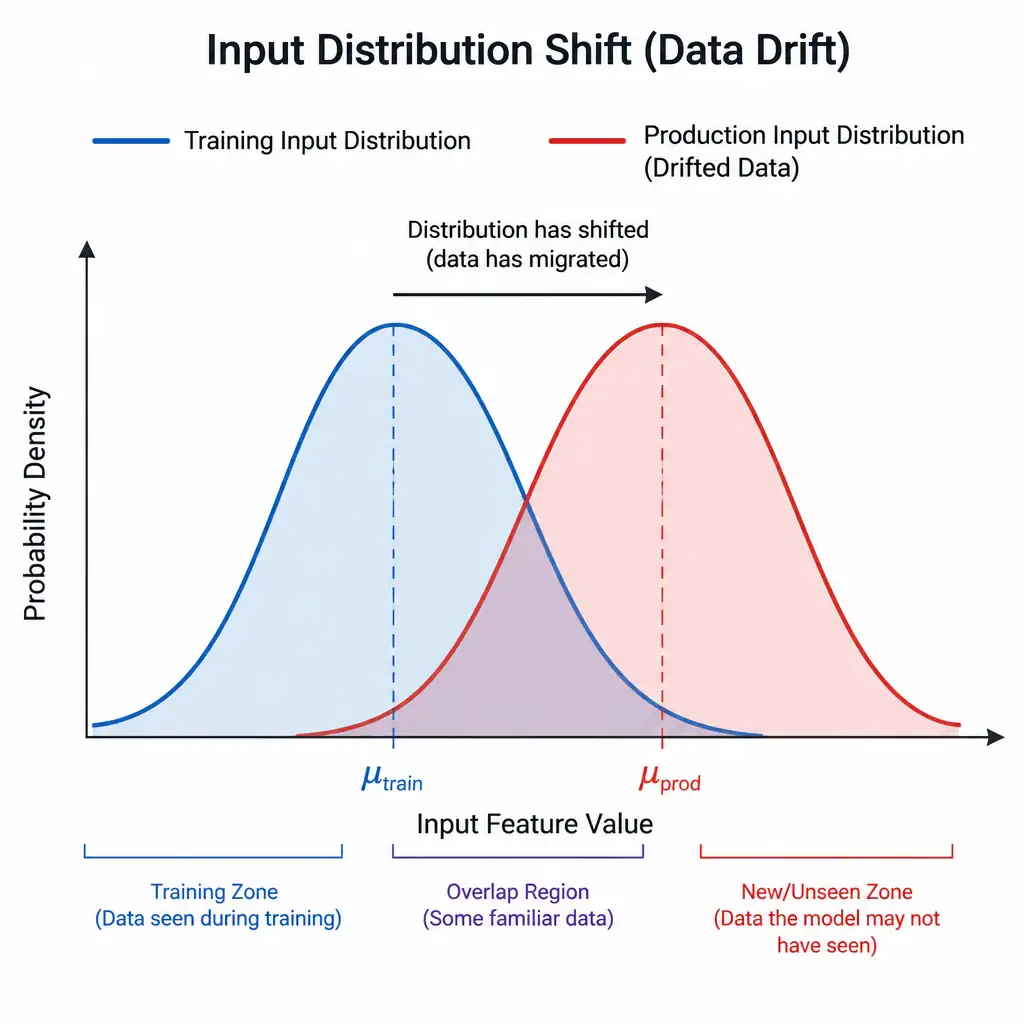
You deploy a recommendation engine, it works fine, then a major sporting event changes user behavior and the input data distribution shifts. Your model logic didn't change, but the incoming data did—that's data drift. Watch your input data, or you'll be serving bad recommendations.
Full Explanation
Data drift, also known as covariate shift, occurs when the input data distribution changes over time while the underlying relationship between the input features and the target labels remains unchanged. In this scenario, the international sporting event shifted the demographics and behavior of active users, altering the feature space that the model was trained on, which led to a degradation in recommendation relevance. The correct issue is the data drift description, because it describes the shift in the statistical distribution of the input variables while the model's logic remains untouched. The concept drift description is incorrect because concept drift refers to a change in the relationship between input features and target labels, meaning what defines the target concept changes, such as what constitutes spam, even if the inputs look similar. The model underfitting description is incorrect because underfitting is a training-phase problem where a model is too simple to capture the underlying patterns, not a production-time change in incoming data. The overlearning description is incorrect because overlearning, or overfitting, is a training-phase issue where a model memorizes the training data noise instead of generalizing, rather than a shift in production data distribution.