
During the training of a neural network, a developer implements a learning rate scheduler (or planner). What is the primary purpose of this component?
Select an answer to reveal the explanation.
Short Explanation
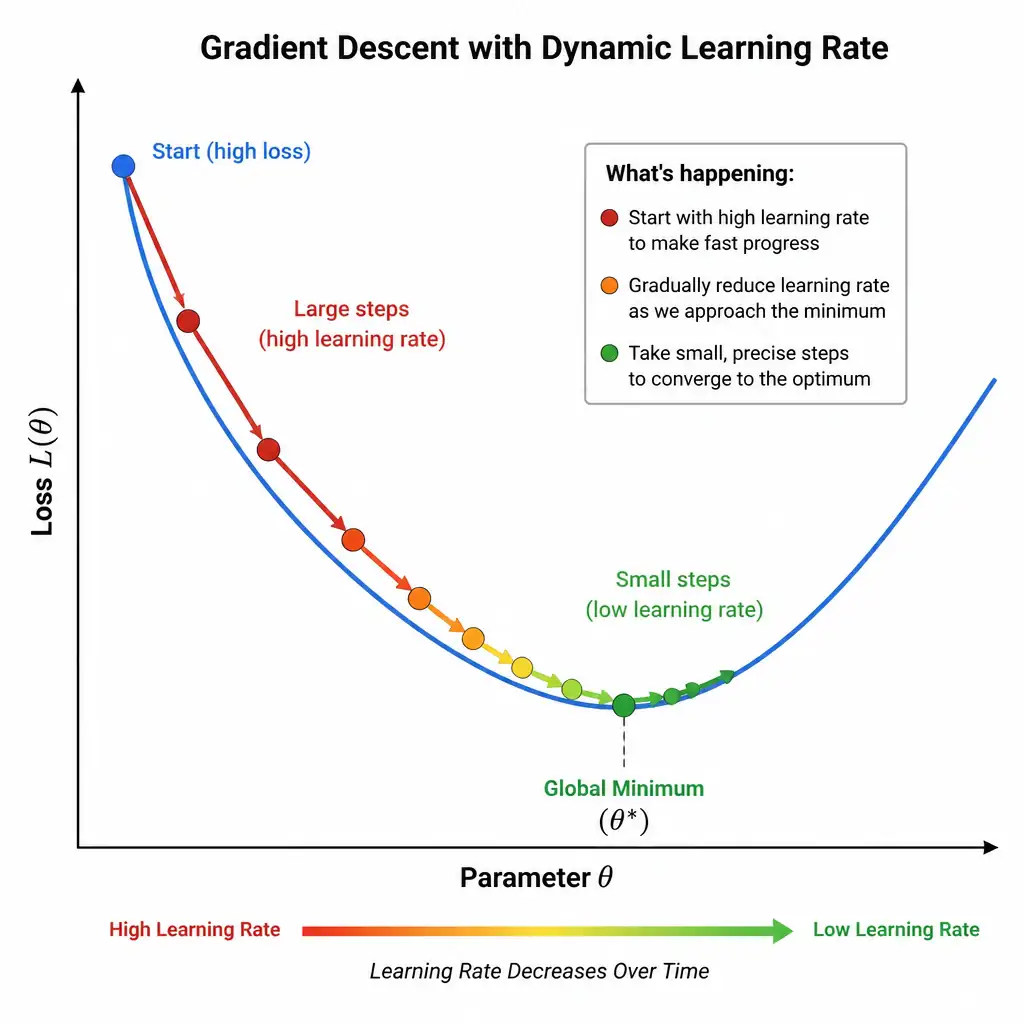
Think of the learning rate like your speed when you're driving toward a destination: too fast and you overshoot, too slow and you crawl. A learning rate scheduler is smart cruise control, starting fast then slowing as you approach the loss minimum. That dynamic step-size adjustment helps you converge quickly and avoid getting stuck in bad local minima.
Full Explanation
A learning rate scheduler, or planner, is used to adjust the learning rate during the training process according to a predefined schedule or based on validation metrics. The learning rate is a hyperparameter that controls how much the model's weights are updated in response to the estimated error gradient. If the learning rate is kept constant and is too high, the optimization algorithm may oscillate around the minimum or diverge. If it is too low, training will be prohibitively slow and may get trapped in suboptimal local minima. The correct statement is the one describing dynamic adjustment of the step size throughout training: a planner can start with a larger rate for rapid progress and decrease it over time, using techniques such as step decay, exponential decay, cosine annealing, or reduced learning rate on plateau, to allow fine-tuning of the weights and improve convergence speed while reducing the chance of getting trapped in suboptimal local minima. The other statements are incorrect. Automatically selecting the best optimization algorithm, such as switching from SGD to Adam, is a structural hyperparameter choice made by the developer before training, such as electing Adam, RMSprop, or SGD, and is not dynamically changed by a learning rate scheduler. Dynamically increasing the total number of epochs if the model has not converged is typically handled by early stopping mechanisms or static training configurations, not by the learning rate scheduler. Applying L1 and L2 penalty terms to the model's loss function to prevent overfitting is model regularization, such as L1 (Lasso) and L2 (Ridge) weight decay, which penalizes large weights and is distinct from adjusting the learning rate step size.