
When preprocessing textual data for a Natural Language Processing (NLP) pipeline, what is the primary goal of applying lemmatization to the corpus?
Select an answer to reveal the explanation.
Short Explanation
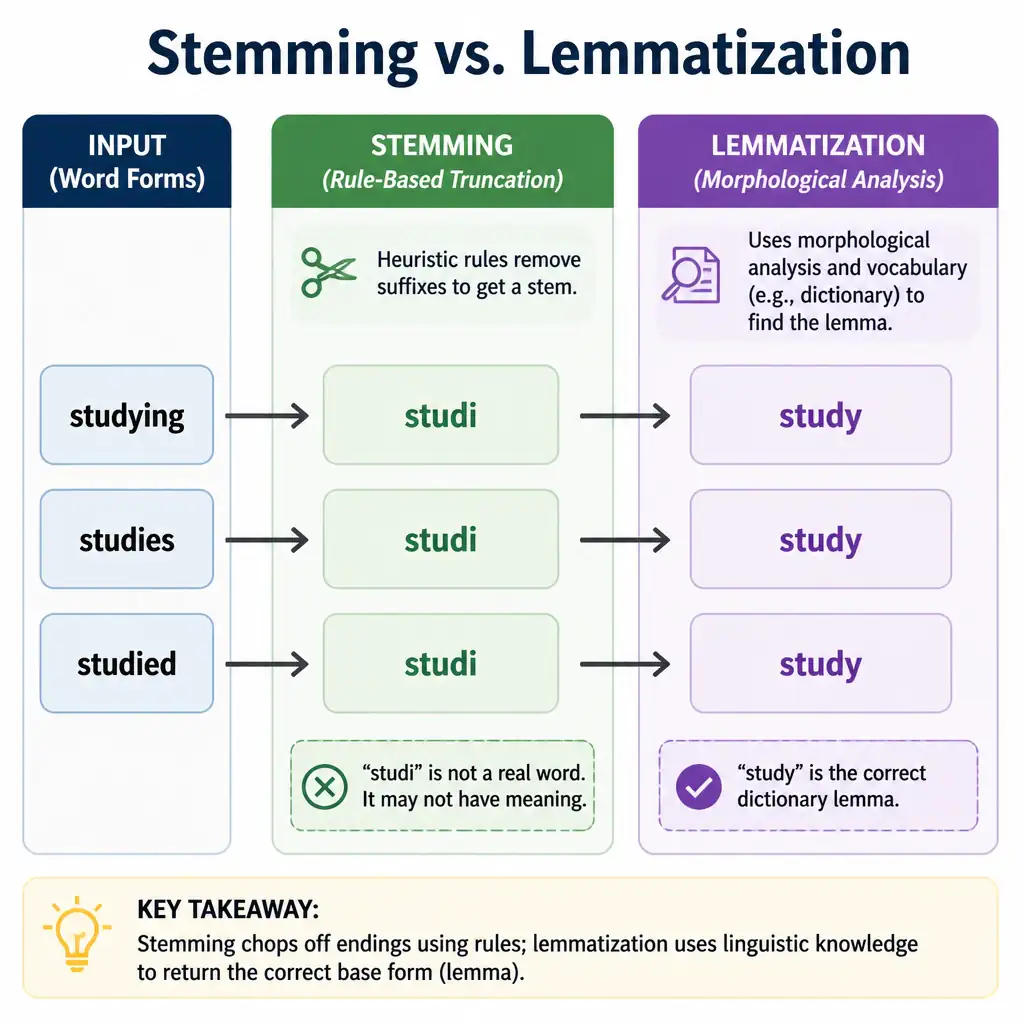
Check this out: 'runs,' 'running,' and 'ran' all point to 'run,' and you want your NLP system to know that. Stemming just hacks off endings and can leave gibberish, but lemmatization uses vocabulary and grammar to find the real dictionary form, like 'better' to 'good' or 'saw' to 'see'.
Full Explanation
Lemmatization is an essential text normalization technique in NLP. Its objective is to reduce a word to its lemma, which is its canonical, dictionary-defined base form. Unlike stemming—which applies simple, rule-based heuristics to slice off suffixes (for example, transforming 'flies' and 'flying' to 'fli' or 'fly' regardless of context)—lemmatization uses vocabulary databases (such as WordNet) and part-of-speech tagging to perform a full morphological analysis. For example, the word 'meeting' could be lemmatized to 'meet' if tagged as a verb, or remain 'meeting' if tagged as a noun. Similarly, the word 'was' is lemmatized to 'be' because it recognizes the underlying lemma of the verb.
The choice describing stripping out common filler words such as 'the' and 'is' defines stop word removal, which eliminates highly frequent words that lack unique semantic value for tasks like classification. The choice describing chopping off the ends of words using crude heuristic rules, often leaving incomplete or non-real root words, describes stemming, which is computationally faster but linguistically crude and often yields non-words. The choice describing normalizing punctuation, special characters, and casing refers to basic text cleaning processes such as lowercasing or punctuation stripping.
For the exam, make sure you distinguish between stemming (crude slicing that may create non-words) and lemmatization (linguistically accurate reduction to a dictionary form).