
Within an MLOps architecture, what is the primary role of a model registry?
Select an answer to reveal the explanation.
Short Explanation
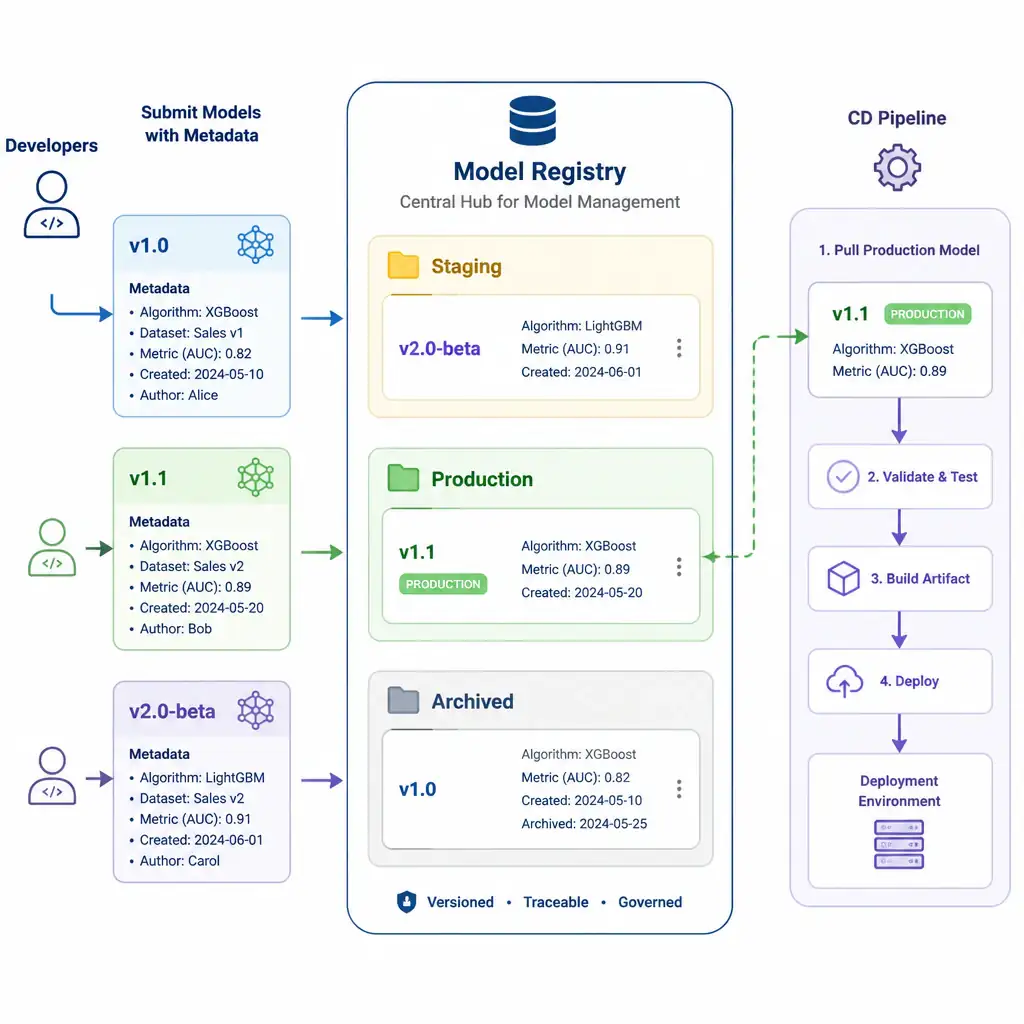
Here's the deal: a model registry is your single source of truth for trained model artifacts, storing them, cataloging them, and managing versions. It tracks which model is candidate, staging, production, or retired, so your deployment pipeline can pull the right one. If you're saving models as 'final_final.pkl' on a laptop, you're asking for trouble.
Full Explanation
In Machine Learning Operations (MLOps), a model registry is a centralized, database-backed repository designed to manage the lifecycle of machine learning models. During the development phase, data scientists train numerous models using different algorithms, features, and hyperparameters. Once a model is deemed suitable for potential deployment, it is registered in the model registry.
The model registry performs several critical functions: 1. Model Versioning: It automatically tracks versions of model artifacts, allowing teams to roll back to a previous version if a deployment fails or degrades. 2. Metadata Cataloging: It stores metadata associated with each model version, such as training parameters, evaluation metrics (e.g., accuracy, ROC-AUC), training datasets used, and who trained it. 3. Stage Management: It facilitates lifecycle transitions by labeling models with stages (e.g., 'Candidate', 'Staging', 'Production', 'Archived'). This allows CI/CD deployment pipelines to programmatically fetch the correct version (e.g., pull the latest model labeled 'Production').
Let's evaluate the incorrect choices: - The choice describing hosting models on serverless infrastructure and exposing them as web APIs for real-time inference refers to model serving or inference hosting, which is the system that executes the model to handle predictions (e.g., Triton Inference Server, TF Serving). The registry stores the model but does not serve it as an active API. - The choice about storing and versioning massive raw datasets and feature stores used during training describes data version control (DVC) or a feature store, which is designed for raw training data and feature vectors, not the trained model artifacts themselves. - The choice about monitoring production traffic and tracking live performance metrics like latency and throughput describes model monitoring and observability, which tracks metrics in production after deployment, whereas the registry is focused on asset management and versioning.